What happened
Researchers at EPFL identified a critical failure mode in large language models (LLMs) when executing long-horizon reasoning tasks—a "no-recovery bottleneck" that emerges when reasoning is decomposed into too many steps. They proposed Lookahead-Enhanced Atomic Decomposition (LEAD), which uses short-horizon future validation and overlapping rollouts to maintain stability while preserving error-correction ability. The o4-mini model using LEAD solved Checkers Jumping puzzles up to complexity n = 13, whereas extreme decomposition failed beyond n = 11.
Why it matters
Even when LLMs are given high-level strategies, they remain unstable during long-horizon execution—a core limitation for tasks requiring sustained multi-step reasoning. The no-recovery bottleneck occurs because errors on a few critical "hard" steps become irreversible due to highly non-uniform error distribution. LEAD's approach of balancing decomposition granularity with local context suggests a path toward more reliable reasoning in AI systems for complex problem-solving.
What to watch
The method demonstrates that o4-mini can now solve Checkers Jumping up to n = 13 complexity using LEAD, compared to n = 11 with extreme decomposition—a measurable improvement in the frontier of long-horizon task capability.
Summaries like this, every morning.
The core challenge in long-horizon reasoning for large language models lies in the tension between decomposition and recovery. The paper demonstrates that while breaking tasks into subtasks improves stability—a finding consistent with prior research on decomposed reasoning—pushing decomposition too far creates a new problem: errors on individual "hard" steps become locked in place, unable to be corrected by downstream processing. This occurs because the error distribution across steps is highly non-uniform; a few critical steps carry disproportionate weight. The no-recovery bottleneck is therefore not a problem of decomposition itself, but of the degree and isolation level at which decomposition is applied.
LEAD addresses this by introducing short-horizon future validation (allowing the model to look ahead within a limited scope) and by aggregating overlapping rollouts—a technique that keeps enough local context alive to enable error correction while maintaining the stabilizing benefits of step-by-step reasoning. The method strikes a middle ground: it avoids both the instability of monolithic single-stage reasoning and the rigidity of extreme decomposition. The measurable gain—solving Checkers Jumping up to n = 13 instead of n = 11—confirms that this balance yields tangible improvements in the frontier of what the o4-mini model can accomplish on controlled reasoning tasks.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
The AICX Association will host AI Agent Day 2027 on February 25 and 26, 2027, online and free with advance reg…
Anthropic shipped Claude Fable 5.2 and Claude Mythos 5.2, priced at $8/$40 per token, which put Fable 5.2 at #…
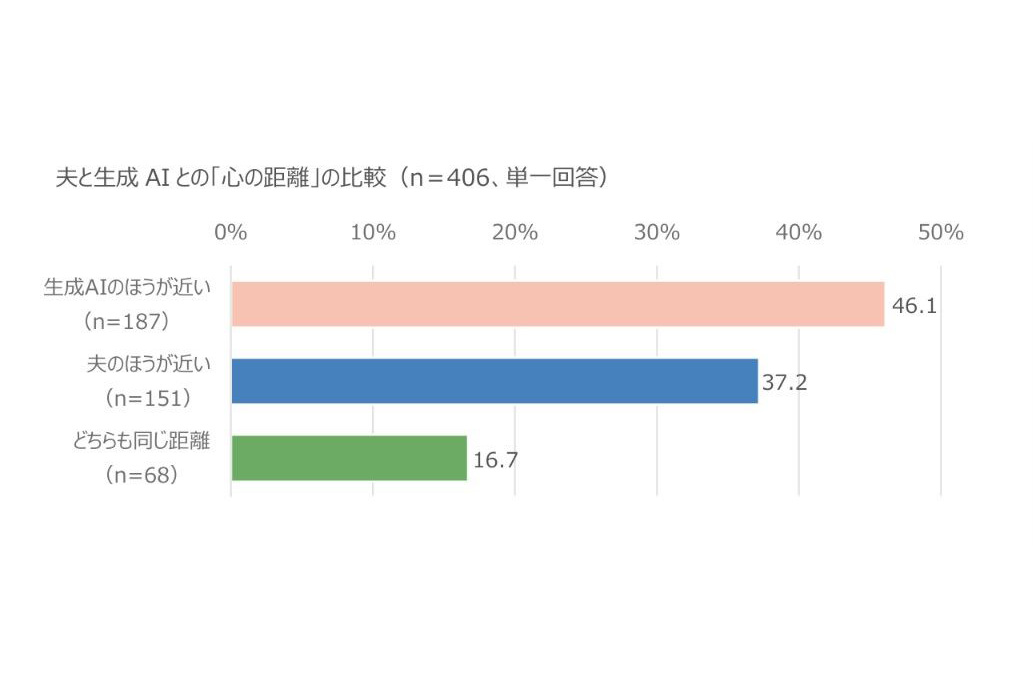
In a Nippon Life survey of 800 married women released for 11月22日 (Good Couples Day), 46.1% of the 406 generati…
Meta released Muse Ember, an efficiency-focused model for repetitive agent tasks, priced at $0.1 per 1M input…
Google DeepMind used AlphaProof Code to formally verify key cryptographic guarantees of the Signal protocol in…
Google announced two specialized AI systems, the TPU 8tx for hardware-encrypted confidential compute and the T…