What happened
Trevor Darrell's UC Berkeley team pretrained a model, then trained a specialist submodel on 100 hours of tactile data covering 200-plus household objects, and fine-tuned it on about 100 teleoperated demos.
Why it matters
On 12 complex tasks — screwing in a light bulb, applying toothpaste, transferring an egg — it averaged 65 percent success, nearly double the best VLA model, which typically ignores touch.
What to watch
Whether scale closes the gap — Fudan-linked NeoteAI already has 30,000 hours, and NeoteAI's Shunlin Lu guesses closer to 100,000 hours in real-world settings could unlock new capabilities.
WHO IT HITSRobotics research teams and startups building manipulation hardware now have evidence that tactile data plus separate high-level and tactile control submodels can roughly double success on fine-grained tasks — though results so far come from single hardware setups or proprietary sensors.
Summaries like this, every morning.
Vision-language-action models have made real progress on everyday jobs like folding laundry and tidying rooms, but they still stumble on tasks needing fine hand control — plugging in a USB cable or turning a key — because they ignore the tactile feedback humans rely on. The Berkeley work attacks that gap by pretraining on existing data first, then adding touch through a specialist submodel trained on 100 hours of demonstrations across more than 200 household objects, with a tactile expert running four times faster than the action expert so grip corrections arrive in time.
The field is also wrestling with data fragmentation. Chengbo Yuan at Tsinghua aggregated more than 3,000 hours from public datasets spanning 21 sensor types, converting each sensor's output into a shared format mapped onto a template of a human hand — an approach inspired by the Open X-Embodiment collaboration. That hardware-agnostic model beat a baseline even on hardware it had never seen, which Yuan attributes to a kind of common sense of tactile knowledge. Meanwhile USC's model infers touch from visual data alone, giving sensorless robots a rudimentary sense of touch.
Not everyone is convinced scale alone is the answer. Long Cheng of the Chinese Academy of Sciences argues tactile signals are sparse and intermittent, so models learn to ignore them; his IROS 2026 model predicts what a robot will feel from vision and amplifies only surprising mismatches, averaging 62.8% success against 28.2% without touch. The outcome now hinges on whether bigger, more diverse datasets or smarter algorithms — or both — prove decisive for truly dexterous tasks.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
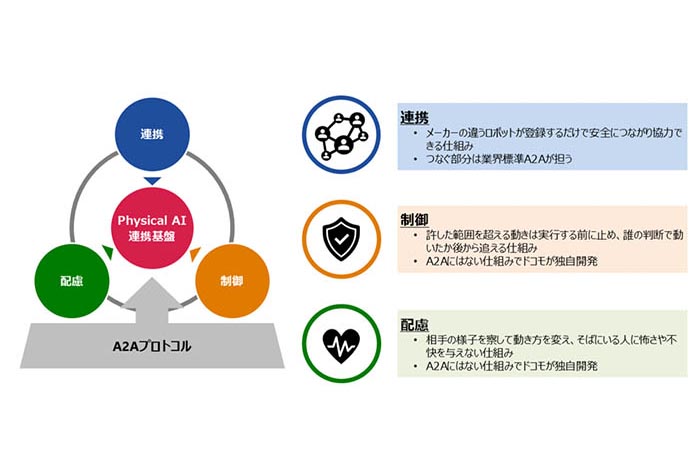
NTTドコモ announced it has developed a Physical AI連携基盤 (a linkage platform for Physical AI), positioned around a…
Google announced Genie 4, a world model that generates interactive experiences about two minutes long, up from…
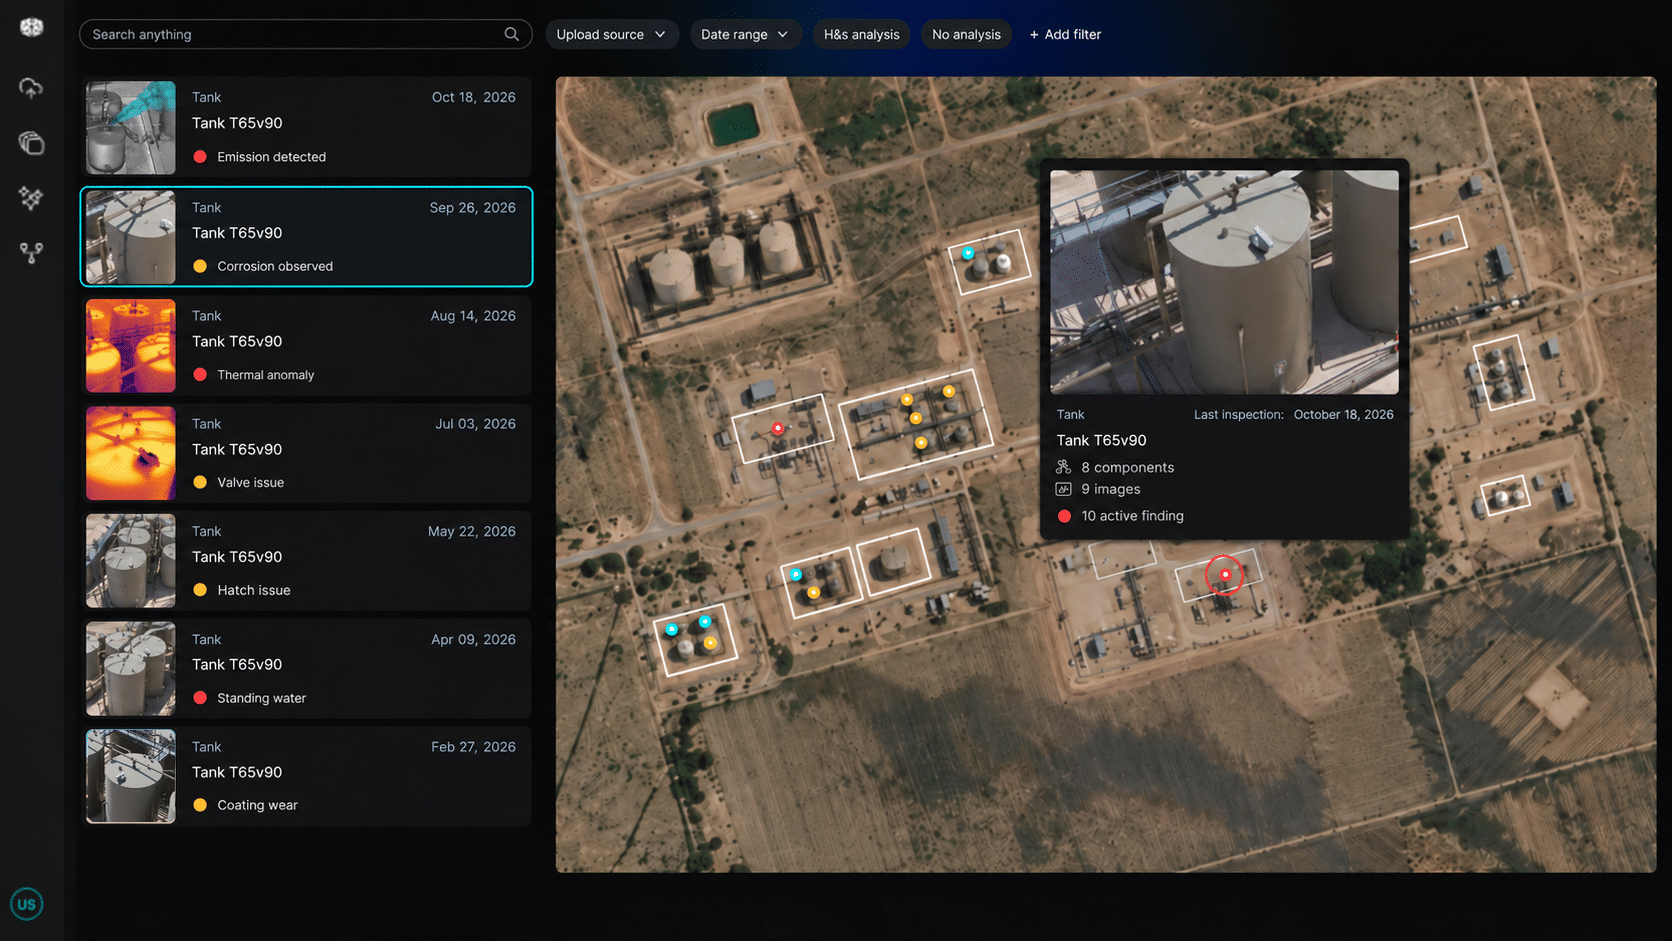
Percepto launched Axion on October 27, 2026, a SaaS platform applying more than 160 AI models trained on over…
Crunchbase data shows global robotics venture funding reached $9.9 billion in Q3, more than double the $4.3 bi…
SunTek Thermal introduced the IR-1 NX platform, which simplifies thermal imaging and onboard AI integration fo…
NTT Docomo developed "Physical AI連携基盤," which unifies linking AI agents to robots, controlling permitted actio…