What happened
Running higurashi-ai/Haru-4B (Apache-2.0) via its haru-inference CLI, the author measured 422.1–462.1ms per frame on CPU but 72.5–104.9ms per frame on an NVIDIA RTX 5060 Ti, below the model's 133ms design frame.
Why it matters
The model's full-duplex behavior was unreliable: the same input yielded silence, a reply after the user finished, or overlapping speech, so a single output can't label it as a backchannel model or an unresponsive one.
Summaries like this, every morning.
Haru-4B is designed as a full-duplex speech dialogue model: instead of waiting for the user to finish, it listens and generates its own voice and text in the same 133ms frame. The test installed the Apache-2.0 code and model directly from GitHub and ran the bundled haru-inference CLI offline, without the Hugging Face Spaces demo and without any paid API key. On the CPU-only machine, nine runs took 422.1–462.1ms per frame, and a Ryzen 7 7700 without a GPU measured 445.7ms, roughly 3.2–3.5 times slower than real time. On an NVIDIA RTX 5060 Ti, eight runs ranged from 72.5ms to 104.9ms per frame, with a PyTorch codec average of about 87.5ms and a single Triton-codec run at 72.5ms. The Web demo server loaded the model in 6.7s and warmed up at 86.1ms per frame, using about 13,592MiB of GPU memory. The full-duplex behavior itself was inconsistent: aligning output text with the user audio's RMS showed one CPU run interjecting during speech, while GPU runs in English were mostly silent or gave a single word, and GPU Japanese runs began speaking only after the user stopped. Because the same seed produced different output on GPU and CPU, judging the model from a single run would be misleading; real-time conversation through a browser microphone was not tested.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Nicalis updated The Binding of Isaac: Repentance Plus to remove AI-generated music after Reddit user ShweetsSt…
Runway released Praxis-1, a 27-billion-parameter open-weight world action model, now publicly available under…
Testing Irodori-TTS, the author found it speaks 4–7dB quieter above 4kHz than its reference (―31.9dB vs ―22.9d…
MomongaCode is out under the MIT license, a terminal AI coding agent that works with Ollama, LM Studio, and Ap…
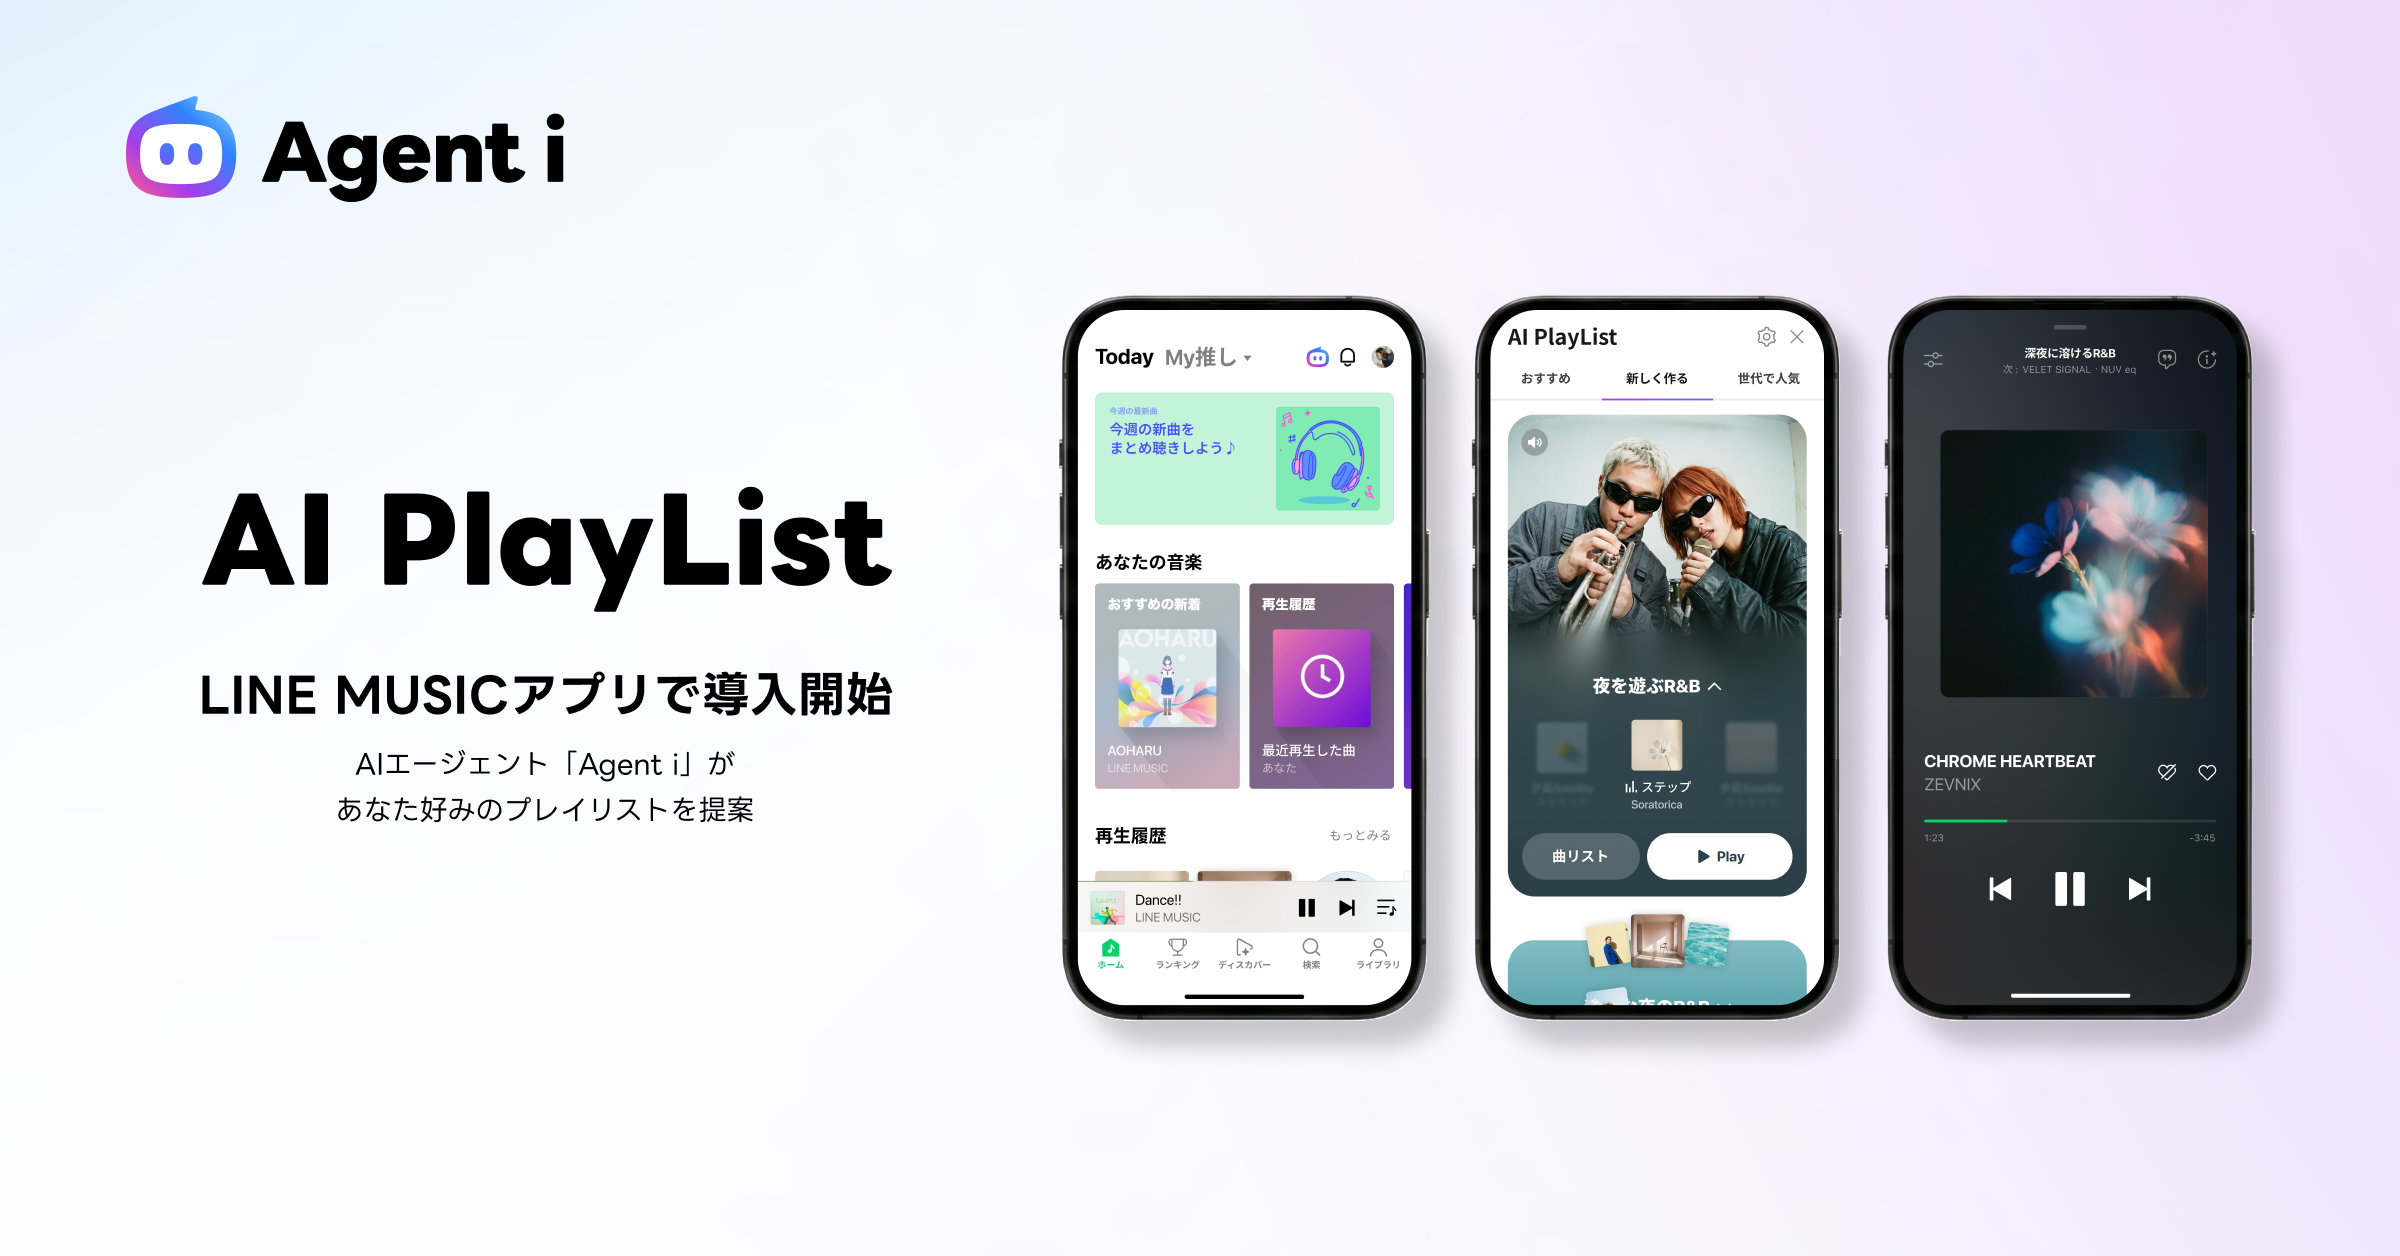
LINE MUSIC and LY Corporation's AI agent "Agent i" have introduced "AI PlayList," a feature that suggests play…
Gyro Governance Lab released AIR Office, a desktop app for AI safety research that runs agentic chat on the Mi…