What happened
Microsoft Research's Hongyu Wang and colleagues proposed DeepNet, combining DeepNorm (residual connections scaled by a constant α > 1) with a scaled-down initialization (β < 1) to train a 1000-layer Post-LN Transformer. The paper appeared in IEEE TPAMI.
Why it matters
The work identifies the cause of instability in deep Post-LN Transformers — model updates exploding in the very early stage of training, followed by almost no updates — and its proposed fix enables training a 1000-layer Transformer without problems, according to the authors' analysis.
What to watch
The paper notes the arXiv version dates from 2022; no scheduled future event is given.
WHO IT HITSAI researchers and engineers working on deep neural network training, particularly those building very deep Transformer models, gain a practically demonstrated method (DeepNorm plus scaled initialization) that enabled training a 1000-layer Post-LN Transformer.
Summaries like this, in your inbox every morning.
The paper's starting point is a concrete diagnostic: in deep Post-LN Transformers, updates blow up in the earliest part of training and then nearly cease, which the authors attribute to gradient shrinking through LayerNorm when its inputs become large, trapping the model in a poor local solution.
DeepNet's fix is structural rather than a new training trick. Each Post-LN sublayer's residual connection is scaled by α, and the FFN weights plus the attention V and output projections are initialized at β times their usual scale, with Q and K projections left at standard Xavier initialization. The authors' analysis is that where ordinary Post-LN accumulates update magnitudes on the order of the sum of parameter changes across all sublayers, DeepNet keeps them to O(1) regardless of depth. Both α and β are constants determined solely by architecture size (for an encoder-only stack of N layers, α = (2N)^{1/4} and β = (8N)^{-1/4}), not learned parameters — a detail that helps explain why the approach scales predictably.
In experiments, a 1000-layer DeepNet (500 encoder and 500 decoder layers, 2500 sublayers) trained without issues. The paper also reports a translation comparison: a 200-layer, 3.2B-parameter DeepNet trained on a bilingual corpus outperformed M2M-100 (Facebook's multilingual translation model, 48 layers and 12B parameters) in BLEU score on every multilingual translation evaluation set tested — WMT, OPUS, TED, and Flores-101.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Valuence's "Generative AI User Trends Survey" (June 2024–May 2026) tracked six services including ChatGPT, Gem…
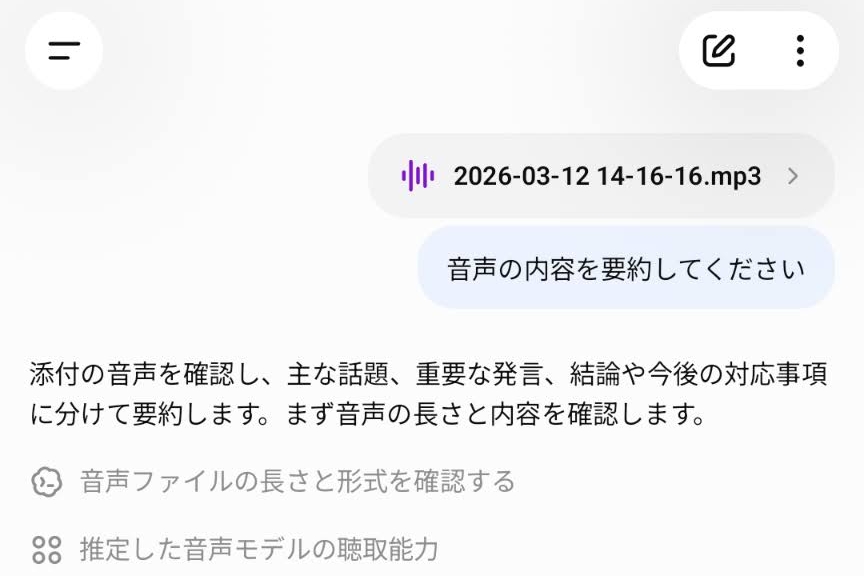
OpenAI began offering a ChatGPT feature that accepts uploaded audio files and can transcribe them, summarize t…
On a self-built 76-question Jev-format set, six trained 3B–9B open-weight models (Imajev-4B, Clef-Flash 9B, Je…
At Gemini at Work, Google introduced the Gemini agent, built into Gemini Enterprise, which gathers information…
Google released Google AI Edge Foresight, a free macOS Labs app that uses EmbeddingGemma 2 and Gemma 4 to tran…
The Association for Human Mathematics said OpenAI's release of 722 AI-generated "mathematical results" is not…