What happened
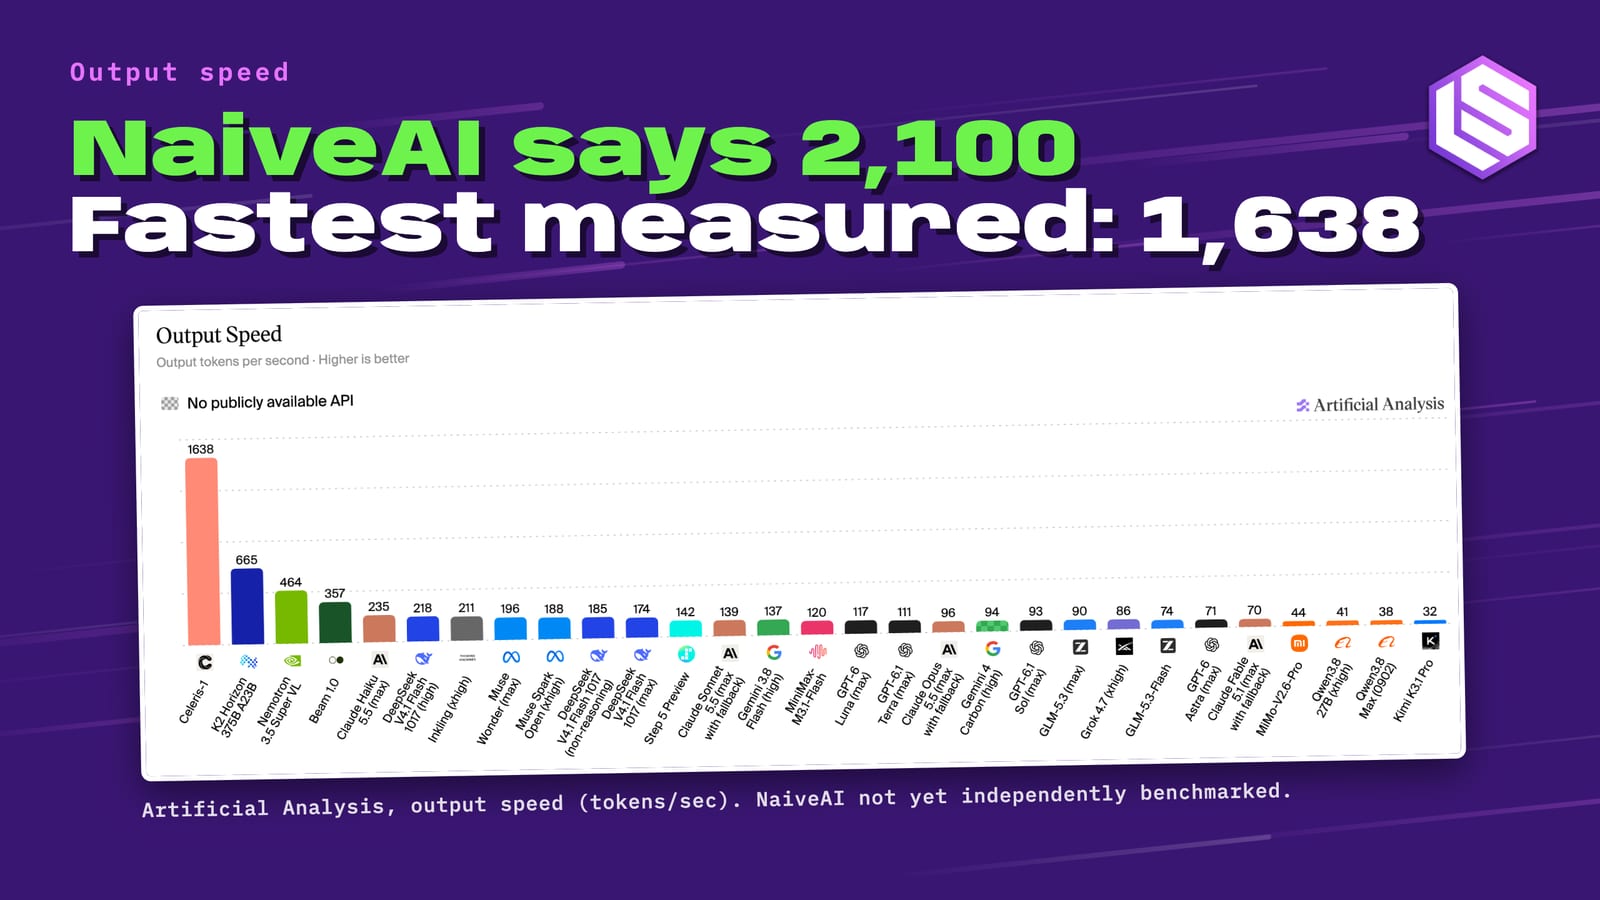
NaiveAI released Naive-N0.5-Flash, an open-weights coding model built on Xiaomi's 310B-parameter MiMo-V2.5, claiming roughly 2,000 tokens per second in ultrafast mode and nearly 1,000 during thinking-heavy tasks.
Why it matters
That speed means faster iteration for developers and AI researchers testing ideas quickly, though NaiveAI positions the model as capable and low-cost rather than a token-economy champion.
Summaries like this, every morning.
Naive-N0.5-Flash did not start from scratch: NaiveAI built it by continuing to train Xiaomi's MiMo-V2.5, a sparse Mixture-of-Experts model with 310B parameters and 15B active parameters trained on 48T tokens. The team adapted those weights to DeepSeek Sparse Attention layers through multi-stage training that took roughly 3.25T additional tokens on top of the original 48T, with about 3T of those at a fixed 1M context length and a constant learning rate.
The model's pitch extends beyond speed. NaiveAI describes it as largely built by AI and trained to do AI research itself, with recursive self-improvement as the long-term goal. In practice, the trade-off found is that Naive-N0.5-Flash takes longer to reason through harder problems, yet still delivers answers faster overall, at a slightly higher cost per question.
On app-building tests, Naive-N0.5-Flash was more consistent than GLM 5.3 Flash (high) and held its own against DeepSeek V4.1 Flash 1017, producing the most detailed solar system app and coming a close second on ray-tracer efficiency. A caution is that the speed sample was small, at 10 questions per difficulty level, and answers were not graded for accuracy.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Andre Mansour, head of AI for Wells Fargo's wealth and investment management arm, said AI Teammate launched la…
Microsoft and IBM launched Imagine Enterprise, an agentic platform with more than 6,000 pre-built AI agents fr…
Texas Instruments added an agentic AI framework to its CCStudio ecosystem, injecting device-specific knowledge…
FRAIM announced a free online webinar on November 12, 19 and 26, 2026, each day from 13:00 to 14:00, where pre…
FastMetal began offering five models on November 10, 2026: Anthropic's Claude Fable 5.2, Meta's Muse Ember, Z.…
At the Palm Beach CorpGov Forum panel "Supporting Your CFO in the AI Era," Sysdig CFO Karen Walker said ROI ca…