What happened
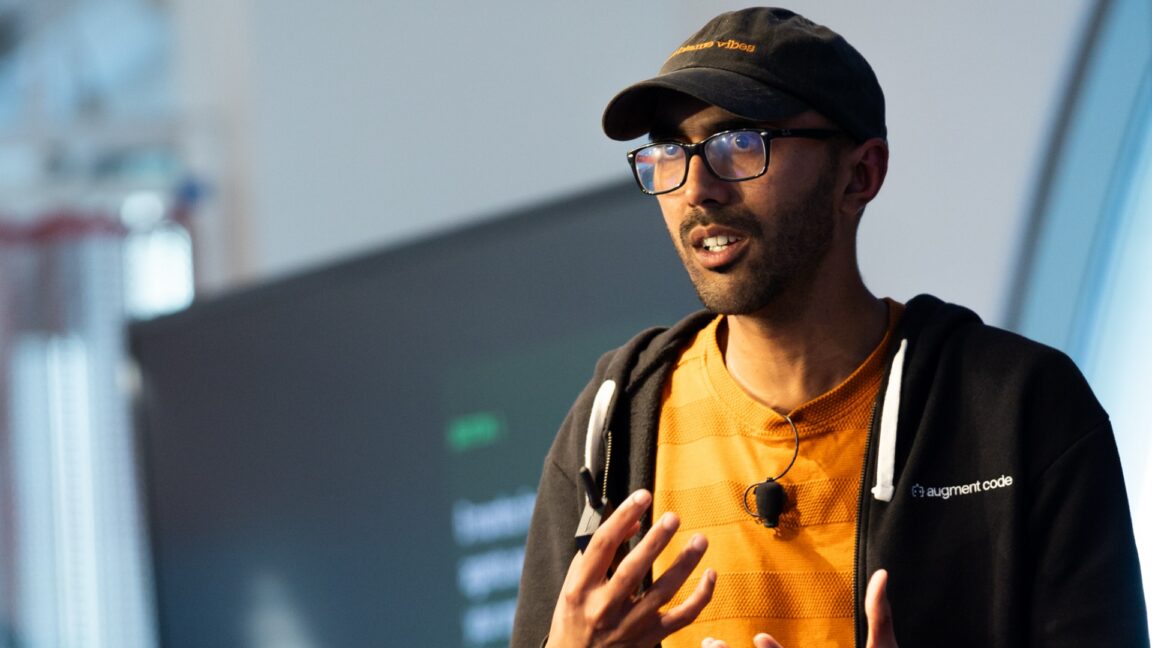
Augment Code's VP of Engineering Vinay Perneti outlined the company's approach to AI-assisted coding, which pre-indexes code repositories using embeddings and a retrieval model to surface contextually relevant code—a contrast to Claude Code's grep-based, lighter approach that avoids structured context by default.
Why it matters
In benchmarks using the same model, Augment Code achieved 33 percent greater token efficiency than Claude Code while maintaining similar accuracy, suggesting that richer context handling can reduce wasted token spending on code exploration. For development teams, especially those with large private codebases that AI models have never encountered, this design choice affects both the quality of outputs and the cost of agentic workflows.
What to watch
The debate reflects a fundamental tension in harness design: as models improve exponentially, whether to bet on the models' raw intelligence to find their own way (Claude Code's lean bet) or invest in engineering infrastructure to guide them toward the code they need (Augment Code's semantic approach). Perneti argues the answer involves both intelligence and context, framed as a systems engineering problem of balancing token efficiency against outcome quality.
Summaries like this, in your inbox every morning.
The article presents a fundamental divergence in how two leading AI coding harnesses—Claude Code (Anthropic) and Augment Code—approach the challenge of feeding code context to AI models. Claude Code, as explained by Anthropic's Cat Wu, embraces a lean harness philosophy, trusting that rapidly improving models will find their own way without structured context tools. This bet reflects confidence that model capabilities are advancing so quickly that building opinionated infrastructure carries the risk of becoming obsolete within months. Augment Code, by contrast, has invested heavily in pre-indexing and semantic retrieval infrastructure built over 18 months of research (starting from the company's founding in 2022) specifically tuned for large codebases.
Perneti's central claim is that intelligence and context are separate dimensions. A more capable model does not automatically provide better context—it still requires token budget to gather the information it needs. He frames harness design as a systems engineering problem: how to optimize both dimensions to achieve the highest-quality outcomes at the lowest token cost. His argument gains weight from the reported 33 percent token efficiency gain in benchmarks, which translates directly to reduced inference costs. However, Perneti acknowledges Anthropic's skepticism: Anthropic reports that its evals show no measurable gain from semantic code-navigation tools, suggesting either that the retrieval engines tested are not well-optimized or that the benchmarks themselves measure different things. The disagreement hinges on whether a sufficiently good retrieval system (trained specifically on code semantics) can outweigh the added complexity and engineering burden.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
ElevenLabs completed a $300 million employee tender at a $22 billion valuation, and co-founder Mati Staniszews…

On October 15, OpenAI announced the Rosalind Academic Plan, giving approved US university labs free access to…

A Qiita article compared automated red-teaming methods for LLM apps — GCG, PAIR, and TAP — using mock implemen…

Liquid AI released d1-ultra on October 15, 2026, an upgraded open-weights decision model that averaged 76.7 ac…

Circlia started a proof-of-concept for TASTE SIGNAL: visitors to Holland Village Cafe FUKUOKA taste cookies an…

In a webinar hosted by French Mathematical Society president Isabelle Gallagher, Fields Medal winner Hugo Dumi…

