What happened
DeepL unveiled Aure for DeepL Voice, which tracks both the translated words and the original audio to reflect mid-conversation shifts in tone, emotion and pace in real time.
Why it matters
Earlier models built translated audio from the voice captured at the start of a conversation, so Aure is designed to carry nuances such as urgency in a negotiation or a shift to enthusiasm into another language.
WHO IT HITSGlobal sales teams, negotiators and multilingual meeting hosts who rely on real-time voice translation may find emotional cues like urgency or enthusiasm survive the language switch, though how reliably this works in live conversation is not detailed.
Summaries like this, every morning.
DeepL's previous voice models worked from a snapshot: they captured the speaker's voice at the beginning of a conversation and generated translated audio from that baseline. Aure shifts to continuous analysis, using both the translated words and the original audio to track how delivery evolves mid-conversation. The company points to situations like a negotiation where emphasis conveys urgency, or good news delivered with a shift from a serious tone to an enthusiastic one, as cases where the added nuance matters.
To build this, DeepL combined multiple learning methods that separate a speaker's distinctive vocal traits, intonation and rhythm from the content of what is said. It then used reinforcement learning to optimize the output, aiming to keep translation accuracy and audio quality while producing natural speech that does not favor a particular accent.
The rollout is designed to be invisible to users: Aure applies automatically across DeepL Voice for Online Meetings, DeepL Voice for In-Person Conversations and DeepL API for Voice, with no extra setup. Support currently covers 8 languages — English, German, Spanish, French, Italian, Japanese, Portuguese and Korean — with expansion planned.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Anker Japan started taking orders on the 12th for the Anker Soundcore Work for Notta, pairing the Soundcore Wo…
The guide says name errors enter at two stages — speech recognition swaps terms for similar everyday words (e.…
For an 80-second animation, the author generated 89 images with Animagine XL 4.0, added motion and subtitles i…
A Zenn essay on real-time voice agents argues that when AI handles phone calls, the decisive factor is time-to…
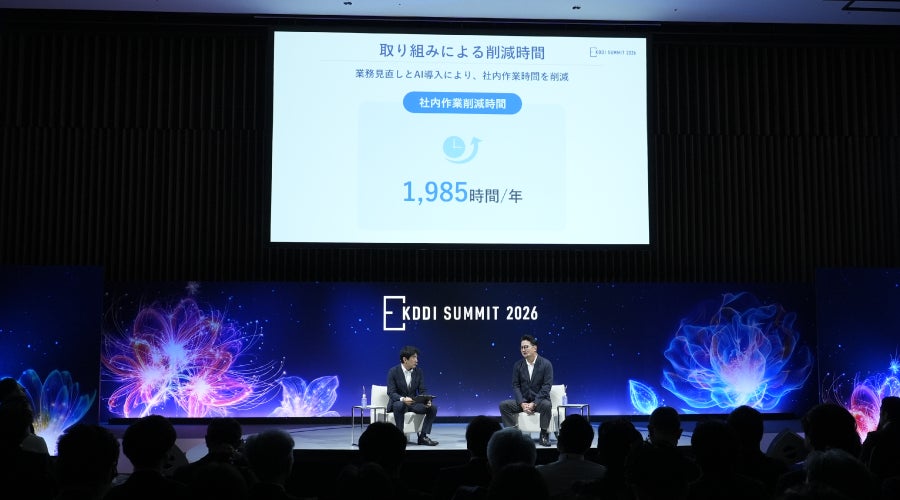
At KDDI SUMMIT 2026, Altius Link said an in-house trade-document AI tool built with Mitsui & Co.'s logistics D…
The write-up compares a few-line Python L−R implementation that subtracts the right channel from the left with…