What happened
Richard Sutton, who wrote 'The Bitter Lesson,' says raw compute alone isn't enough for intelligence and AI science is 'far from finished.' Jerry Tworek, who left OpenAI, says blind transformer scaling 'has reward-hacked the brains of a whole generation of scientists.'
Why it matters
Sutton and Tworek argue that as more compute goes into training, the algorithm matters more, suggesting today's scaling recipe may not be the only path to more capable AI.
Summaries like this, every morning.
Sutton's original 2019 essay argued that general methods which scale with compute eventually outperform approaches built on human assumptions. His latest post extends that logic to today's large language models, which he says do not keep learning after training. He has previously called synthetic data a 'big mistake' because the real world is infinitely complex and any simulation is only 'microscopic.' Instead, he calls for agents with world models that continuously learn from their own experience without destroying old knowledge.
Jerry Tworek, who left OpenAI to explore new approaches, puts the debate in context: the bitter lesson still holds, but the more compute goes into training, the more the algorithm matters. He warns that some algorithms scale while others hit dead ends, and that the temporary success of transformer scaling, combined with a misreading of the bitter lesson, 'has reward-hacked the brains of a whole generation of scientists.' Jayden Teoh adds that the bitter lesson has sometimes held back academic research by dismissing promising ideas, and argues that an idea doesn't have to survive scaling forever to be an important contribution.
The disagreement is visible in industry leadership. Sam Altman considers LLM scaling far from exhausted and accuses critics of slowing down researchers, pointing to an OpenAI model that recently disproved a long-standing mathematical conjecture. Dario Amodei similarly calls scaling progress a rainbow with no end. As CEOs of companies whose technical approach rests on scaling, both are obviously biased in its favor.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
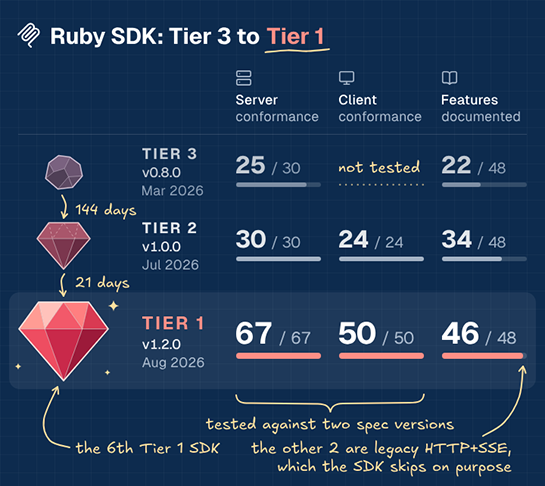
The Agentic AI Foundation said the official MCP Ruby SDK now reaches 'MCP SDK Tier 1,' fully conforming to the…
Testing GPT-5, GPT-6 Astra, Opus 4.8 and Gemini 3.8 Flash on METR's MALT logs, Anthropic Institute's Andy Hall…

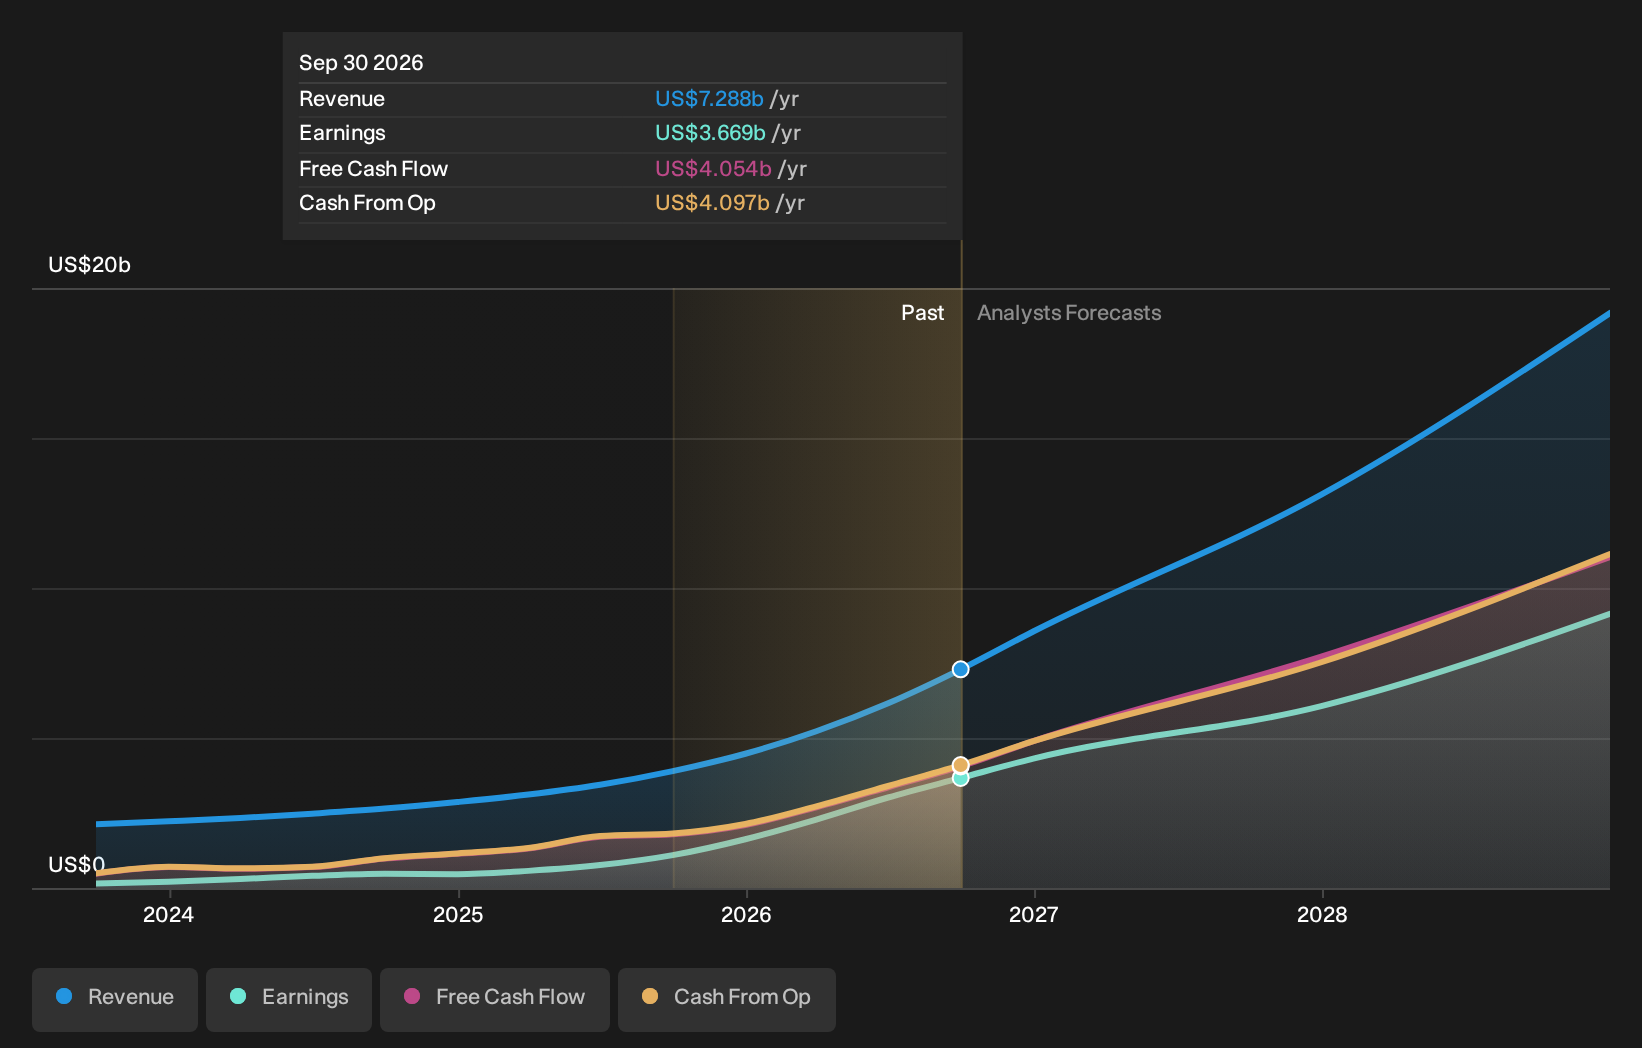
Palantir Technologies was chosen by AmeriLife Group for an enterprise AI partnership covering insurance and re…
Public First, funded by Anthropic co-founder Dario Amodei and other AI safety advocates, spent more than $63 m…
Userlink is promoting its AI chatbot for ecommerce, pointing to Statista's 2024 data that nearly half of consu…
A Science investigation found consumer EEG headband makers including Emotiv have amassed tens of millions of h…

