What happened
Running agent-cost directly on the same Claude Code session finished in 36.454 seconds, but the pre-fix AgentCostTelemetryAdapter stopped it at 30.019 seconds with a default 30_000ms timeout and only a "Command failed" message.
Why it matters
A completed measurement that takes longer than the caller's timeout gets killed before it finishes, so a slow-but-working job can look like a failure rather than a result. The diagnostic message gave no signal that the timeout was the cause rather than agent-cost itself or the input data.
Summaries like this, in your inbox every morning.
The investigation began when a session's cost record simply was not there. Running agent-cost directly on that same Claude Code session succeeded and took 36.454 seconds, while the pre-fix AgentCostTelemetryAdapter failed at 30.019 seconds. The adapter's default timeout was 30_000ms, so it killed a process that needed roughly six more seconds. The error message said only "Command failed", giving no indication that a timeout had occurred or that agent-cost itself might be at fault.
The fix in spec-lane v0.10.1 raises the default to 180_000ms and exposes the setting through a CLI option, with a new message that reports the timeout and SIGTERM. A re-run with a different session completed in 38.01 seconds and produced a CalibrationObservation and a cost_ledger entry, with emit-metrics reporting coverage.status=complete. The author notes this proves the measurement finished and was stored, but not that the estimated cost, the pricing catalog, or the task attribution are correct.
A separate concern is that usage-import can return exit 0 while recording measurement-incomplete and matched: false without writing to the ledger. The author's takeaway is that "measurement failed" and "cost was zero" are different states, and that collapsing them into one value makes it impossible to tell later whether a cost was truly zero or never measured.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
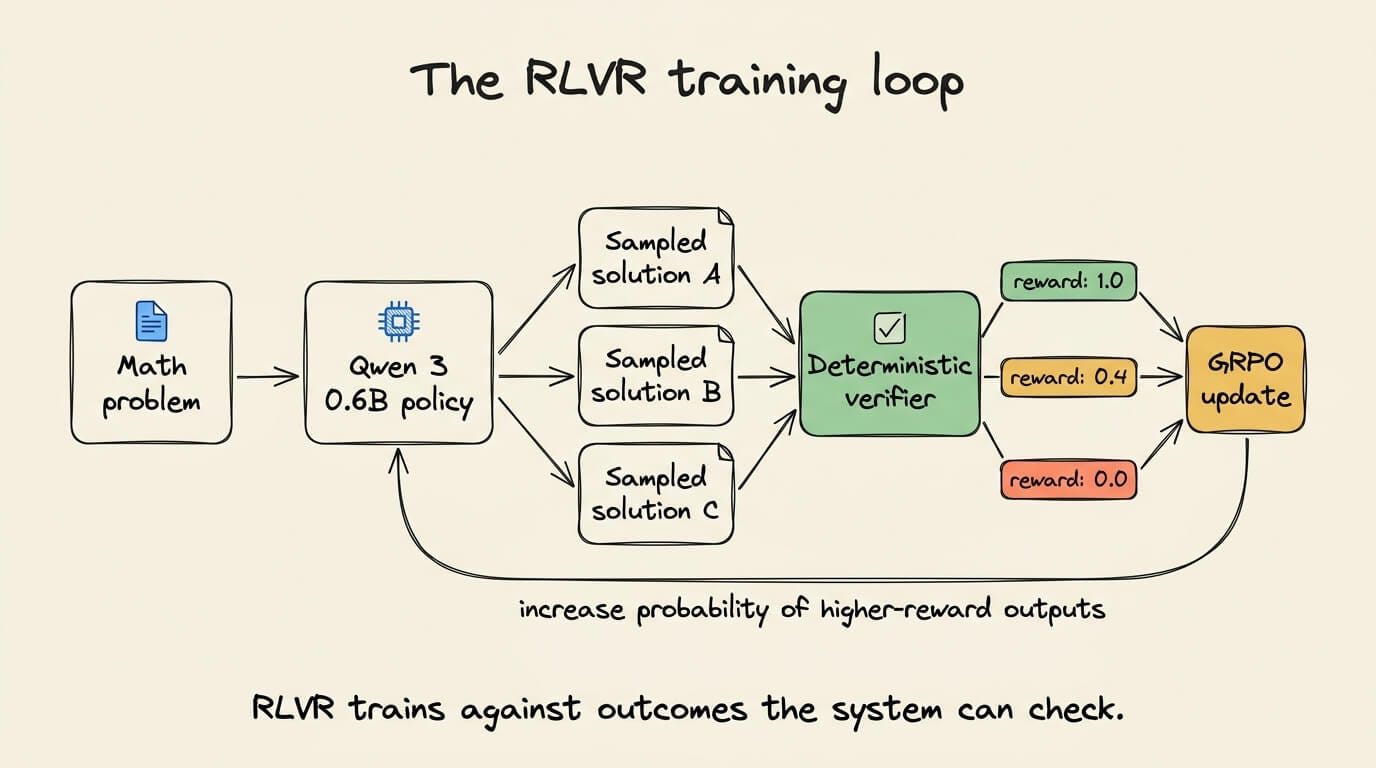
A walkthrough uses a custom four-signal reward (correctness 0.6, parseability 0.2, format 0.1, reasoning 0.1)…
A Zenn write-up on PlanGate argues you should split Claude Code or Codex sessions at work boundaries, not at u…
Anthropic's Claude Code 2.1.294 fixed natural-language prompt and agent hooks that were allowing operations th…
CEO Brian Chesky said Airbnb is now an "AI-native company." As of Q1 2026, about 60% of engineer-produced code…
WIRED's Boone Ashworth used Google Labs' newly launched Playground to build three games in one day, including…
Vals AI tested GPT-6 Sol and Claude Opus 5.5 on the Vibe Code Bench, solo and as teams, at medium and maximum…