A LessWrong post flags that the Gemini 4 safety report, on page 114, says some RL training components observe thoughts as context to reward reasoning on track to good outputs, and cites Kaufmann et al. (2026) to call such auxiliary rewards low-risk.
Summaries like this, every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Andre Mansour, head of AI for Wells Fargo's wealth and investment management arm, said AI Teammate launched la…
Microsoft and IBM launched Imagine Enterprise, an agentic platform with more than 6,000 pre-built AI agents fr…
Texas Instruments added an agentic AI framework to its CCStudio ecosystem, injecting device-specific knowledge…
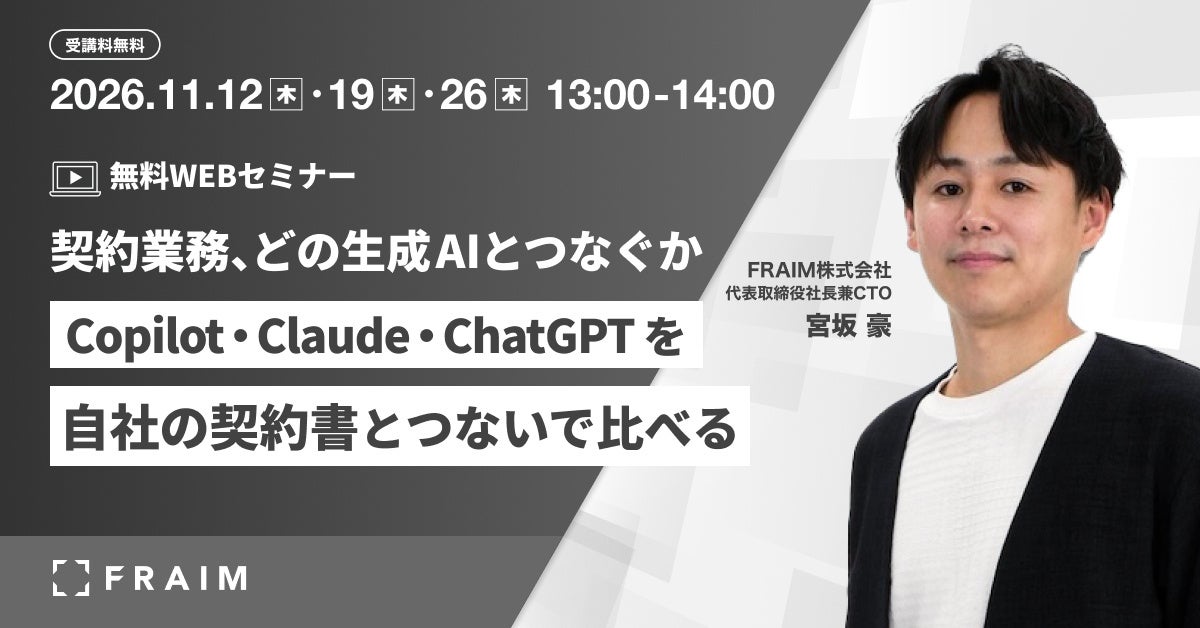
FRAIM announced a free online webinar on November 12, 19 and 26, 2026, each day from 13:00 to 14:00, where pre…
FastMetal began offering five models on November 10, 2026: Anthropic's Claude Fable 5.2, Meta's Muse Ember, Z.…
At the Palm Beach CorpGov Forum panel "Supporting Your CFO in the AI Era," Sysdig CFO Karen Walker said ROI ca…