What happened
The author installed FFmpeg and openai-whisper, ran the medium model on a meeting.m4a file with Japanese specified, and got .txt, .srt, .tsv and .json outputs.
Why it matters
Whisper does not separate speakers, so the transcript is a draft; people must fix proper nouns, owners and deadlines by hand, which is viewed as safer than automatic speaker labels.
Summaries like this, every morning.
The walkthrough is built around a practical division of labor rather than full automation. Whisper produces a timestamped transcript, and the author's sample minutes template — with sections for decisions, discussion summary and action items listing owner and deadline — shows where the human step begins. The author stresses that company terms, abbreviations and katakana words are especially error-prone and should be checked against meeting materials and the attendee list.
On accuracy, the author's own testing found that recording conditions mattered more than file conversion. Converting audio to mono 16kHz with FFmpeg did not reliably improve results, while placing the microphone closer to speakers and reducing simultaneous talking helped more. An initial prompt describing the meeting's context can stabilize spelling of technical terms, though it does not guarantee any specific word is recognized.
The local setup also carries a data-handling angle. Running Whisper on your own PC is presented as a valid option for sensitive recordings, with the caveat that where files and transcripts are stored, backed up and who can access them must be checked separately, and deleting recordings afterward should follow company or team rules.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
At NVIDIA's Agentic AI Day Japan 2026 on Nov 10 in Tokyo, JAIST's Shota Imai predicted competitive areas will…
Irene Solaiman, chief policy officer at Hugging Face, said on the Equity podcast that the permissive, data-ric…
ai& launched Meta's first open-weight Muse model, Muse Spark Open (meta/muse-spark-open), on its ai& Inference…
NVIDIA published Nemotron Personas Finance Japan and Nemotron PII Japan on Hugging Face, built with cooperatio…
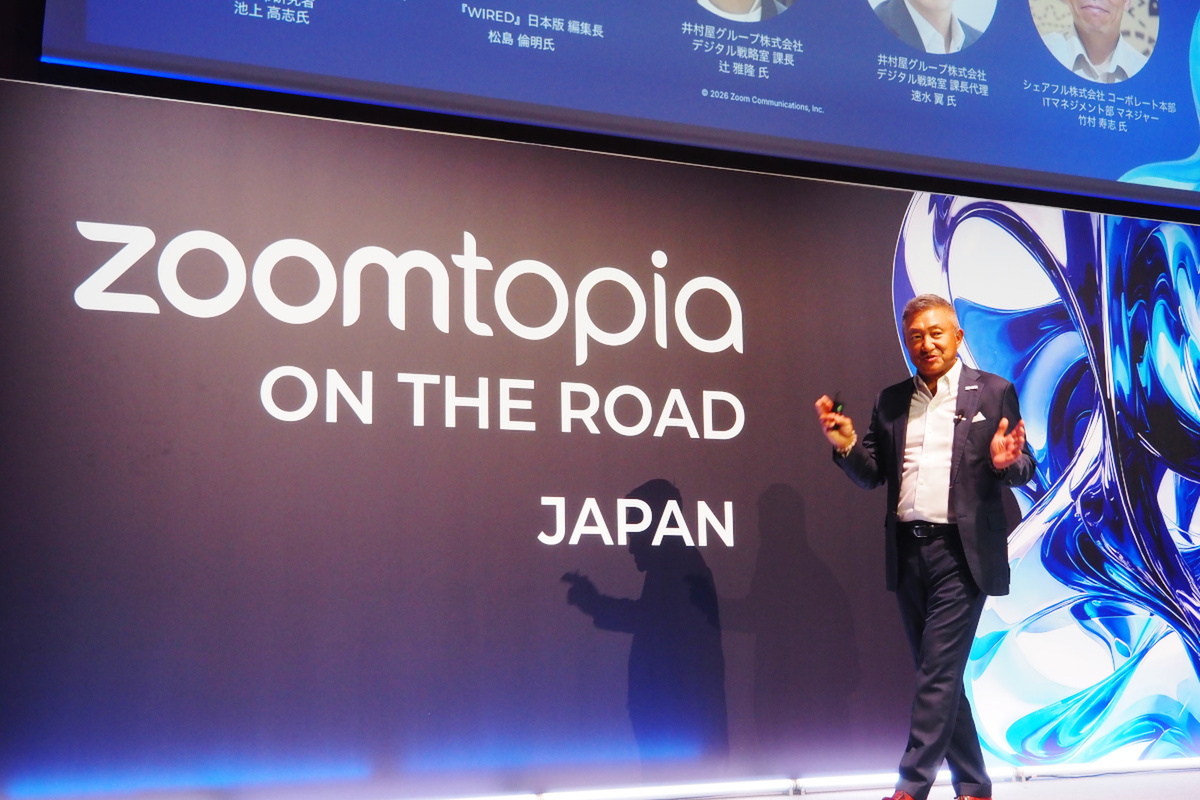
At Zoomtopia ON THE ROAD 2026 JAPAN, CTO Xuedong Huang said Zoom's multi-model "federated AI" approach ranked…
NVIDIA introduced GR00T 2, an open world action model trained on 100,000 hours of egocentric data