What happened
NVIDIA's Nemotron 3.5 Super VL, a 120B-parameter model with 12B active parameters and up to 1M-token context, is now available in Amazon SageMaker JumpStart in NVFP4 and BF16 variants.
Why it matters
The NVFP4 variant is the JumpStart default and closely matches the BF16 reference weights on multimodal benchmarks, so teams can pick a lighter-weight deployment without a major quality trade-off, according to NVIDIA's model cards.
WHO IT HITSEnterprise AI teams building document-intelligence, GUI-navigation, and video-understanding agents can now deploy this vision-language model through SageMaker JumpStart, choosing NVFP4 for optimized inference on G7 instances or BF16 for customization.
Summaries like this, every morning.
NVIDIA Nemotron 3.5 Super VL is the vision-language member of the Nemotron 3.5 family, built for agentic workloads that must read and see. Its language backbone interleaves Mamba-2 and Mixture-of-Experts layers, initialized from Nemotron 3 Super Base and distilled from Nemotron 3 Ultra Base, while a C-RADIO vision encoder maps images and sampled video frames into the language model's embedding space. Training moved from continued pre-training through multimodal supervised fine-tuning, reinforcement learning with verifiable rewards and human feedback, multi-teacher on-policy distillation, and a final stage for the Multi-Token Prediction head.
The two JumpStart variants serve different needs. NVFP4 runs on G7 instances with NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs and a checkpoint of about 75 GB, while BF16 requires ml.p5en.48xlarge with NVIDIA H200 GPUs and about 249 GB. NVIDIA's model cards report that NVFP4 matches BF16 on MMLongBench-Doc and stays within about one point on other multimodal benchmarks, scoring slightly higher on OCRBench v2 and OSWorld-Verified. That narrow gap may make the lighter NVFP4 default attractive for inference-heavy deployments where GPU footprint matters.
Inference performance measured on JumpStart showed mean output throughput of 63.07 tokens per second per request on ml.g7.24xlarge with NVFP4 and 140.85 tokens per second on ml.p5en.48xlarge with BF16, though AWS notes these run on different GPU systems and are not an isolated precision comparison. Time to first token stayed around half a second across configurations, but longer prompts change the picture: with the summarize profile of 10,000 input tokens, time to first token on ml.g7.24xlarge is 12.62 seconds. Teams weighing deployment choices will need to match the variant and serving configuration to their prompt lengths and latency targets.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
IBM plans to bring Anthropic's Claude Mythos cyber reasoning into IBM Concert Protect, combining AI code scann…
PKSHA Technology CEO Katsuya Uenoyama said after 14 years of AI deployments at over 4,800 companies, replaceme…
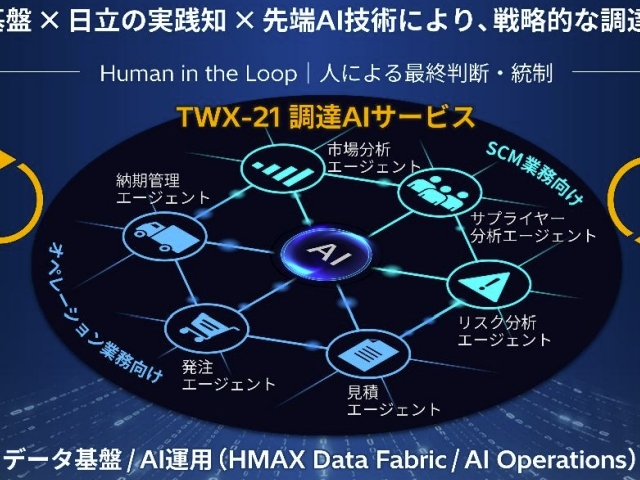
Hitachi released "TWX-21 調達 AI サービス" on 11月9日, sold under its HMAX Industry brand within the TWX-21 business-t…
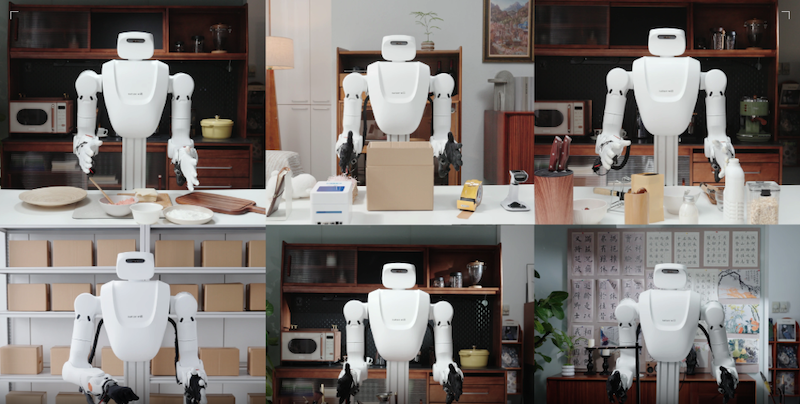
Nature Will announced Natura-1, a 50-billion-parameter mixture-of-experts model trained on over 1 million hour…
Meta introduced Muse Ember, its smallest and most efficient AI model, priced at $0.10 per million input tokens…
OpenAI listed ChatGPT Enterprise on AWS Marketplace on November 9, 2026, so organizations can discover, buy an…