What happened
Across five stages, YuNet + SFace scored 5/5 in 9.94 seconds; Jev was fastest at 3.81 seconds but scored 1/5; Claude Opus 5.5 scored 4/5 in 51.22 seconds; Clef scored 0/5 in 18.36 seconds.
Why it matters
Splitting the job into face detection and face matching appears to have beaten models asked to answer with coordinates directly, suggesting how a task is broken down can matter as much as raw model capability.
Summaries like this, every morning.
The experiment grew out of a Qiita post in which Jev found a Waldo-style character in 0.4 seconds, prompting this spin-off that swapped the target for a real person's face. Rather than pitting raw models head-to-head, the author assembled four different search systems — Jev via its Box feature, Clef through coordinate choices, Claude Opus 5.5 answering from images, and OpenCV's YuNet plus SFace — and ran them on the same reference image and five stage images.
The most striking contrast is not speed but method. YuNet + SFace first detects faces, then compares each candidate to a reference image, a two-step split. The general-purpose models were asked to return a location straight from the image. The author notes this may be why the face-specific pipeline did well, while cautioning that if YuNet fails to detect a face, SFace cannot pick it. Similarly, Clef's 0/5 is tied to the coordinate-choice output format used here, not proof of weak image understanding.
Timing also deserves care: Jev's 3.81 seconds and YuNet + SFace's 9.94 seconds include API communication and model loading, so they are not pure inference speeds. The author's takeaway is that for face-finding, matching the decomposition of the problem to the tool may matter more than picking the newest general model.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Visa launched its Agentic Commerce Benchmark, a framework to evaluate AI-powered shopping experiences for cons…
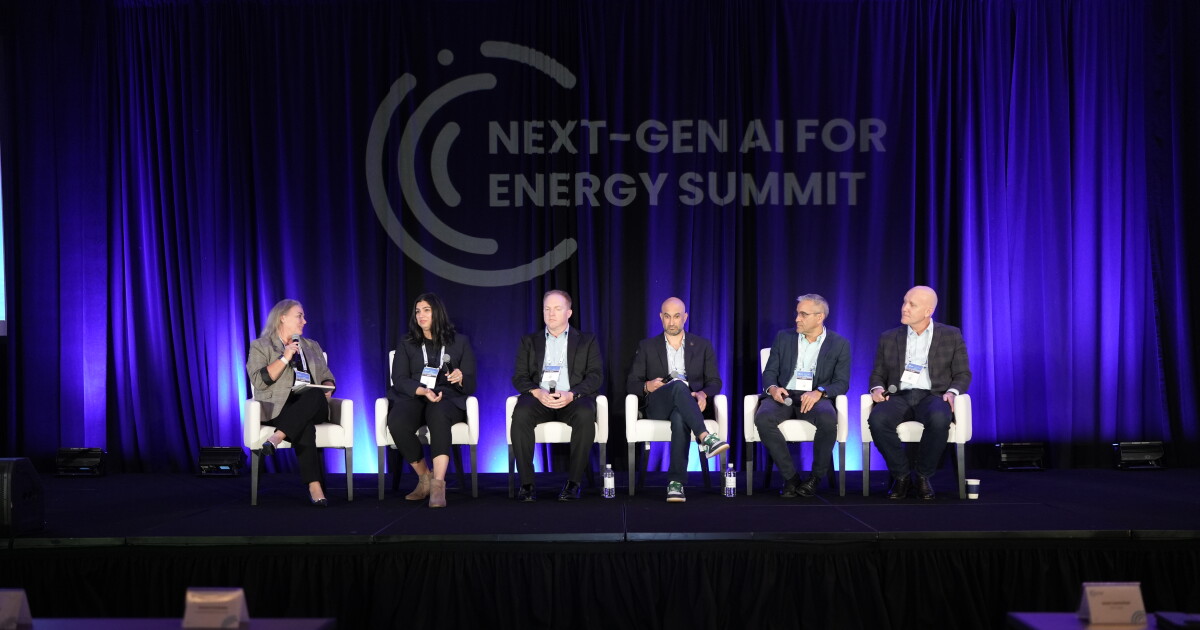
At the Next-Gen AI for Energy Summit in Houston on 3 November, Anthropic's Boaz Nur said AI will take over the…
Visa's Agentic Commerce Benchmark tested 22 AI models from 12 labs on shopping tasks like buying a TV or lapto…
Salesforce agreed to acquire Cresta, adding voice agents, real-time agent assistance, and conversation intelli…
In May 2026, SMFG said it will invest 100 billion yen in generative AI over three years, expanding a 50 billio…
The Japan enterprise agentic AI market was valued at $149.6 million in 2025 and is projected to grow at a 46.9…