What happened
IBM released Granite Speech 5.0 2B, a 2-billion-parameter open-source model trained on 390,000 hours of public audio, ranking #2 among public models with a 5.06% average word error rate on IBM's English test.
Why it matters
The model handles six languages, up to 2,000 user-specified keywords for names and technical terms, and improved translation, so meetings with jargon and noisy recordings become easier to transcribe accurately.
WHO IT HITSEnterprise IT teams and developers building meeting transcription, subtitle, and call-center tools can now self-host these models commercially under Apache 2.0, while teams recording noisy or multi-speaker audio get a higher-accuracy option.
Summaries like this, in your inbox every morning.
IBM's update splits the Granite Speech family into three purpose-built models rather than one general-purpose system. The flagship Granite Speech 5.0 2B keeps the previous model's 2-billion-parameter size but was trained on 390,000 hours of public audio, and IBM is emphasizing robustness to noise and reverberation — conditions that trip up transcription in real meeting rooms and factory floors. A new keyword feature lets users pre-register up to 2,000 terms, aimed at the common failure where names, product names, and acronyms are misheard.
The lightweight Granite Speech 5.0 470M Turbo CTC moves from English-only to seven languages including Japanese, adds automatic punctuation and English capitalization, and runs about 1.6 times faster, which IBM frames around on-device transcription. Separately, the Granite Speech 4.1 2B Plus targets multi-speaker recordings, with speaker-identification error down about 7% and long-audio transcription error down 24% — improvements that matter for subtitling and searching recorded conversations.
Because all three ship under Apache 2.0, companies can deploy and modify them commercially without a proprietary license, which may make them an attractive option for organizations that want speech tools running on their own infrastructure rather than through a cloud API.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
NVIDIA added five models to Nemotron Retriever and released them free as open models
SafeDep found malicious files in all seven packages of LiteLLM 1.107.0, published on PyPI on October 21, 2026…
Anthropic used Claude to analyze 25 open-source projects (over 5 million lines) and found 493 issues, includin…
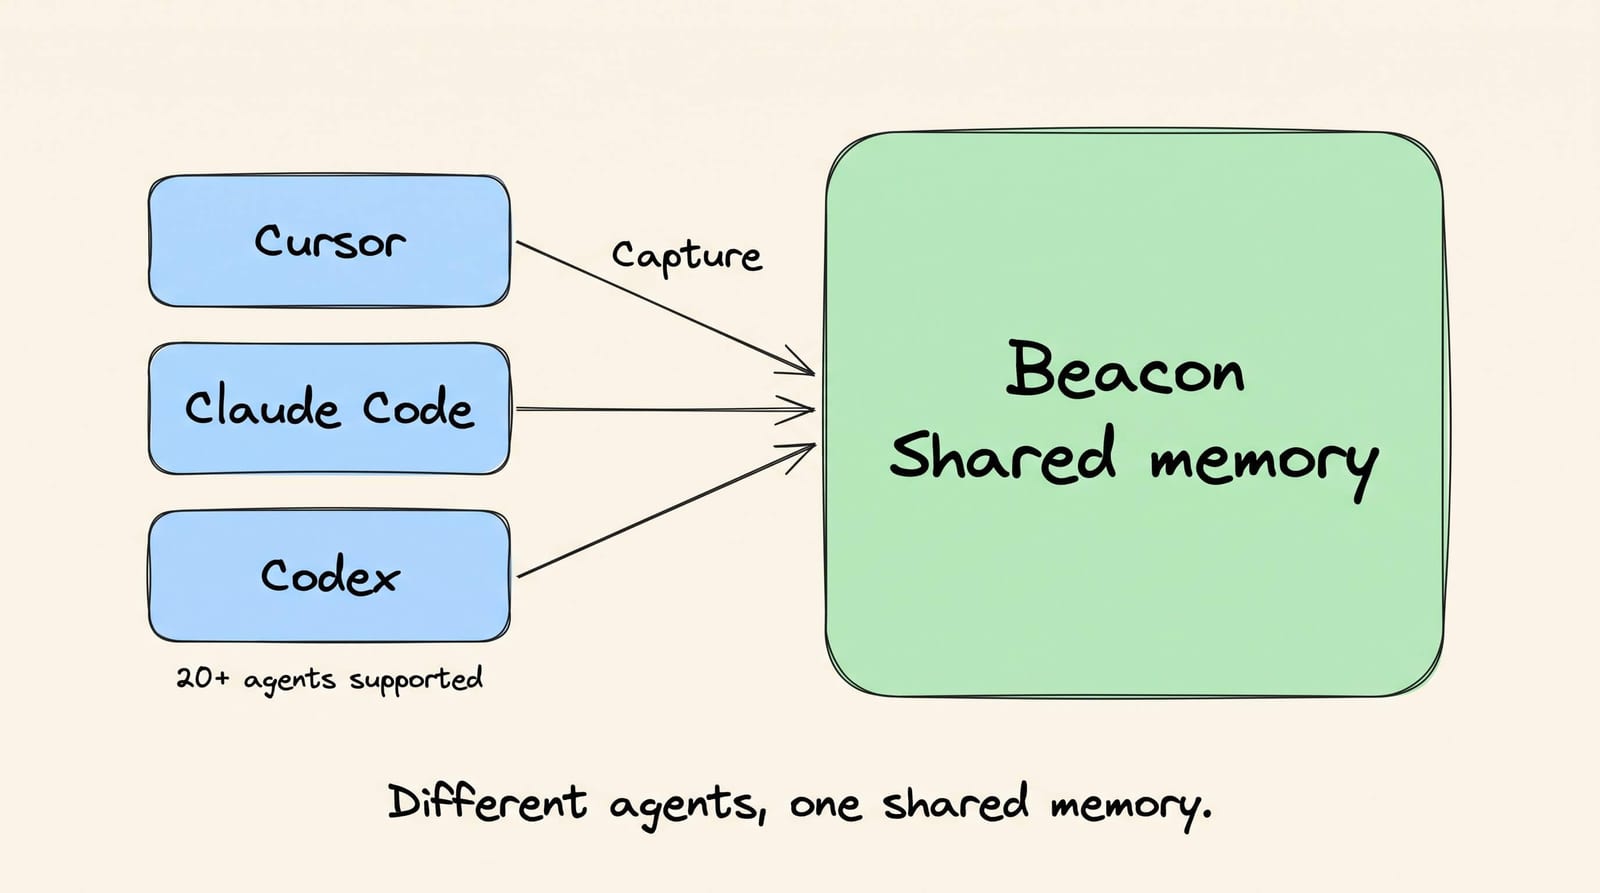
Asymptote Labs' Justin showed Beacon, an open-source layer that captures prompts, tool calls and file changes…
Hugging Face CEO publicly criticized Netflix's AI hack documentary, saying it gets the story wrong
AWS walked through training Qwen3 three ways on one trn2.48xlarge — via Hugging Face Transformers v5, torchtit…