What happened
NVIDIA added five models to Nemotron Retriever and released them free as open models. Nemotron-3.5-Embed-8B-BF16 handles 34 languages including Japanese plus image and text input, and beat Qwen3-VL-Embedding-8B and EmbeddingGemma-2 on embedding benchmarks.
Why it matters
The benchmarks position these models as fast and accurate alternatives to competing embedding models, with the smaller variants showing performance close to larger rivals. That may make self-hosted retrieval setups cheaper to run, though NVIDIA's own presentation of the results is the main evidence offered.
WHO IT HITSEnterprise teams building self-hosted search and document-processing pipelines get a free, open set of models they can download and run themselves, rather than paying a vendor API.
Summaries like this, in your inbox every morning.
NVIDIA is extending its Nemotron Retriever line, which is already aimed at retrieval-augmented generation, with five new models spanning embedding, reranking and PDF parsing. The company put its benchmark comparisons front and center: the 8B embedding model is shown above Qwen3-VL-Embedding-8B and EmbeddingGemma-2, and the 1B models are shown tracking closely to Qwen3-VL-Embedding-8B despite their smaller size.
NVIDIA also highlights the trade-off between speed, accuracy and cost. Graphs in the post plot processing speed against accuracy and per-query cost against accuracy, with the three embedding models shown as fast and accurate relative to competitors. It says pairing Nemotron-3.5-Embed-8B-BF16 with Nemotron-3.5-Rerank-8B-BF16 cuts cost while improving accuracy.
On the parsing side, Nemotron-3.5-Parse is presented as both accurate and fast, with its pages-per-second rate standing out in NVIDIA's comparison. The release is free and open, so organizations can evaluate these claims on their own document workloads rather than take the charts at face value.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Schneider Electric, Nvidia and HPE formed a strategic collaboration to launch Industrial AI Agents at the Edge…
Anthropic released Claude Duet, built on Claude Opus 5.5
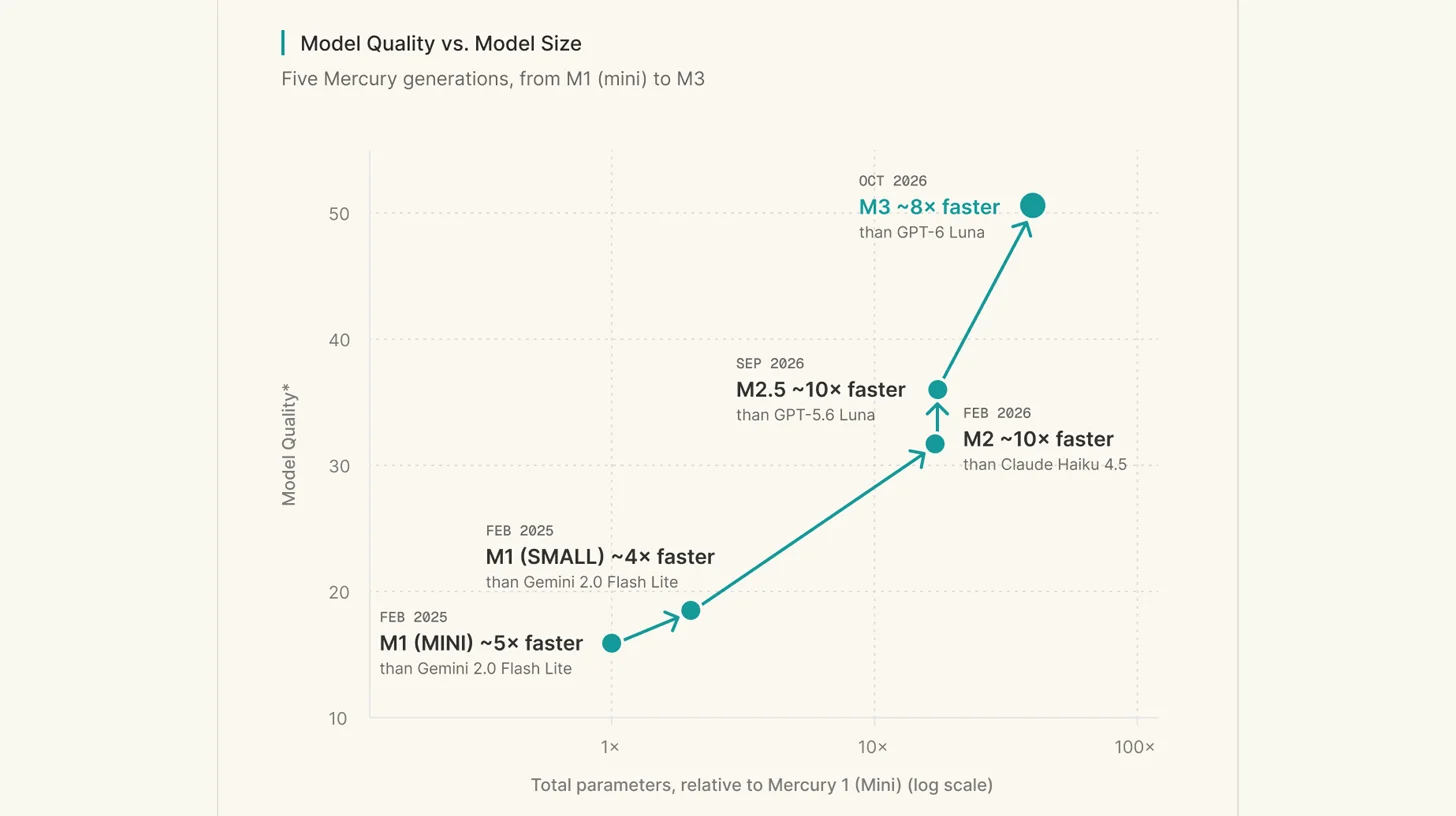
Inception launched Mercury 3 on October 19, a diffusion model it says generates 1,068 output tokens per second…
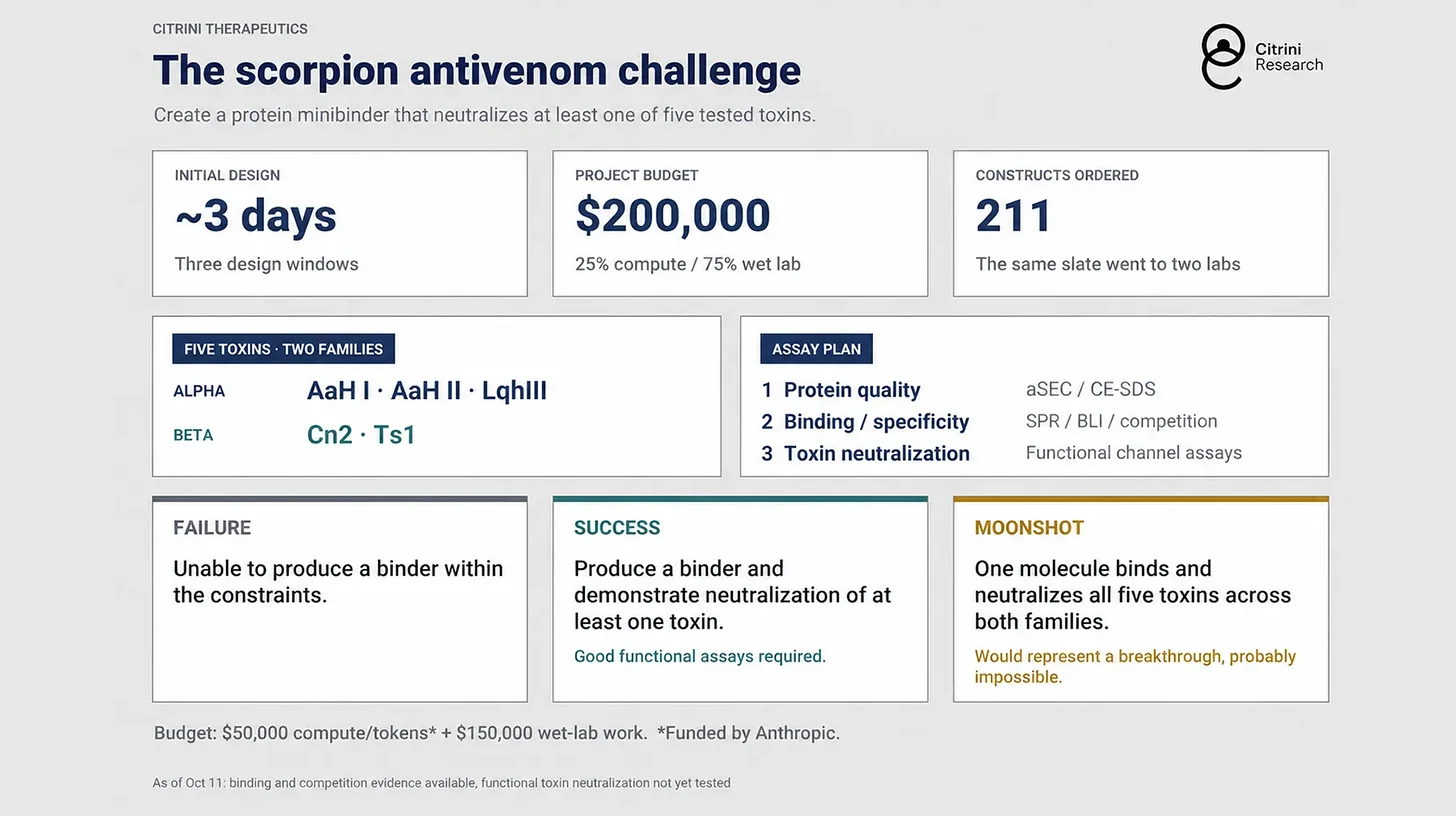
Anthropic reported that an internal version of Claude generated 318,484 candidates over a 64-hour run and sele…
NTT Data and NTT Data Tokai will start a joint proof-of-concept with Aichi Bank on October 26, testing a conve…
WD measured that an 8-second AI video (a 3.97MB 720p file for the user) generated more than 500MB of back-end…