
What happened
He, Zhang, Ren and Sun at Microsoft Research showed that making each block learn only a residual $F(x) = H(x) - x$ and adding the input back at the output removes the degradation problem; a 34-layer ResNet beat its plain counterpart by 2.8 points top-1, and a 152-layer version won ILSVRC 2015.
Why it matters
Without any extra parameters on the shortcut, deeper models stopped getting worse and started getting better, so teams could add depth to improve accuracy rather than fighting a training failure that had nothing to do with overfitting.
Summaries like this, in your inbox every morning.
The paper starts from a puzzle that had been building since AlexNet in 2012: stacking more layers kept improving accuracy, but past a certain depth the training error itself got worse. That is odd because a deeper network can always imitate a shallower one by making the added layers pass their input through unchanged. The authors argued the obstacle was optimization, not representation — stochastic gradient descent struggled to find those identity weights when they had to be built from scratch through nonlinear layers.
The fix reframes what each block has to learn. Rather than produce the target output directly, the weighted layers produce only the correction, and the input travels down a shortcut to be added at the end. If the best thing for a block is to do nothing, the weights only need to shrink toward zero, which is far easier than shaping a random matrix into the identity. The authors describe this as preconditioning the problem — changing its form so it is easier to solve.
The experiments hold everything else fixed to make the point. A 34-layer plain network has the same parameter count and compute as a 34-layer ResNet, differing only in the shortcuts, and the ResNet wins by 2.8 points top-1 on ImageNet while its training error also falls. Comparisons of shortcut variants (zero-padding, 1×1 projection only where dimensions change, projection everywhere) came out within a few tenths of a point, which the authors read as evidence that the extra parameters are not what fixes degradation. Later work picked up the thread: a follow-up moved normalization and activation ahead of the weights so the shortcut path stays a clean identity, and separate researchers found that removing individual blocks from a trained ResNet barely hurts accuracy, suggesting the network behaves partly like an ensemble of shorter paths.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
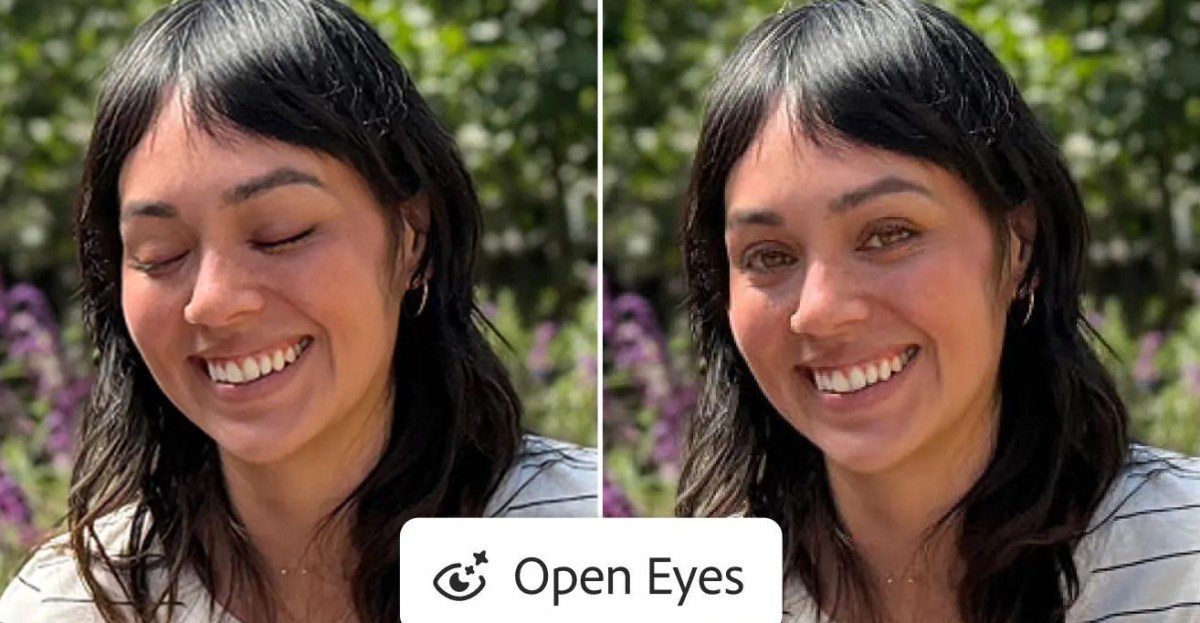
Adobe says Lightroom mobile on iOS, iPadOS and Android now offers an Open Eyes Quick Action — a one-tap, gener…
EURO, a PM at Toonkit, published a guide based on the team's Style LoRA training guide covering dataset choice…
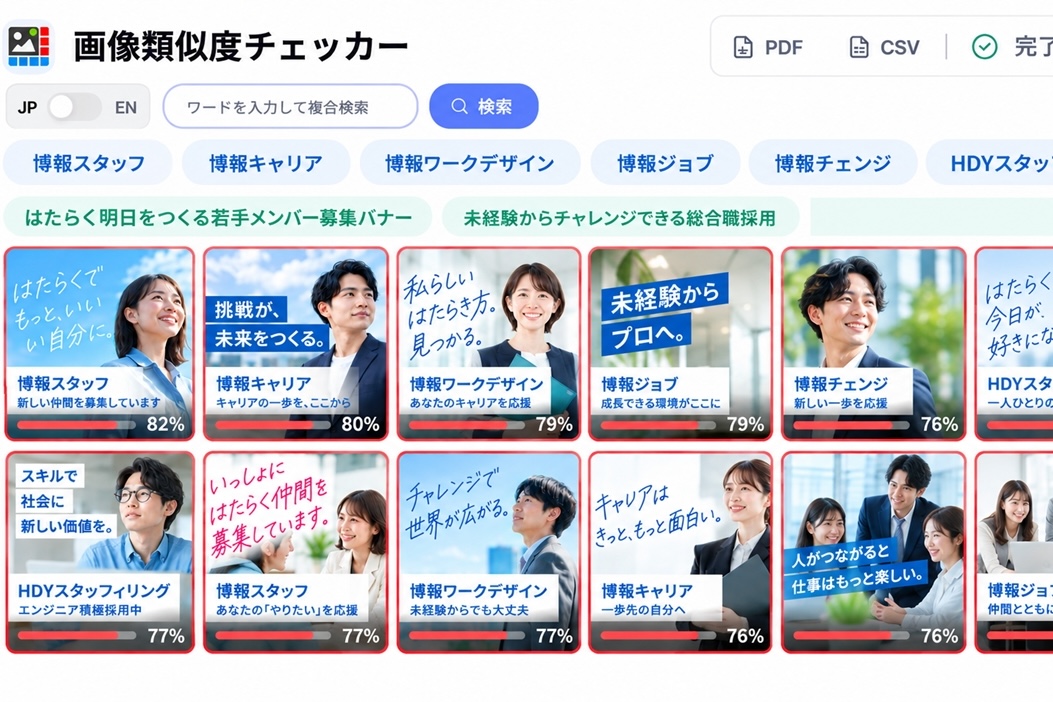
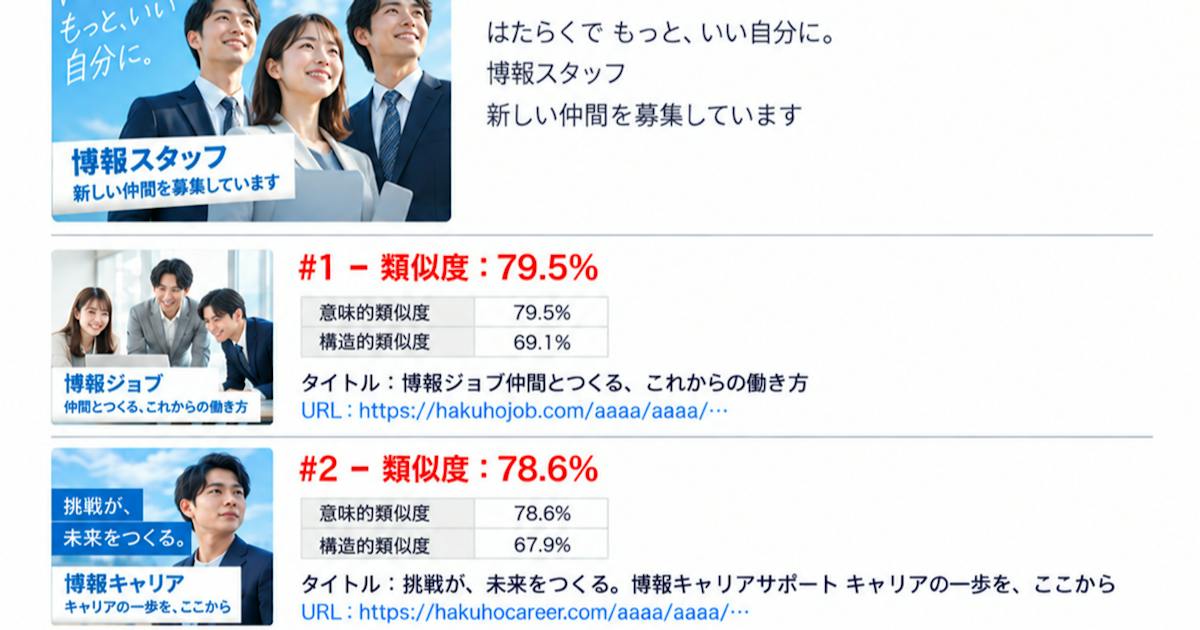
Hakuhodo began offering its "Image Similarity Checker" to client companies on October 19, automatically search…
In a 10-question test of Jev 1.14 against OpenAI's Decisions API (gpt-6-luna), both got every answer right

On October 19, Hakuhodo said it will offer its 画像類似度チェッカー to companies, automatically detecting and displaying…
The author found that simulating each pleat as cloth is overkill, since painted folds with AI shading now look…

