What happened
Futurum's report, sponsored by QumulusAI Inc., finds agentic AI can drive token consumption per task 10 to 100 times higher than a simple inference call. It forecasts agent and reasoning inference will grow 219% this year, and total inference spending will rise from $120 billion in 2025 to $885 billion by 2030.
Why it matters
The report quantifies a real cost problem that chief information officers and chief financial officers have reported with increasing frequency, according to the article.
What to watch
The risk isn't just a high bill; unpredictable bills can kill useful projects, and some customers abandoned internally built automation tools because they couldn't forecast or justify the costs, per the report. Futurum recommends reserved bare metal for sustained workloads with predictable utilization above roughly 60%.
WHO IT HITSEnterprise IT and finance teams running production AI workloads are most affected, since agentic AI can use 10 to 100 times more tokens per task than a simple inference call. The report warns that unpredictable bills can cause organizations to abandon successful projects, so IT and finance leaders may need to measure cost per task rather than cost per token.
Summaries like this, in your inbox every morning.
The Futurum report, "The Off Ramp From Per-Token Pricing," was sponsored by neocloud provider QumulusAI Inc. and arrives as enterprises are already shifting how they buy AI compute. According to Futurum's survey of 824 AI decision-makers, reserved and owned infrastructure account for 66% of AI compute consumption, compared with 19% for on-demand cloud, and 59% of respondents primarily run AI workloads outside hyperscaler public clouds, in their own data centers, colocation facilities, or with bare-metal providers.
The report also notes that the offramp works well for open-weight models a company can deploy on infrastructure it controls, which is why Amberd.ai built on private, open-source large language models. But many enterprises have standardized on frontier models available only through their developers' application programming interfaces or hyperscaler marketplaces. For those workloads, no bare-metal alternative exists, so the pricing lever rests with the model provider.
Whether the offramp pays off may hinge on operational skills, since reserved infrastructure only saves money if it stays busy. The report acknowledges that these environments require more custom engineering, limiting the operating margin gains for teams without the hardware expertise. Enterprises that lack deep bench strength in serving engines, batching, quantization and key-value cache management may find the offramp leads to a different kind of cost overrun.
For example, today's edition would include:
AI-summarized, only the topics you pick: one digest a day via Email, LINE, or Slack.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
1Password CTO Nancy Wang said at Okta's Oktane event that agents need just-in-time, task-based access, and the…
Bhakti Pitre, ServiceNow's VP of AI platform security product, said at Okta's Oktane event that agent "kill sw…
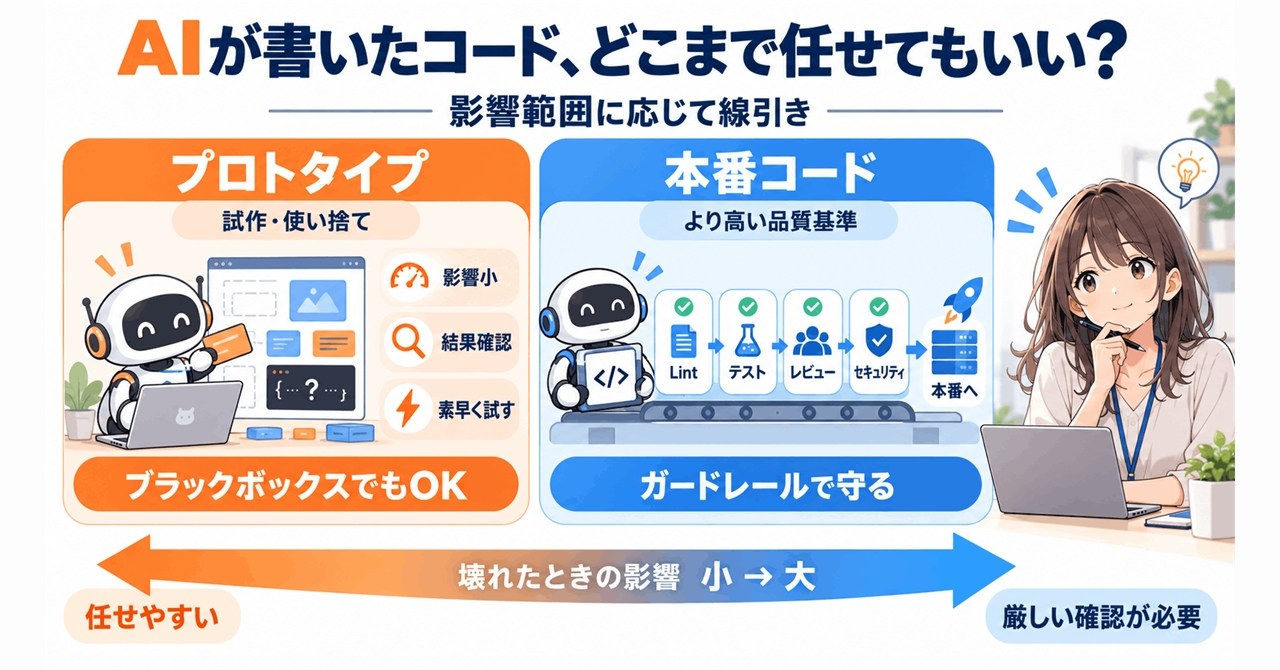
Claude Code's creator Boris Cherny answered a developer's question on September 11, 2026, saying throwaway pro…
ITR principal analyst Hiroaki Koumoto said Japanese firms' efforts in harness engineering are 'almost nonexist…
Stagwell CEO Mark Penn told Power Players most digital ads "are not very good" and said AI's payoff is doing t…
AMD agreed to an $8.2 billion all-stock buyout of World Labs, the San Francisco startup led by Dr