
What happened
Summarizing the same 14 saved articles, Haiku 5.5 missed the core claim in 4 of 13 cases twice running, while Opus 5.5 managed 13/13 and 12/13; fabricated figures and quotes were 0 under every condition.
Why it matters
A fact-checking script can only confirm what a summary says, so a missing core claim leaves no signal a reader could notice — and even Opus 5.5 missed one core claim, suggesting silent omission is not purely a cheap-model problem.
Summaries like this, in your inbox every morning.
The test was set up to isolate the model itself, not the retrieval pipeline. Fourteen web articles were fetched and saved on 10/9, and the identical files were fed to every condition, so differences could not come from CAPTCHA or timeouts changing what each model read.
A line is drawn between two kinds of summary failure. A factual error can be caught by checking what is written against the source. A missing core claim cannot be caught that way, because nothing about it appears in the summary for a checker to compare. The plain-prompt Haiku summaries passed the factual check at full marks in the top row of the comparison table while still dropping the central point in 4 of 13 cases — the failure sits outside the net.
Retrieval limits behaved differently. Opus 5.5, left with the plain prompt, wrote about missing images, truncated bodies, and CAPTCHAs in only 3–4 out of 10 articles, showing that gap is not unique to cheaper models. The prompt step closed both gaps at once, pushing Haiku's core-claim score to 13/13 and both models' retrieval-limit score to 9–10/10. An example was the GPT-6 announcement, where the plain Haiku summary listed every product detail correctly but never mentioned the closing line about software adapting to people; the stepped version put that line at the top and flagged that the interactive UI examples in the fetched text were labeled GPT-5.6 Instant.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
DeepSeek released DeepSeek-V4.1-Flash-1017, a “minor update” that reduces task execution time and output lengt…
NEC's Kei Noguchi described how employee engagement fell to 19%, with 8 in 10 staff saying they wanted to leav…
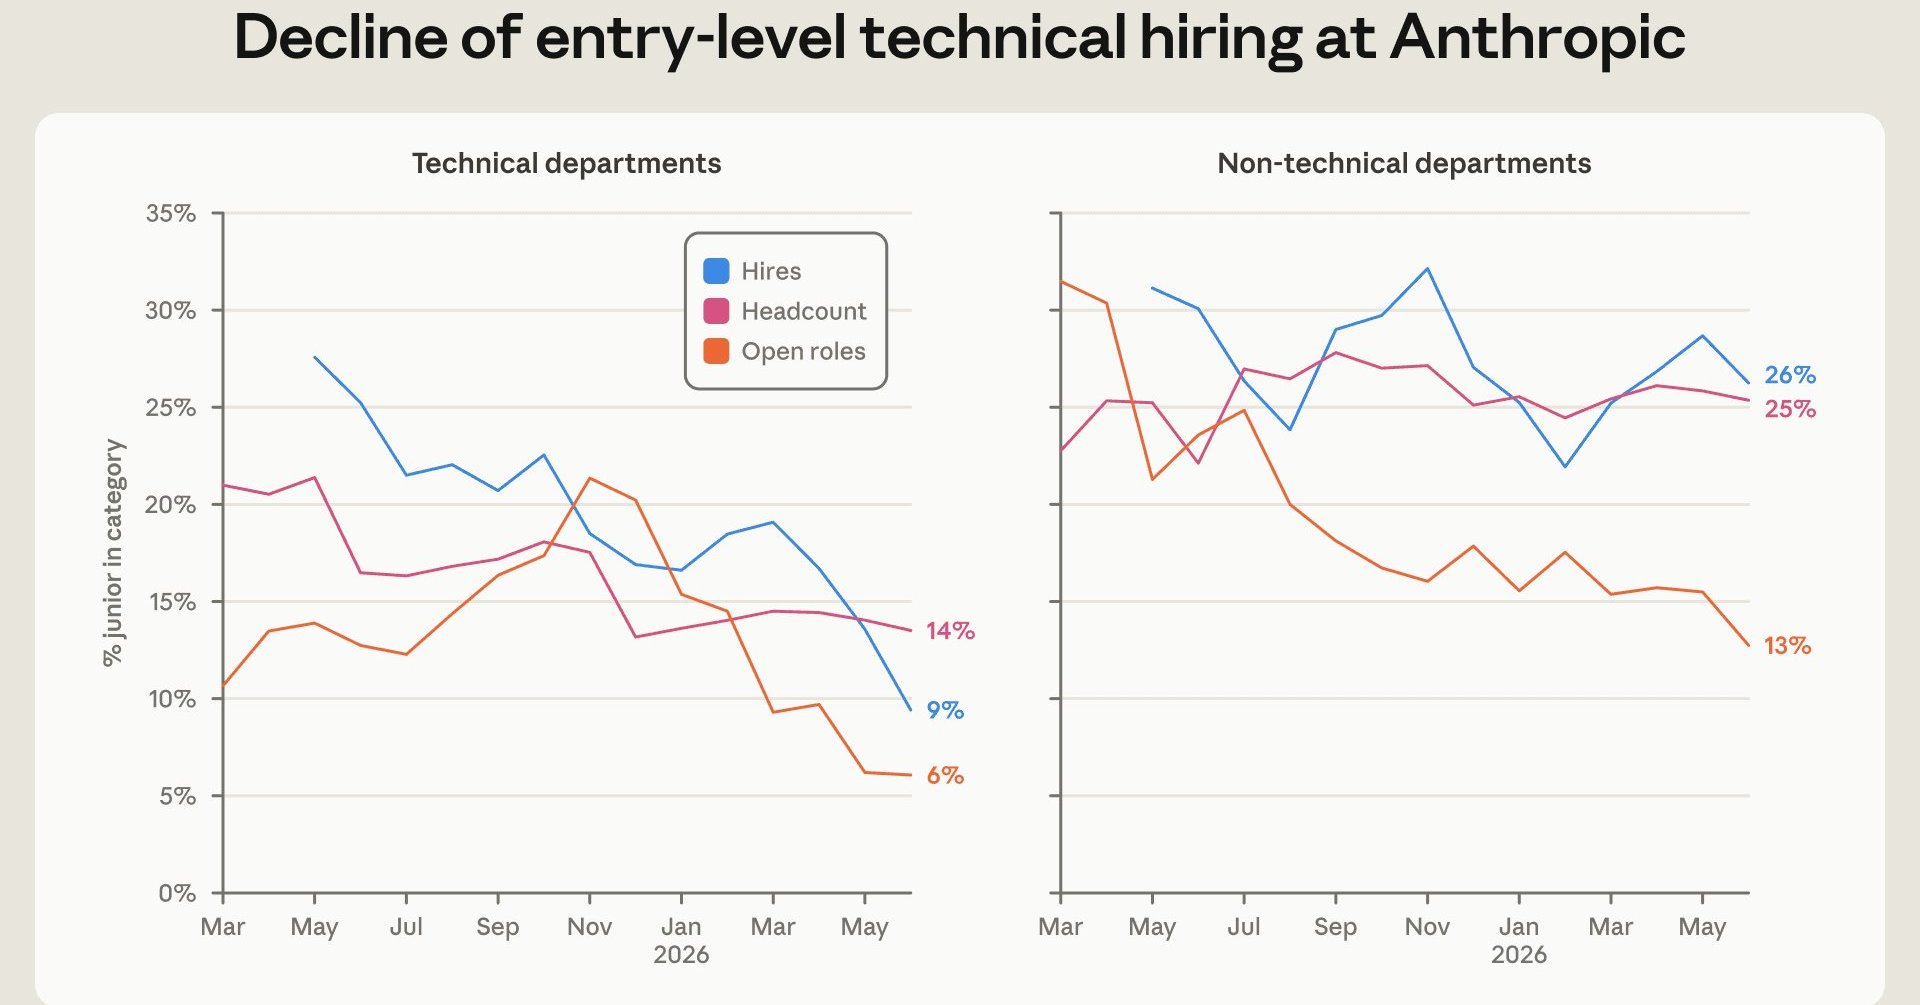
Anthropic's internal report says entry-level workers fell from 21% to 14% of technical staff, and entry-level…
Simon Willison shipped llm-echo 0.5, a debug plugin whose "echo" model involves no LLM at all and just repeats…
On October 13 (US time), Apple announced HomeView, a $299 smart home display running Siri AI and HomeKit but w…
The author detailed a Python script that uploads MP3 audio to Google Cloud Storage (GCS), transcribes it with…

