A blog post on LessWrong lays out the common argument that RL for LLMs accumulates about 1/rollout_length bits per sample versus pretraining, and asks why RL still succeeds.
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
DeepSeek released DeepSeek-V4.1-Flash-1017, a “minor update” that reduces task execution time and output lengt…
NEC's Kei Noguchi described how employee engagement fell to 19%, with 8 in 10 staff saying they wanted to leav…
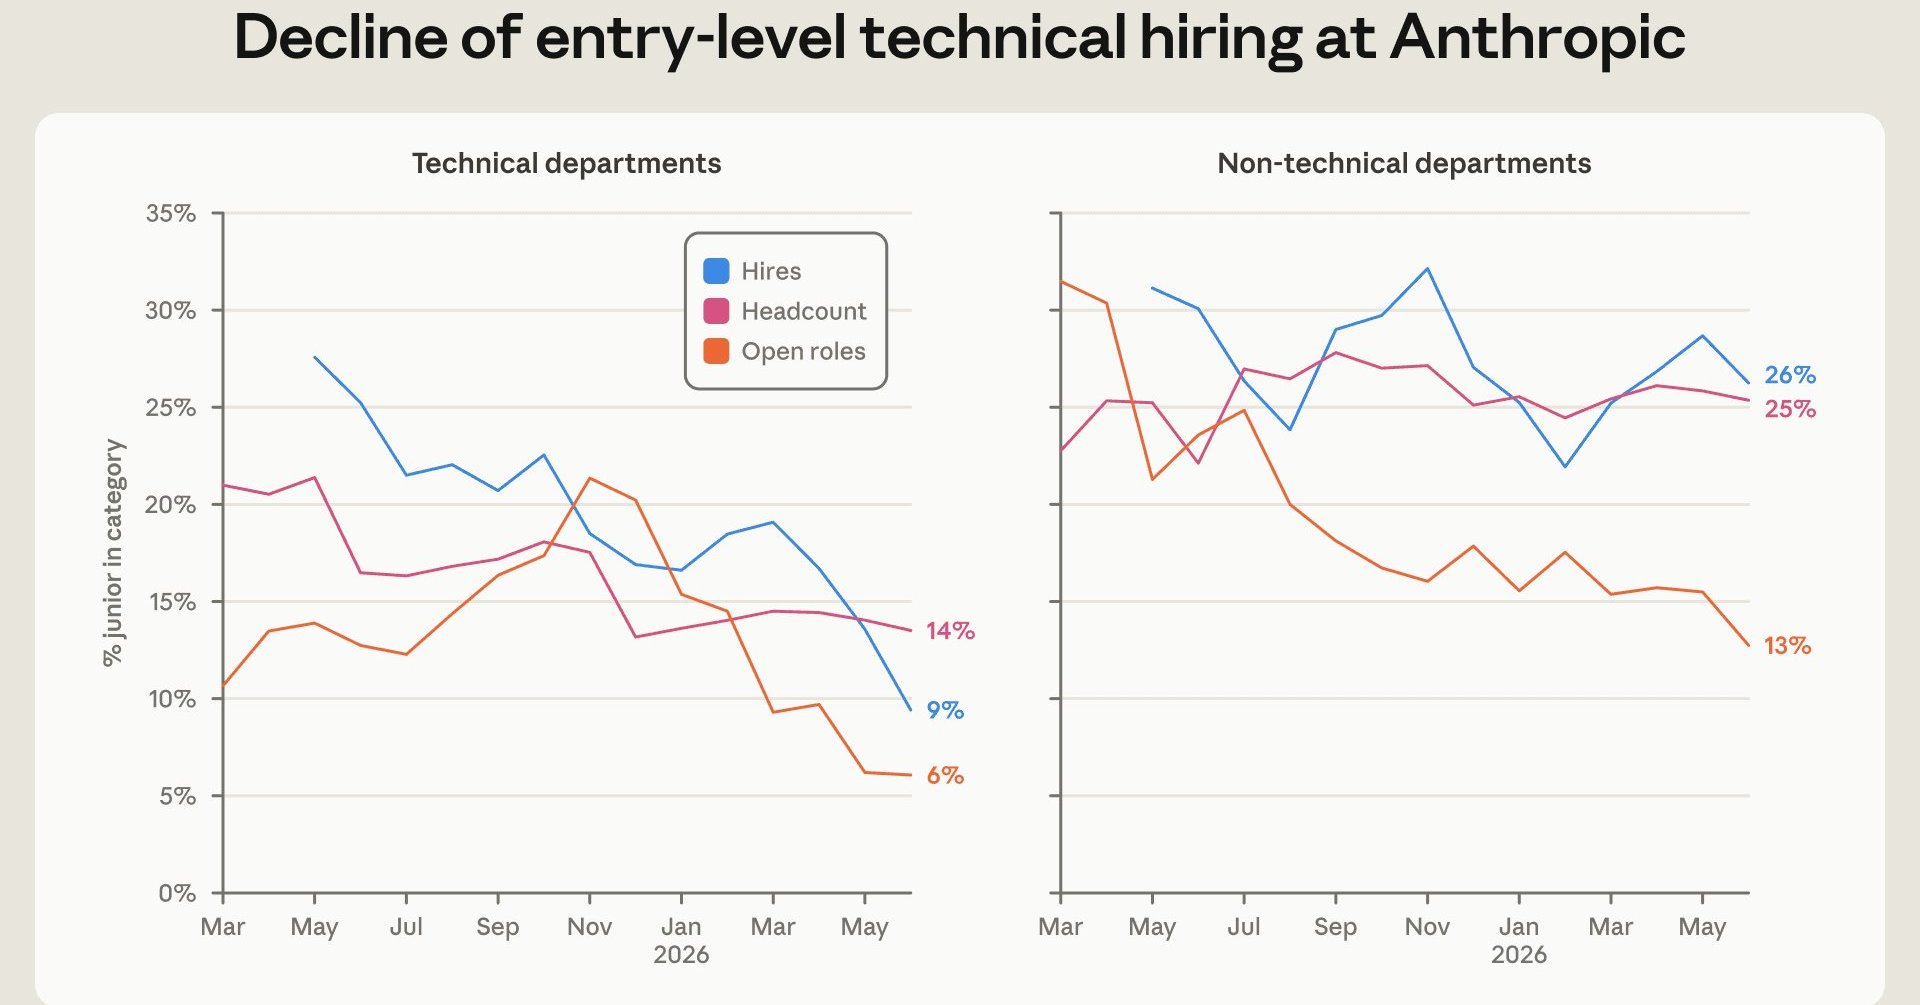
Anthropic's internal report says entry-level workers fell from 21% to 14% of technical staff, and entry-level…
Simon Willison shipped llm-echo 0.5, a debug plugin whose "echo" model involves no LLM at all and just repeats…
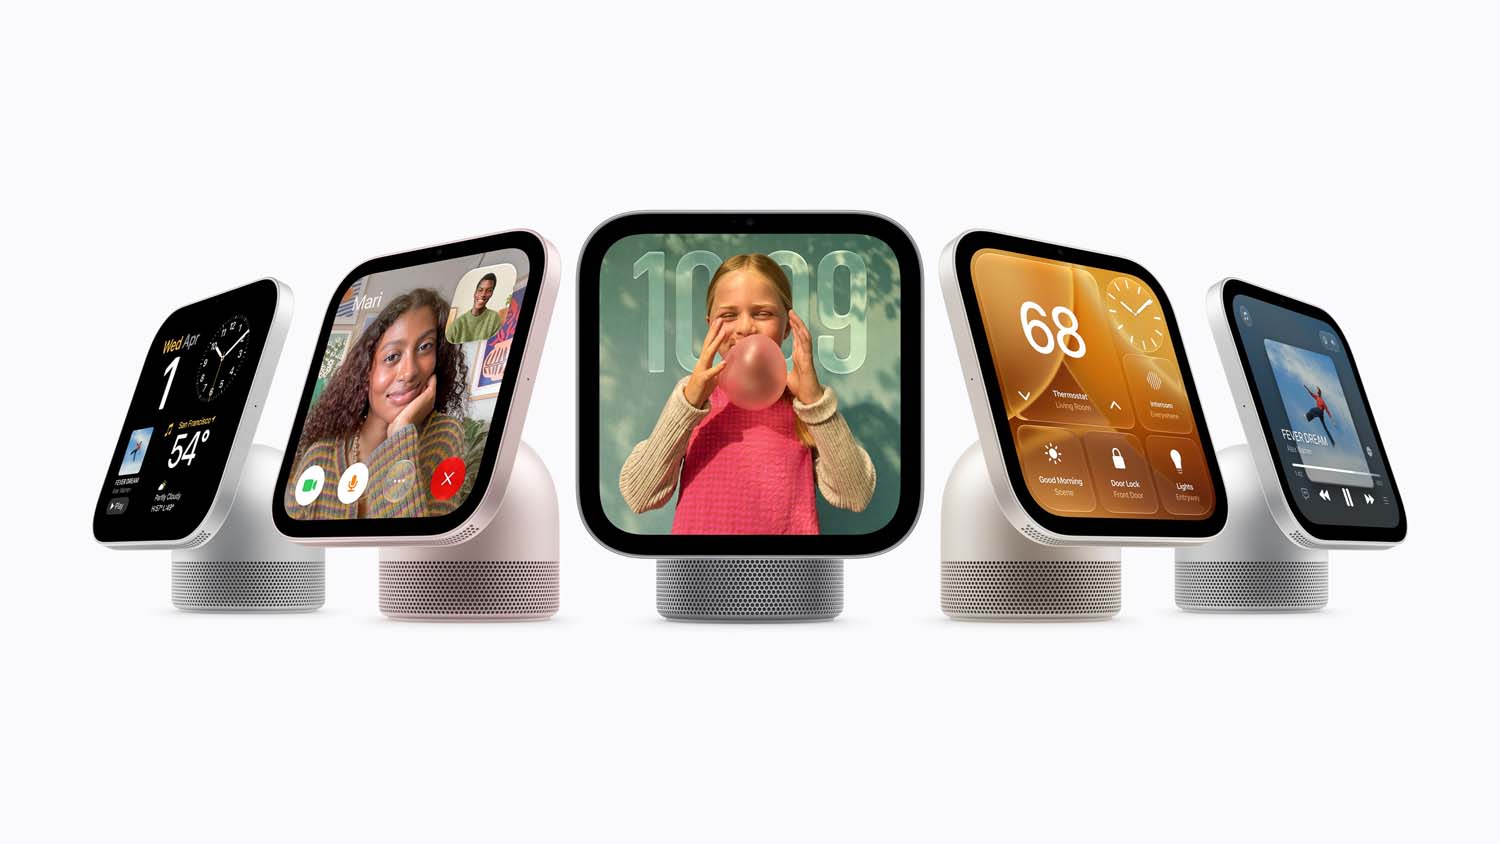
On October 13 (US time), Apple announced HomeView, a $299 smart home display running Siri AI and HomeKit but w…
The author detailed a Python script that uploads MP3 audio to Google Cloud Storage (GCS), transcribes it with…


