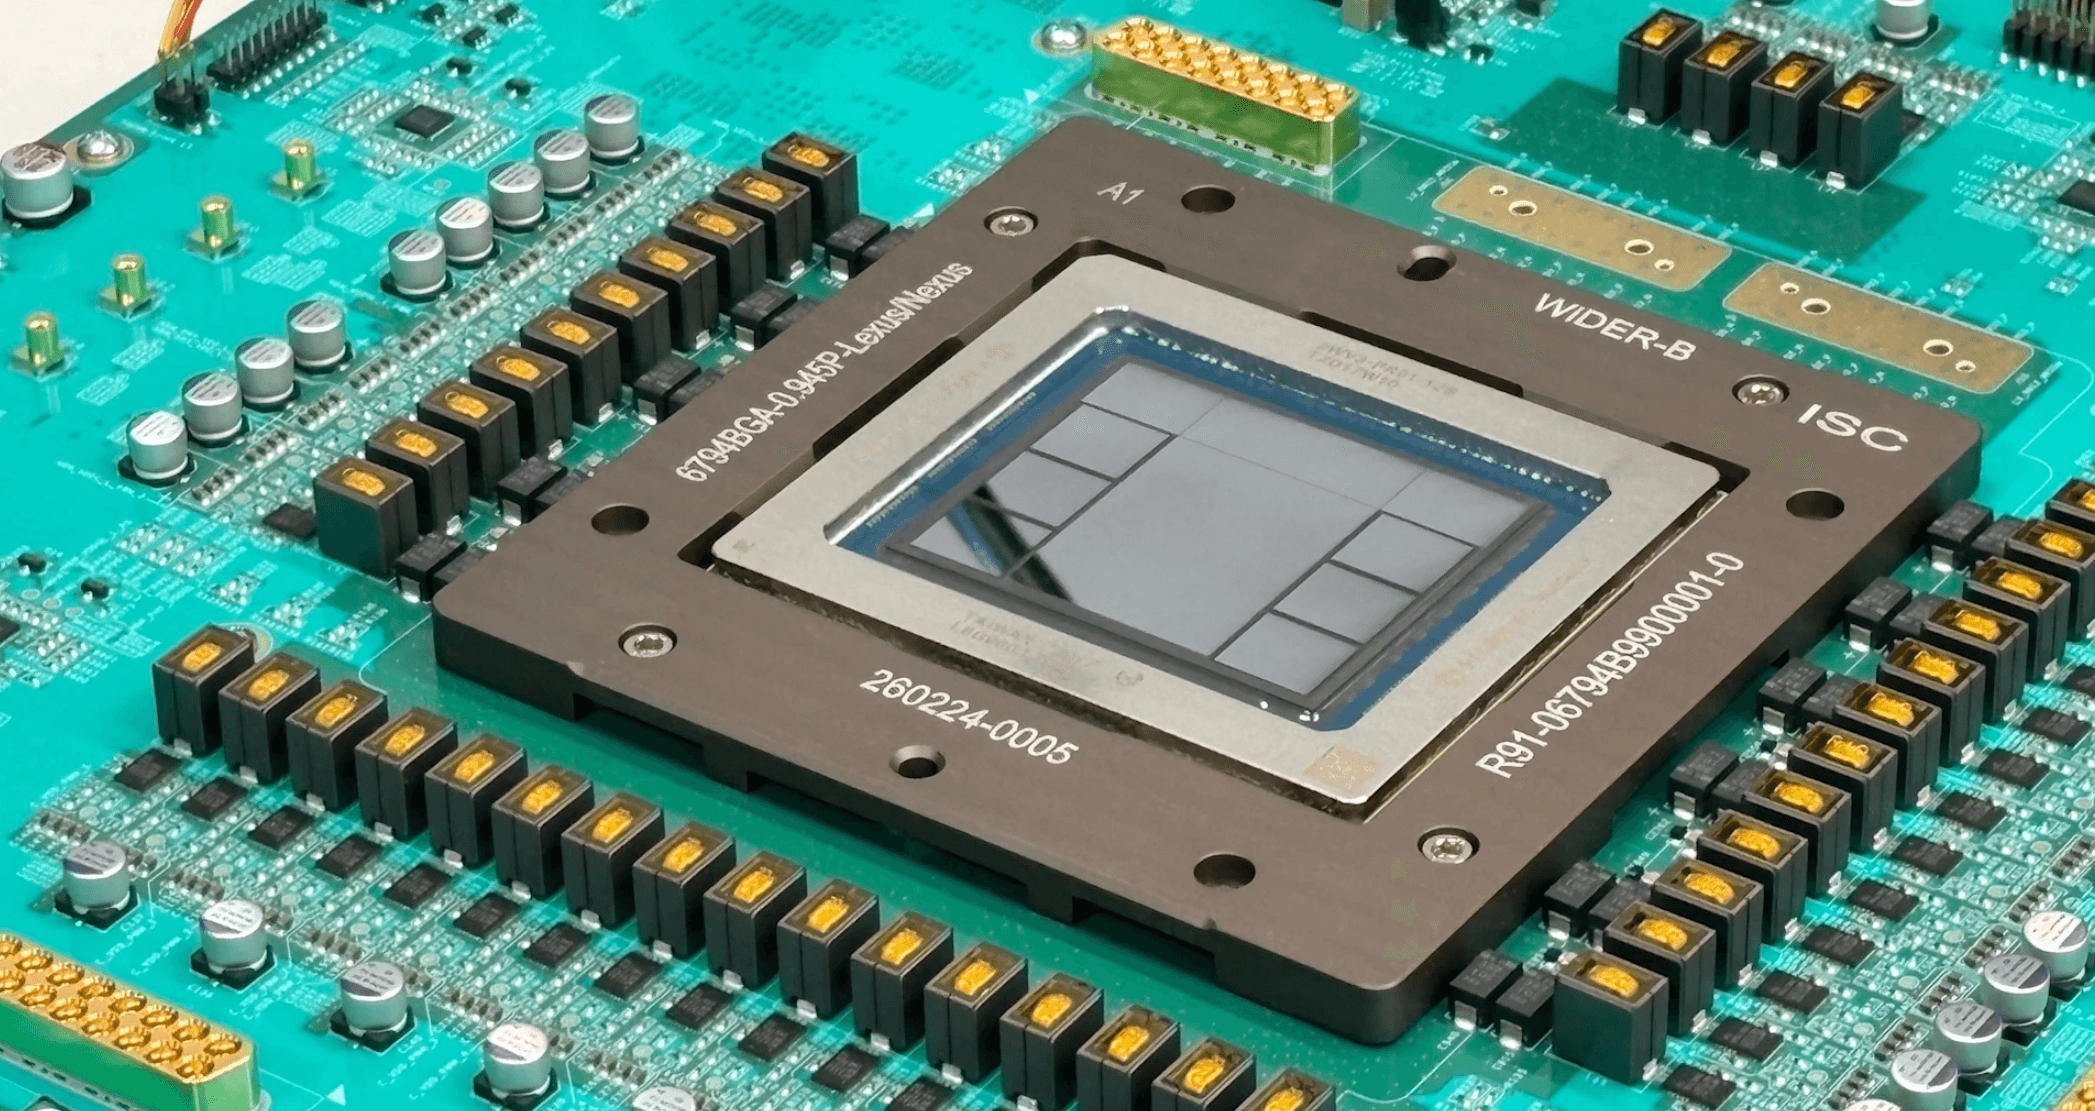
What happened
OpenAI unveiled benchmarks for its custom inference chip "Jalapeño" at the Hot Chips conference. It reportedly outperforms Nvidia's Blackwell and Rubin in throughput per watt and token latency.
Why it matters
Jalapeño delivers 1.5x to 1.9x more AI work per watt and 1.7x to 3.6x lower latency than the best commercial systems. This could challenge Nvidia's dominance in AI chips, with SemiAnalysis suggesting the "CUDA moat" may be "potentially dead."
What to watch
Jalapeño is still in engineering samples, while Nvidia's Rubin systems are shipping. OpenAI claims it built the chip in nine months using its own AI models, and SemiAnalysis notes it beats Vera Rubin in output tokens per megawatt even without multi-token prediction.
Summaries like this, in your inbox every morning.
OpenAI's Jalapeño chip, developed with Broadcom, took only nine months from first design to manufacturing blueprint, a speed that SemiAnalysis says signals the end of Nvidia's CUDA moat. The chip delivers up to 104x token throughput per kilowatt at matched decoding speed, and it does so without relying on optimizations like multi-token prediction, leaving room for further gains. However, caveats remain: competitors like Nvidia and AMD have tested larger models on their chips, and Jalapeño is still an engineering sample, not yet in production. OpenAI's CFO Sarah Friar frames the chip as part of an integrated compute strategy, complementing existing partnerships with Nvidia, AMD, and others, rather than replacing them. This dual dynamic of cooperation and competition underscores the broader industry trend where major players are developing custom silicon, even as they continue to buy from each other.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
The Motley Fool argues Amazon is the AI company of the two, since AWS was just 21% of first-half 2026 revenue…

Hewlett Packard Enterprise stock is down 5% at $55.87

Cammarata reinterprets InceptionV1's cat-car neuron as a V-shape detector, not two unrelated concepts

Google Deepmind's Gemini 4 Argon scored 97.5 percent on ARC-AGI-3 at a cost of $4,800, second only to GPT-6 As…

Microsoft's Surface Laptop Ultra, using Nvidia's RTX Spark platform, starts at $2,599 (up to $5,899)

Meta's new commercial terms, effective October 30th, appear to let it crawl and train AI on content from websi…


