What happened
On the Qualcomm Dragonwing RB3 Gen 2 (QCS6490), YOLOv11-N measured 134.7 ms through default TFLite but 5.03 ms via a precompiled w8a8 QNN path, per Qualcomm AI Hub's on-device workbench.
Why it matters
The measured gap shows that a latency figure without its runtime path is not a real benchmark, since the same model on the same hardware produced very different results.
Summaries like this, every morning.
A model which appears to run may be quietly executing most of its network on GPU and CPU. In the default TFLite path, only 19 of 343 layers ran on the NPU, while 168 layers went to the GPU and 156 to the CPU. Without a layer-by-layer profile, one would record 134.7 ms as the chip's performance and never see the misplacement.
The failures are equally instructive. A precompiled FP32 model was rejected because the device demands quantized I/O. A w8a16 QDQ conversion returned only exit code 14, prompting an upstream issue at qualcomm/ai-hub-models#364. A QNN DLC FP32 model compiled but failed on-device with MODEL_GRAPH_ERROR, a reminder that compilation success is not execution success.
The Galaxy S25 control run matters because it isolates the problem: on a flagship phone, even the default TFLite delegate placed all layers on the NPU at about 2.9 ms. The author notes the same failure pattern on Rockchip boards, where RKNN models silently fall back to CPU per operator. The takeaway is that a latency figure without its runtime, precision, and layer placement is incomplete, and layer profiles are the only evidence that distinguishes a slow NPU from an NPU that was never given the work.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Kokuyo is consolidating meeting minutes, design documents and tasks into Notion and Notion AI, and linking Cla…
Mihail Eric, who teaches The Modern Software Developer at Stanford and leads AI at Monaco, brought open-source…
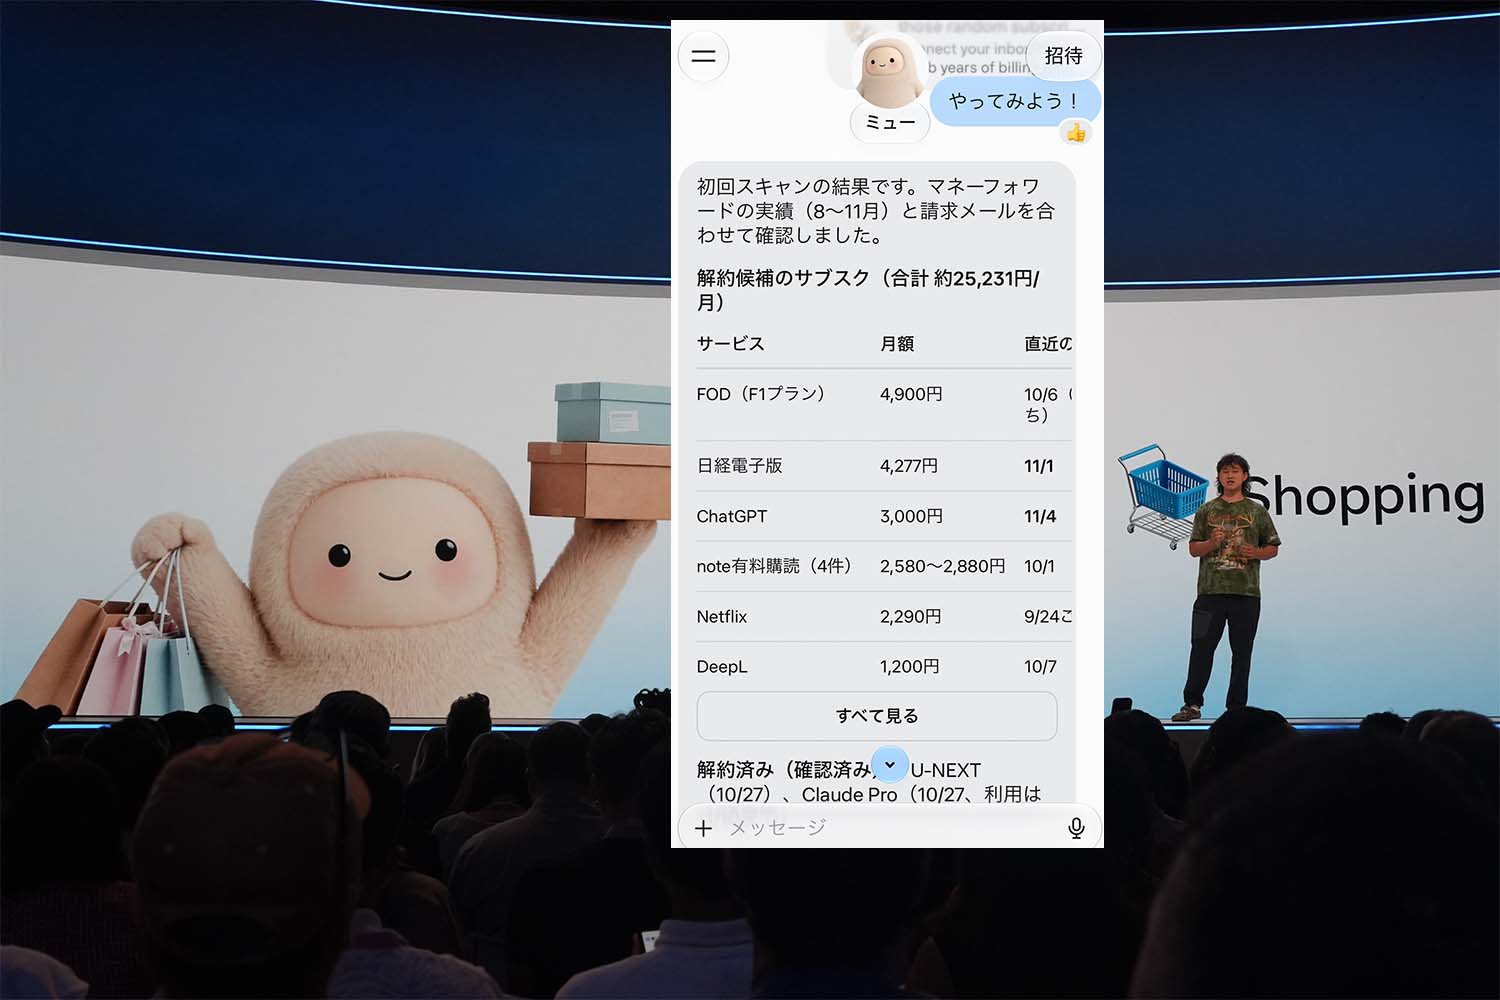
In his Watch Impress column, Nishida Sotokazu says Meta's Muse pushes subscription audits, cheapest electricit…
Testing Rockchip's rknn-llm multimodal demo for Qwen2-VL-2B-Instruct, the author found transformers 5.8.0 thro…
Goldman Sachs has barred employees who are not engineers from using advanced AI tools, as reported by Fast Com…
Visa's Agentic Commerce Benchmark tested 22 AI models from 12 labs on shopping tasks like buying a TV or lapto…