What happened
Across 48 P5en instances — 16 for training and 32 for inference — enabling DeepEP over EFA raised aggregate RL rollout throughput by 40 percent on a super-sparse MoE model.
Why it matters
The 40 percent throughput gain on that setup suggests sparse token routing between machines is a major bottleneck in large-scale training runs, so infrastructure choices may matter as much as compute capacity.
What to watch
The result comes from one 48-instance setup, so whether the 40 percent gain holds at larger cluster sizes is the open question.
WHO IT HITSInfrastructure and platform engineers running large-scale model training on AWS GPU clusters are the ones who would act on this, since the gain comes from a networking and communication configuration rather than new hardware.
Summaries like this, in your inbox every morning.
The post starts from a structural problem in post-training MoE models: as these architectures become more sparse to cut inference costs, training becomes limited more by communication between machines than by raw compute. Expert Parallelism worsens this, because it routes tokens dynamically across devices rather than using the structured patterns of tensor, data, or pipeline parallelism.
To address that, AWS combined Amazon EKS, EFA, and Amazon S3 so orchestration, high-performance networking, and durable storage can scale on their own. Amazon also contributed features migrating DeepEP's communication primitives to libfabric, giving DeepEP v2 native EFA support, and NCCL 2.31 picked up the latest EFA optimizations for dense collective communication. In testing across 48 P5en instances, that combination raised aggregate rollout throughput by 40 percent. The post also proposes Spot Instances for rollout generation, since interruption of a rollout worker does not halt the whole job the way it would for tightly coupled training workers.
Whether that 40 percent holds beyond this single cluster size is the practical uncertainty. For teams weighing where to spend on training infrastructure, the finding suggests networking configuration, not just accelerators, may be the lever worth testing first.
For example, today's edition would include:
AI-summarized, only the topics you pick: one digest a day via Email, LINE, or Slack.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Google DeepMind chief Koray Kavukcuoglu said Gemini 4 has entered post-training and Google intends to ship an…
CrowdStrike Holdings (NasdaqGS:CRWD) became a founding member of the Blueprint Alliance, joined by AWS, Google…
At Dreamforce 2026, Salesforce presented an agentic health enterprise, citing UCLA Health's 75,000+ patient in…
Microsoft launched an updated Copilot app that can code and handle productivity tasks, replacing separate 365…
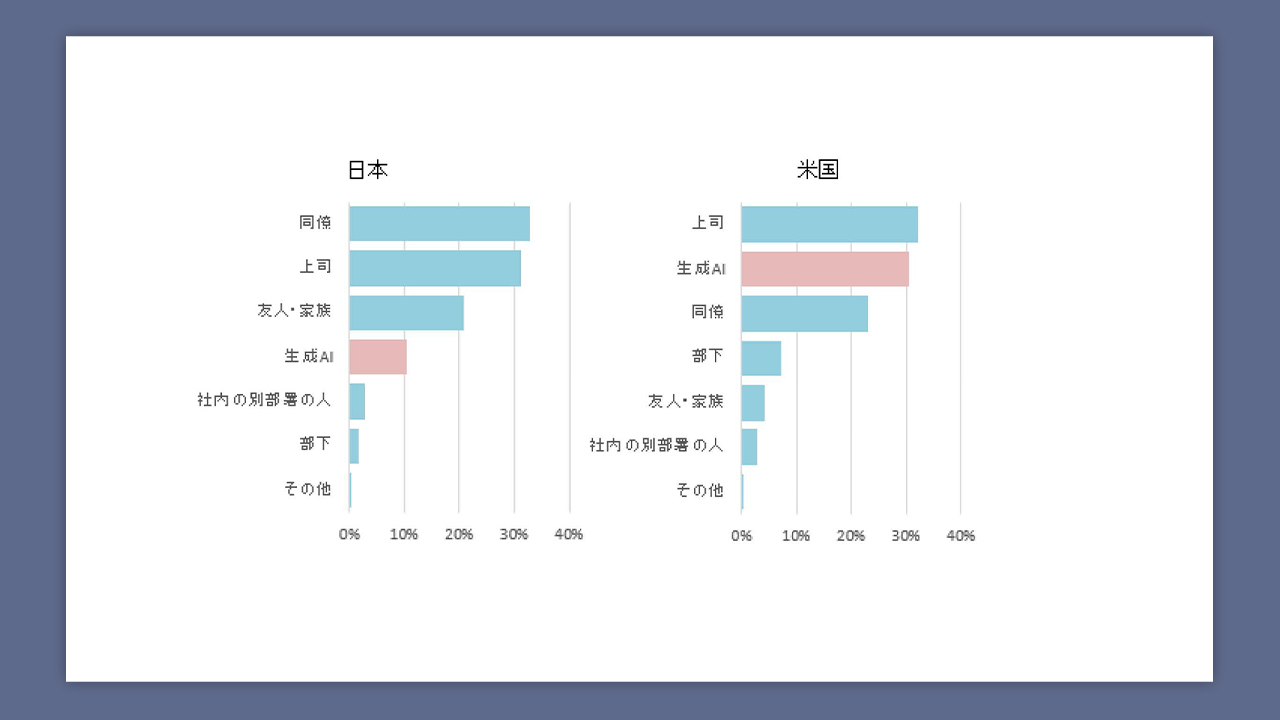
AdverTimes (AdverTimes by Sendenkaigi) compared how people in Japan and the U.S
Shoeisha will publish 'Evaluation-Driven Development for LLM Applications' on September 24