What happened
Cartesia, an AWS Partner, detailed how its Sonic (text-to-speech) and Ink (speech-to-text) models, built on State Space Models, achieve sub-100ms latency and are available on AWS.
Why it matters
With first audio byte in approximately 90ms, the models are designed to make AI voice interactions feel as responsive as human conversation, which could reduce awkward pauses in customer-facing applications.
WHO IT HITSDevelopers building real-time voice features such as contact-center agents, telehealth tools, and accessibility interfaces can now deploy Cartesia's models within their own AWS accounts, giving them more control over latency and data sovereignty.
Summaries like this, every morning.
Cartesia's approach addresses a fundamental tension in voice AI: traditional transformer-based text-to-speech models process entire sequences before producing output, so higher quality often means higher latency. State Space Models process sequences step by step with a constant memory footprint, enabling true streaming without architectural modifications. Sonic leverages this to begin generating audio before the full text input is received, and Ink uses native turn detection to identify when a speaker has finished, reducing the need for separate voice activity detection. Together, these models aim to deliver the responsiveness users expect from human conversation, and their availability on AWS—through a managed model package or self-managed containers—gives teams options for balancing operational control with time to deployment.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
A comparison of 11 singing photo generators picked freebeat as best overall, citing Photo Karaoke's staged cli…
OLA PARTY JAPAN's Yoitoki made its AI matchmaker voice interview available to all users from October 4, with r…

The team launched ViiTor Live, an online tool that transcribes audio/video files up to 500MB, supports 100+ la…
Google DeepMind announced Genie 4 on October 27, 2026, a real-time world model that natively generates ambient…
Google DeepMind announced Genie 4 on October 27, 2026 — a world model that builds scenes you can walk through…
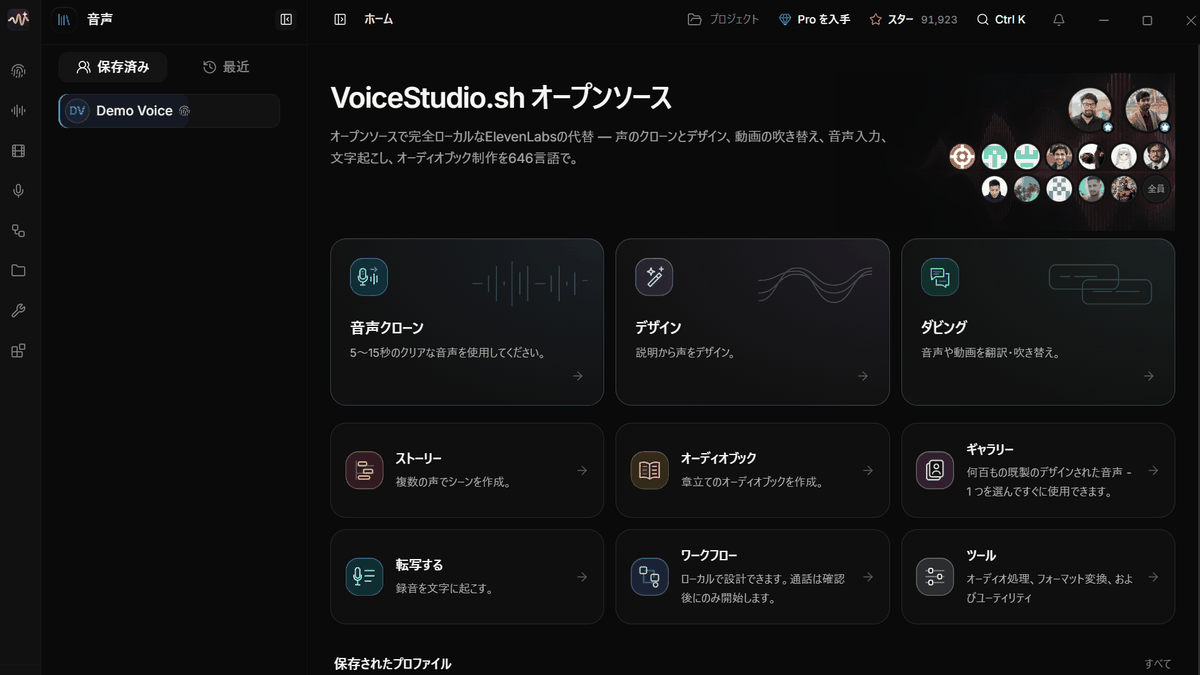
VoiceStudio, an open-source ElevenLabs alternative, runs on Windows with OmniVoice as its default engine, cove…