What happened
i14 used native PyTorch through TorchNeuron Native to run its Laplace 3B linear-attention model on AWS Trainium2, training at about 120,000 tokens per second on one trn2.48xlarge instance.
Why it matters
This shows Trainium2 can support custom architectures beyond standard transformers, giving teams an alternative to GPU-optimized kernels for specialized models.
WHO IT HITSAI teams building long-context agents and large-document analysis tools may gain a serving option where per-sequence memory stays fixed, making capacity planning more predictable, though they must evaluate retrieval quality for their workloads.
Summaries like this, in your inbox every morning.
i14 positions Laplace 3B as an alternative to standard transformer models, whose key-value cache grows with context and can reduce concurrency and increase serving cost. By replacing softmax attention with Gated Linear Attention, the model compresses history into a fixed-size recurrent state. Bringing this custom architecture to Trainium2 required more than a port: the original GPU-optimized Triton kernels had to be re-expressed with standard PyTorch operators, and the Muon optimizer's communication pattern was redesigned under FSDP2. The team chose the beta version of TorchNeuron Native after comparing approaches because it performed better. The reported training run, still in progress at about 44 billion of 100 billion tokens, showed a smooth loss decline and stable gradients. On the serving side, an unmodified vLLM engine matched i14's reference outputs token for token, and profiling showed that operator dispatch—not arithmetic or memory bandwidth—dominated decode time, which compiled decode addressed. These results suggest that Trainium2 can accommodate architectures beyond standard transformers, though teams would need to assess retrieval quality for their own workloads.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
The US imposed sanctions on five Chinese entities tied to former Google engineer Linwei Ding, after his convic…
Pigment closed a $250 million Series E at a $2.3 billion valuation, led by Scaleup Europe Fund managed by EQT…
Nvidia is reportedly in talks to invest hundreds of millions of dollars in Firmus, and Maas Group — which owns…
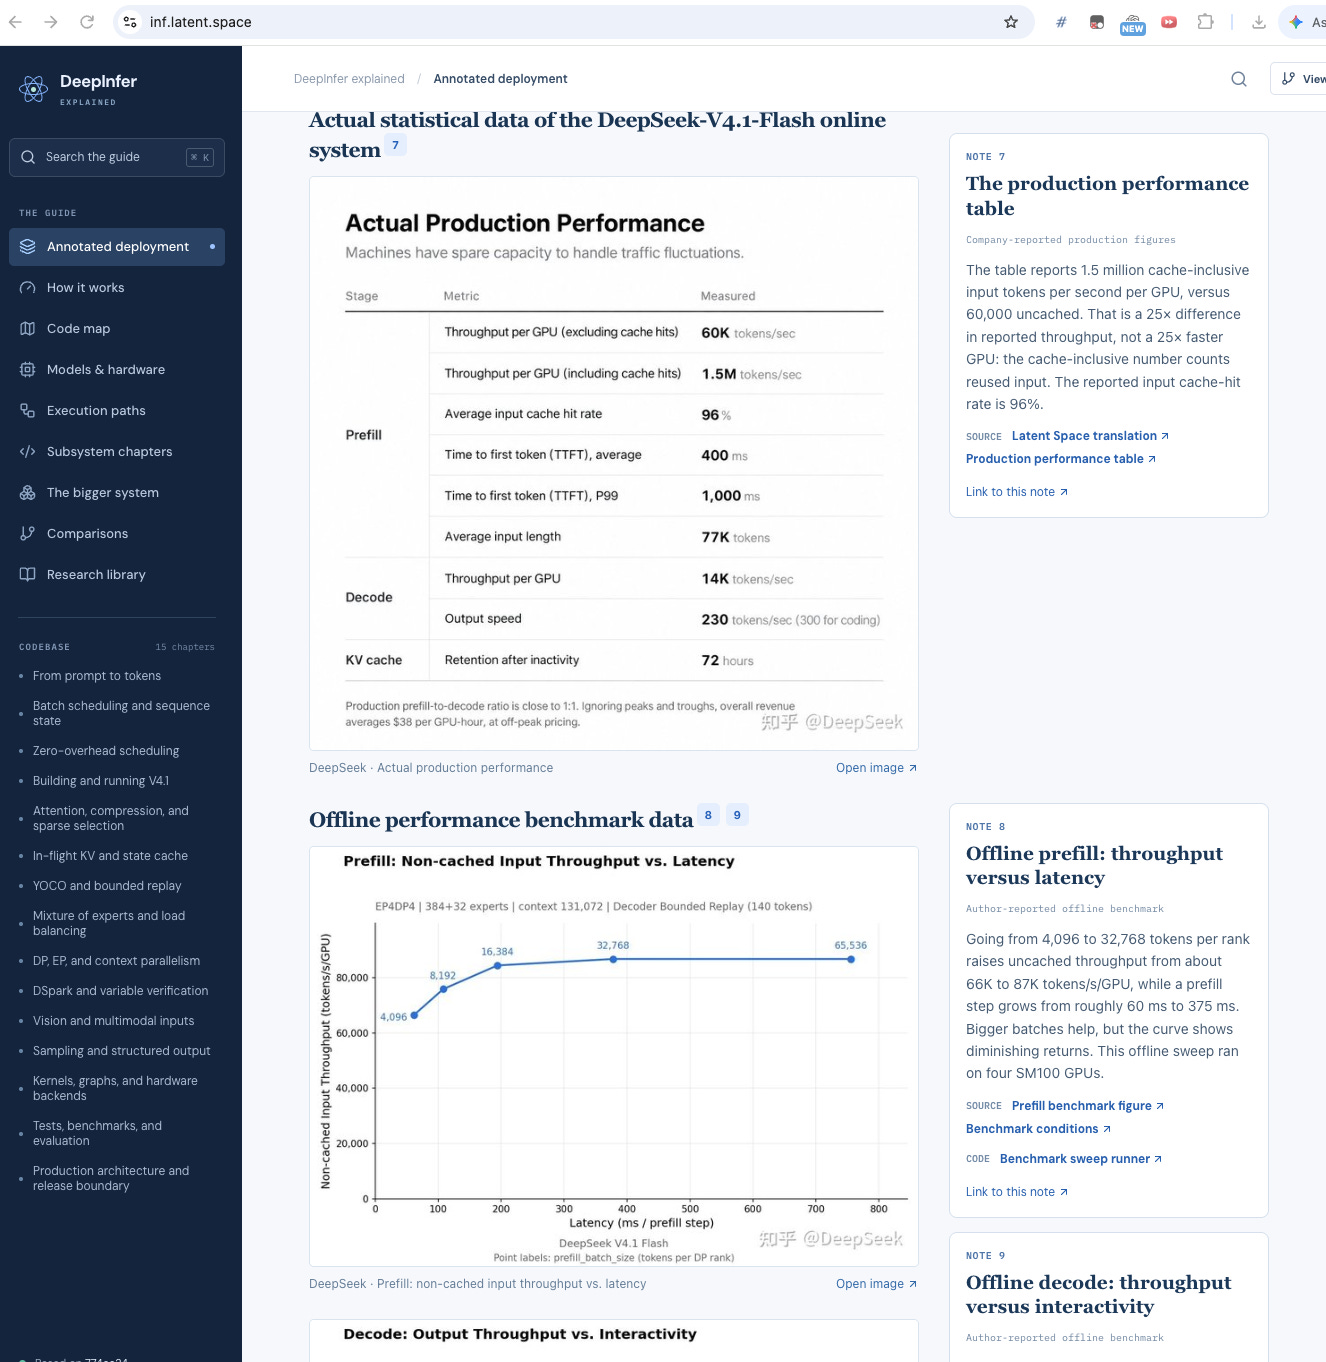
DeepSeek released DeepInfer, the inference engine behind V4.1-Flash, with production figures of 155 trillion t…
Tenex cofounder Alex Lieberman said at AIE New York that the firm has grown to 75 people, with 50% of customer…
OpenAI acquired Orchestra Bio on October 20 and is integrating its team and drug-development coordination tech…