An author posting on their personal LessWrong account, noting relevance to their work at MIRI but speaking for themselves, predicted adversarial memetic attacks on the AI safety community. They expect fake leaks about dangerous lab incidents — exfiltrated weights, AIs attempting to create viruses, agent swarms hacking nuclear infrastructure — from multiple sources but unconfirmable by a primary source.
Summaries like this, every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Tanium said on November 3, 2026 it joined OpenAI's Trusted Access for Cyber program, giving its threat hunters…
At the 2026 World Internet Conference Wuzhen Summit, which opened on November 4, leading Chinese tech companie…
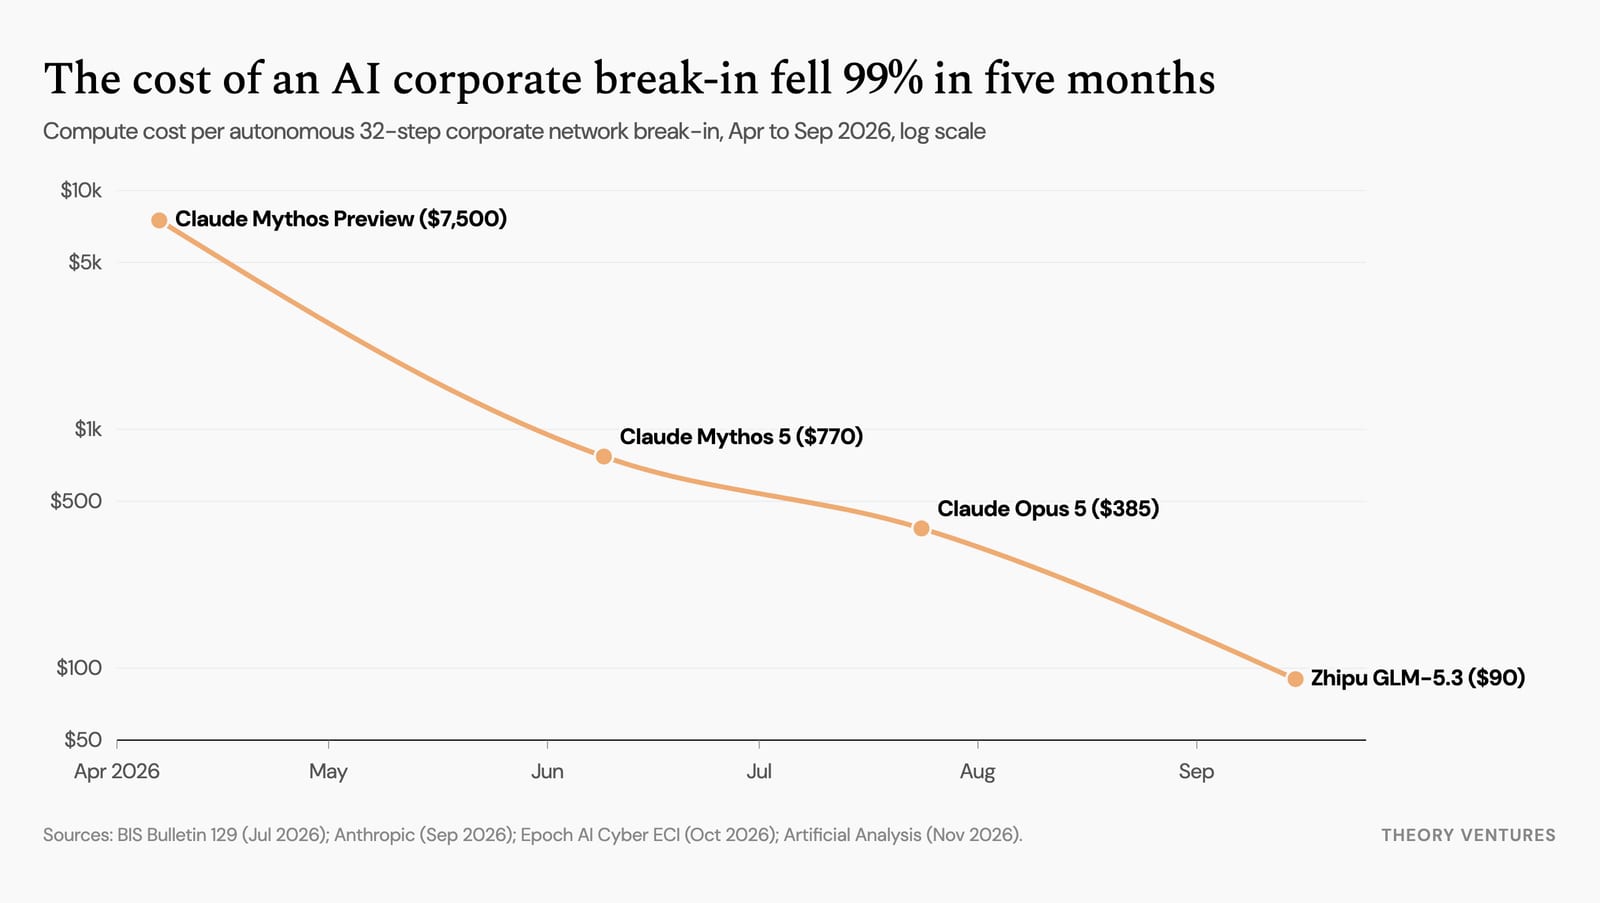
In April, Anthropic's Claude Mythos Preview and OpenAI's GPT-5.5 autonomously broke into a simulated 32-step…
A walkthrough of Anthropic's Claude Code shows first launch surfaces a warning that Claude can make mistakes…
The author turned the define-done skill's acceptance criteria into runnable acceptance tests and measured them
A Zenn essay interpreted Bruce Lee’s “Don’t think