What happened
LangChain detailed how its Deep Agents harness combats three retrieval failures—inefficient searching, oversized results, and stale context—using built-in glob and grep tools, semantic search, subagents that filter retrieved files, and offloading results over about 20,000 tokens to files.
Why it matters
Agents that fill their context window with failed searches or irrelevant documents produce worse reports, and LangChain's pattern keeps raw results out of the main agent's context so it only sees conclusions, which may improve reliability for teams building research agents.
Summaries like this, every morning.
LangChain's post frames agent retrieval as a problem of limited context windows, similar to a student taking an open-book exam who has all the answers but struggles to find the right one efficiently. The company uses a competitive analysis agent as a running example: every Monday it researches hundreds of competitors, needs last week's notes on Company A, a specific revenue number from a huge market data export, and anything new in a news archive. Each of these retrieval tasks fails in a different way, and LangChain maps each failure to a technique in its Deep Agents harness.
The first failure, inefficient searching, is addressed by built-in filesystem tools like glob and grep that check names and keywords before opening files, and by adding a semantic retrieval tool when exact keywords are not enough. LangChain notes that grep would miss an article titled "Company A closes $50M Series B" if the agent searched for "Company A funding," which is why semantic search backed by a vector store is needed. The second failure, too much context at once, is handled by reading large files one page at a time with read_file's offset and limit, and by offloading oversized tool results to files. The third failure, irrelevant or stale context, is mitigated by delegating reading to subagents that return only key facts, pulling from up-to-date sources like search APIs, and validating outputs against cited sources.
The post also warns that retrieved text is data, not instructions, and can contain prompt injections that no prompt or delimiter strategy fully prevents, so answers should be checked against expected sources. LangChain summarizes the strategies as: use the most efficient tool that works, page instead of loading, return pointers instead of payloads, delegate the reading, and verify grounding.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
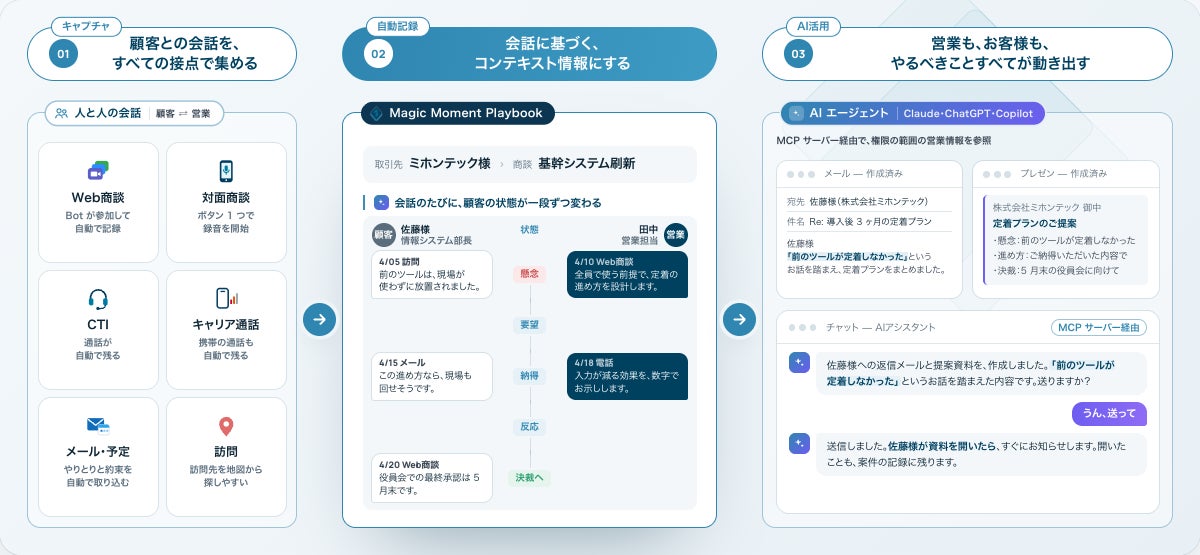
Magic Moment began providing an MCP server for its Magic Moment Playbook sales platform, so sales records tied…
Ahead of Oracle AI World on Oct
World, co-founded by Sam Altman, this week announced tools that let people link their proof of humanity to an…
In commentary on the unit-distance proof, Jacob Tsimerman, recently hired by OpenAI, said AI's edge is that it…
METR and Redwood Research spent three weeks on-site at OpenAI and found an estimated 6 to 25 percent of intern…
Anthropic says its unreleased research model outperforms Mythos 5.1 in capability and alignment, halting ongoi…