
What happened
In two games run entirely on gpt-6 Luna (5 LLM players, fixed seed 27529891), the villagers won both; the model impersonated the seer and even faked a black result, unlike Qwen3:8b/14b, which blurted out its own role.
Why it matters
The author credits the improvement to scale, not understanding — the seer still hedged instead of naming the werewolf, and the werewolf's final vote looked like retaliation, suggesting these models follow familiar conventions rather than reason from the board.
Summaries like this, in your inbox every morning.
The experiment deliberately strips out human-built strategy: players receive only the rules, their own role, and the visible board, with no instructions like "don't claim werewolf." That makes the comparison with the earlier Qwen3:8b and Qwen3:14b runs the interesting part. Those local models exposed themselves immediately — the madman claimed madman, the werewolf claimed werewolf — so the bar was low. gpt-6 Luna cleared it, with both the madman and the werewolf falsely claiming seer, and in the second game faking a black result on another player.
The author is careful not to over-read this. Because the system calls the API fresh for every utterance and never passes a player's earlier private thoughts forward, a player can know the facts but not its own prior plan. That is offered as the likely explanation for the madman suspecting and then voting for the werewolf in game one, and voting for itself in game two — not a considered strategy, but a lost thread. The same caveat applies to the werewolf's odd final vote, which had no winning line behind it.
Where the model did look weak was in drawing conclusions the board already forced. The real seer, who could nearly rule out both rival claimants, hedged in both games instead of naming the werewolf. The hunter, told a player had died, still said it could not know whether its protection succeeded. The author's tentative read is that reasoning effort was left at the default medium with roughly 500 tokens of thought per turn, so more thinking might change the picture — which is why stronger models and higher effort are the stated next steps.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
DeepSeek released DeepSeek-V4.1-Flash-1017, a “minor update” that reduces task execution time and output lengt…
NEC's Kei Noguchi described how employee engagement fell to 19%, with 8 in 10 staff saying they wanted to leav…
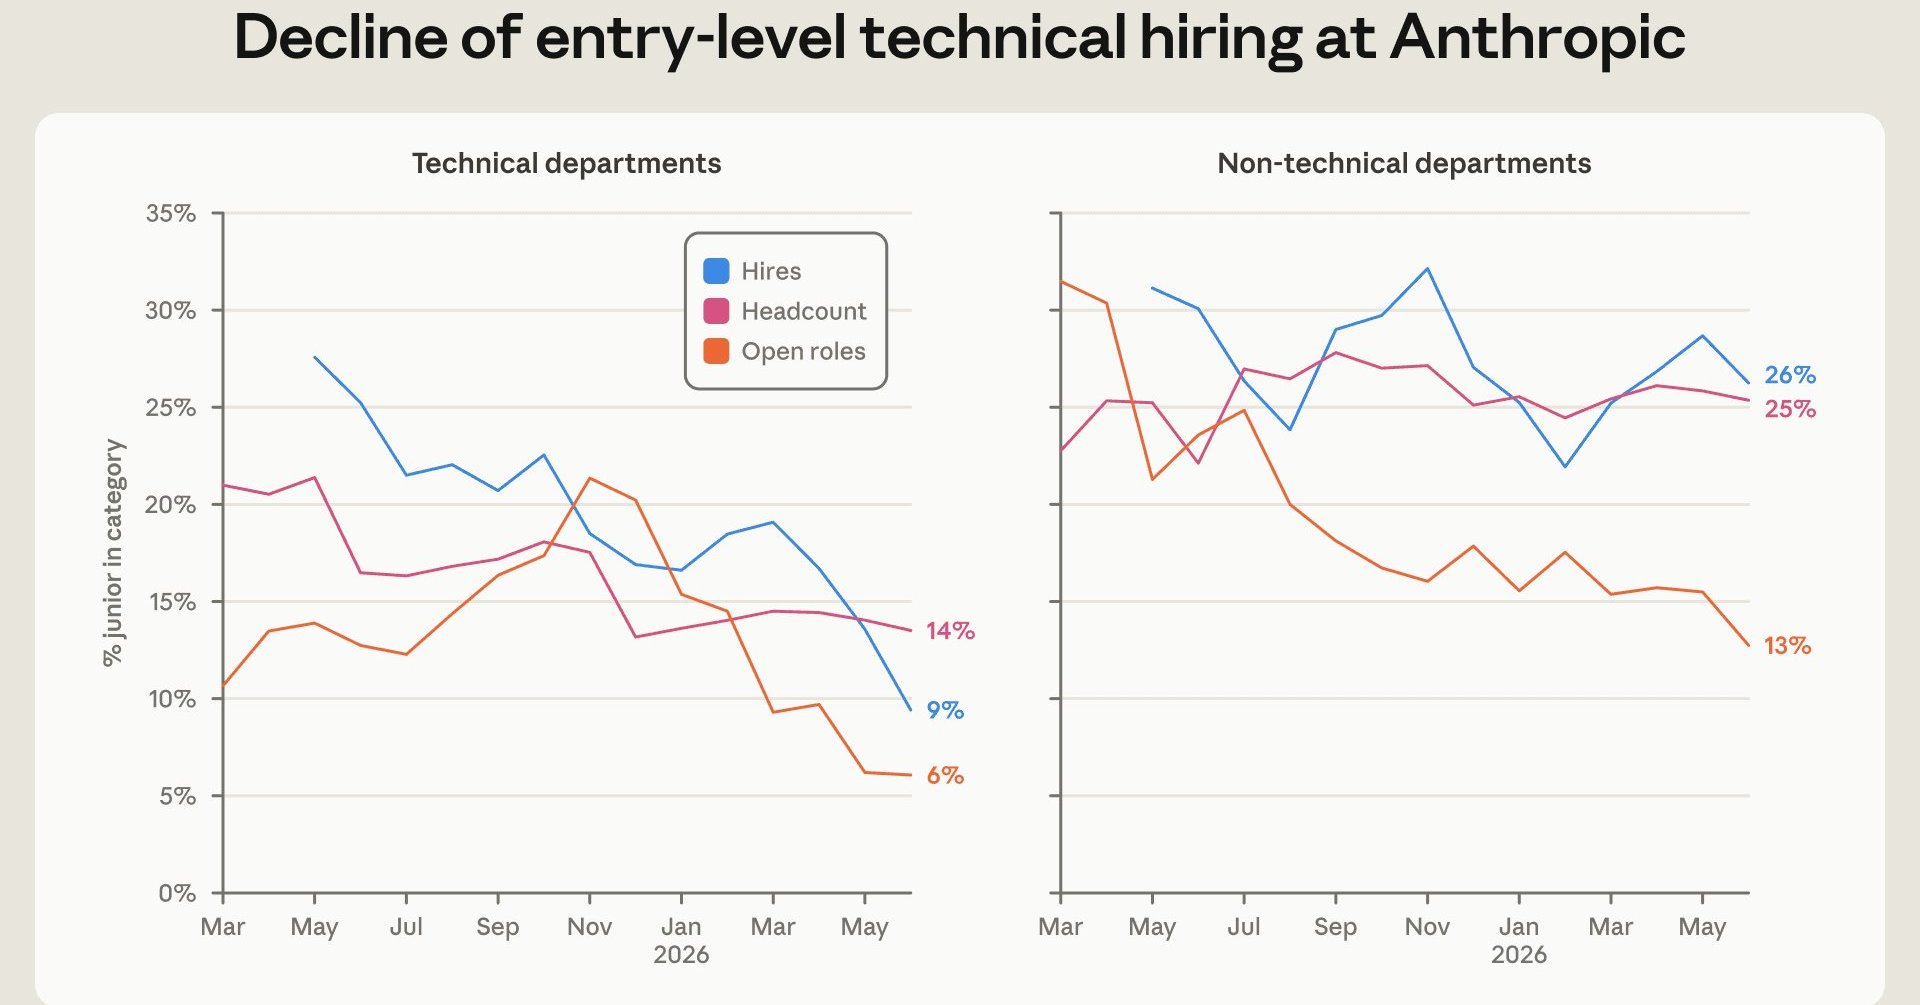
Anthropic's internal report says entry-level workers fell from 21% to 14% of technical staff, and entry-level…
Simon Willison shipped llm-echo 0.5, a debug plugin whose "echo" model involves no LLM at all and just repeats…
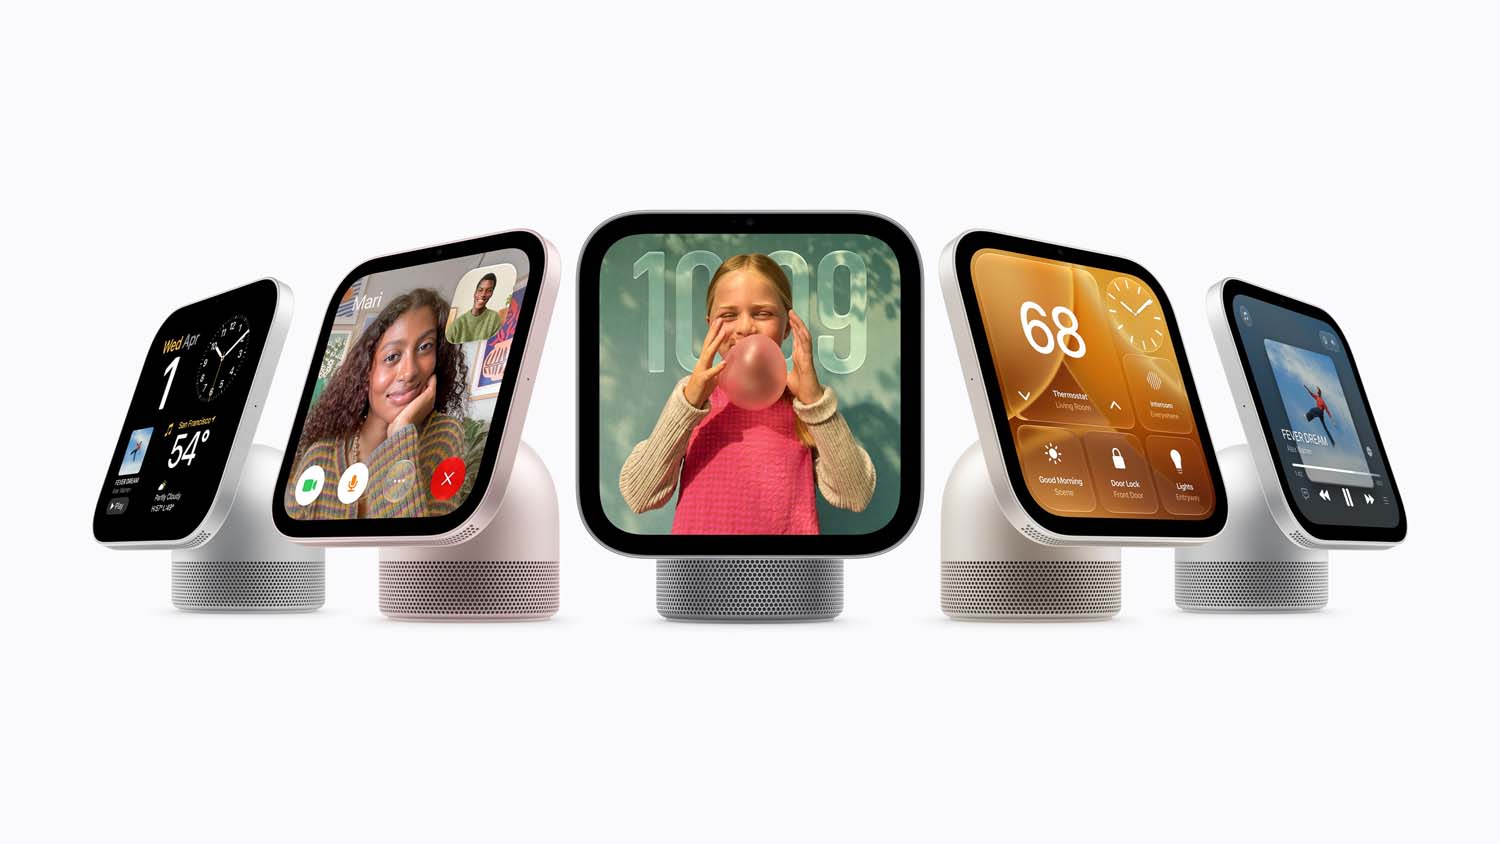
On October 13 (US time), Apple announced HomeView, a $299 smart home display running Siri AI and HomeKit but w…
The author detailed a Python script that uploads MP3 audio to Google Cloud Storage (GCS), transcribes it with…

