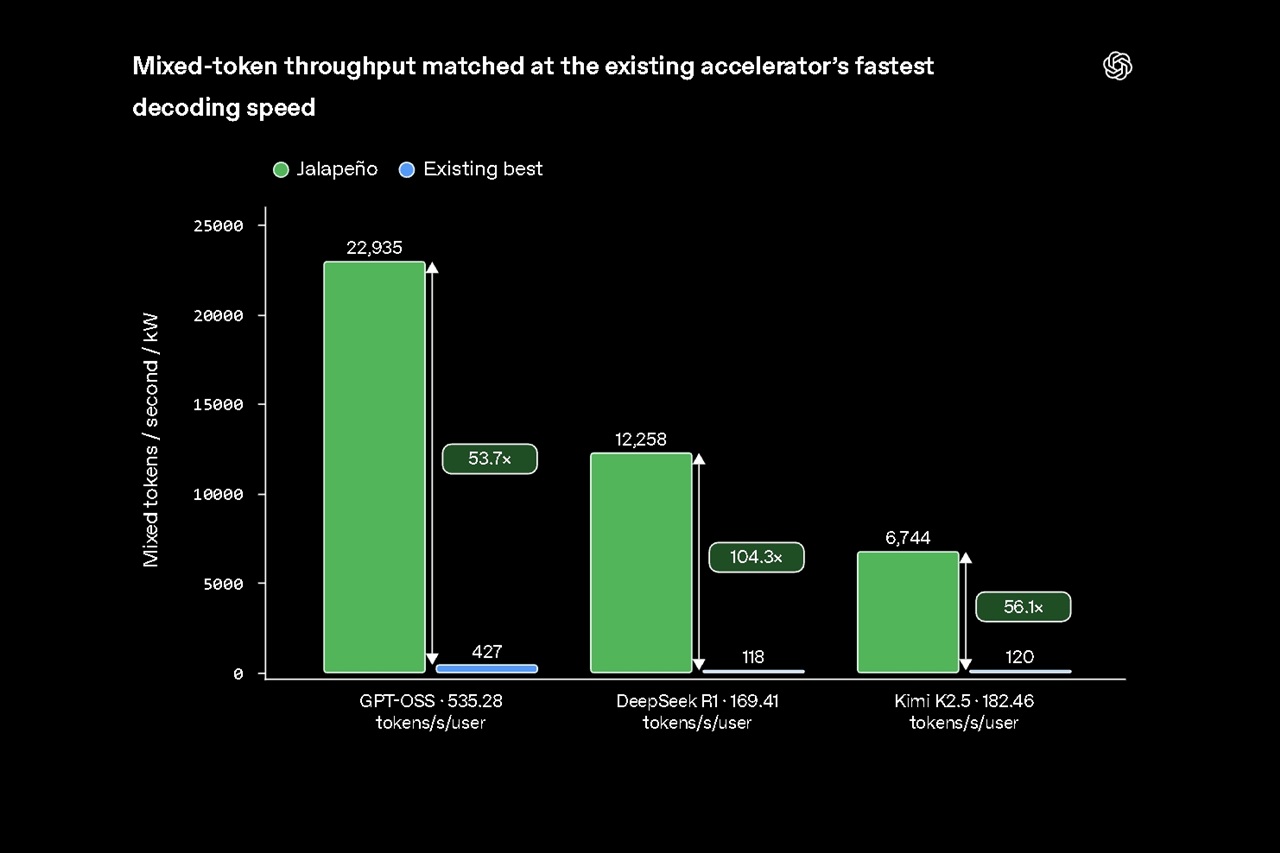
OpenAI announced its first custom inference chip, named Jalapeño, which delivered faster responses and better power efficiency than competing systems in tests across several large language models. The chip cut latency up to 3.6x.
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
A Motley Fool analysis argues Palantir's price-to-sales ratio of 81 prices in endless growth, while Wall Stree…
Microsoft is the cheapest of the four big tech stocks on price-to-operating-earnings, with about $175 billion…
Qualcomm trades at 26 times next year's earnings, versus 15 for Nvidia and 22 for Broadcom, even though its st…
SpaceX shares rose more than 5% on Friday after Starship's first trip to Earth orbit and a week of launches, a…
AMD closed at $608.10 on October 9, down 6.36% from its October 6 record close of $649.42, after a Financial T…
Vals AI tested GPT-6 Sol and Claude Opus 5.5 on the Vibe Code Bench, solo and as teams, at medium and maximum…