What happened
Kisaburo Yamada sketched the LogicStudio logic IDE, its LLint checker, and a .wm world-model format, splitting reasoning into loose proposition matching and strict rule application.
Why it matters
The design aims to stop LLM reasoning from leaping past logic, while human refinements are stored as signed .wm propositions rather than blended into model weights, so edits stay local and reversible.
What to watch
The whole thing is a concept paper with no experiments, so its claims hinge on open problems like proposition-extraction stability, matching thresholds, and confidence calibration; a suggested first test compares LLint against a standalone LLM on a small domain.
WHO IT HITSAI researchers and engineers building reasoning or verification tools, and knowledge workers who would edit and sign proposition models, are the people this design is aimed at.
Summaries like this, in your inbox every morning.
The paper's starting point is a concrete failure the author cites: adding a single dictionary entry — "upper: shoe upper (noun)" — to a rule-based machine translation system broke its regression tests badly, because the extra sense multiplied the parsing search space. The same pattern shows up in search, where a query about using FFmpeg without dependency problems tends to return container, package-manager, or source-build answers while burying the "one static build, just run it" answer. The author calls this "cyberspace debris" — knowledge that has lost its conditions of application.
Against that backdrop, the design places a three-layer toolchain: LLint as a small UNIX-pipe logic linter where --parse proposes propositions (the LLM's job), --edit lets a human accept or reject them, and saved results go into a JSON Lines proposition dictionary. LogicStudio sits above it as an IDE for the logical tree of a text, much as a code editor works with an abstract syntax tree. Storing those propositions and rules in a .wm file turns a dictionary into a world model — the author notes one can run Hayek.wm against Keynes.wm, diff them, and see where the two viewpoints collide.
The paper is explicit that none of this is verified yet, and the open problems it lists are the real stakes. Whether loose matching stays reliable across a multi-step chain, whether writing application conditions just recreates the old dictionary-maintenance burden, and whether confidence numbers from an LLM are calibrated enough for the branch-confidence formula to mean anything — these determine if the idea holds up. The author's suggested first step is narrow: pick a small domain like software install procedures and compare an LLM alone against the LLint setup on how often each reaches the right answer, flags leaps, and needs a human to step in.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
ServiceNow launched Flow, a natural-language service desk that handles employee requests inside Slack and Micr…
DeepSeek and Huawei announced a partnership to develop semiconductor software, part of efforts to reduce China…
The AI Ataraxos beat Niemeijer, the most decorated Stratego player, with an 85 percent effective win rate over…
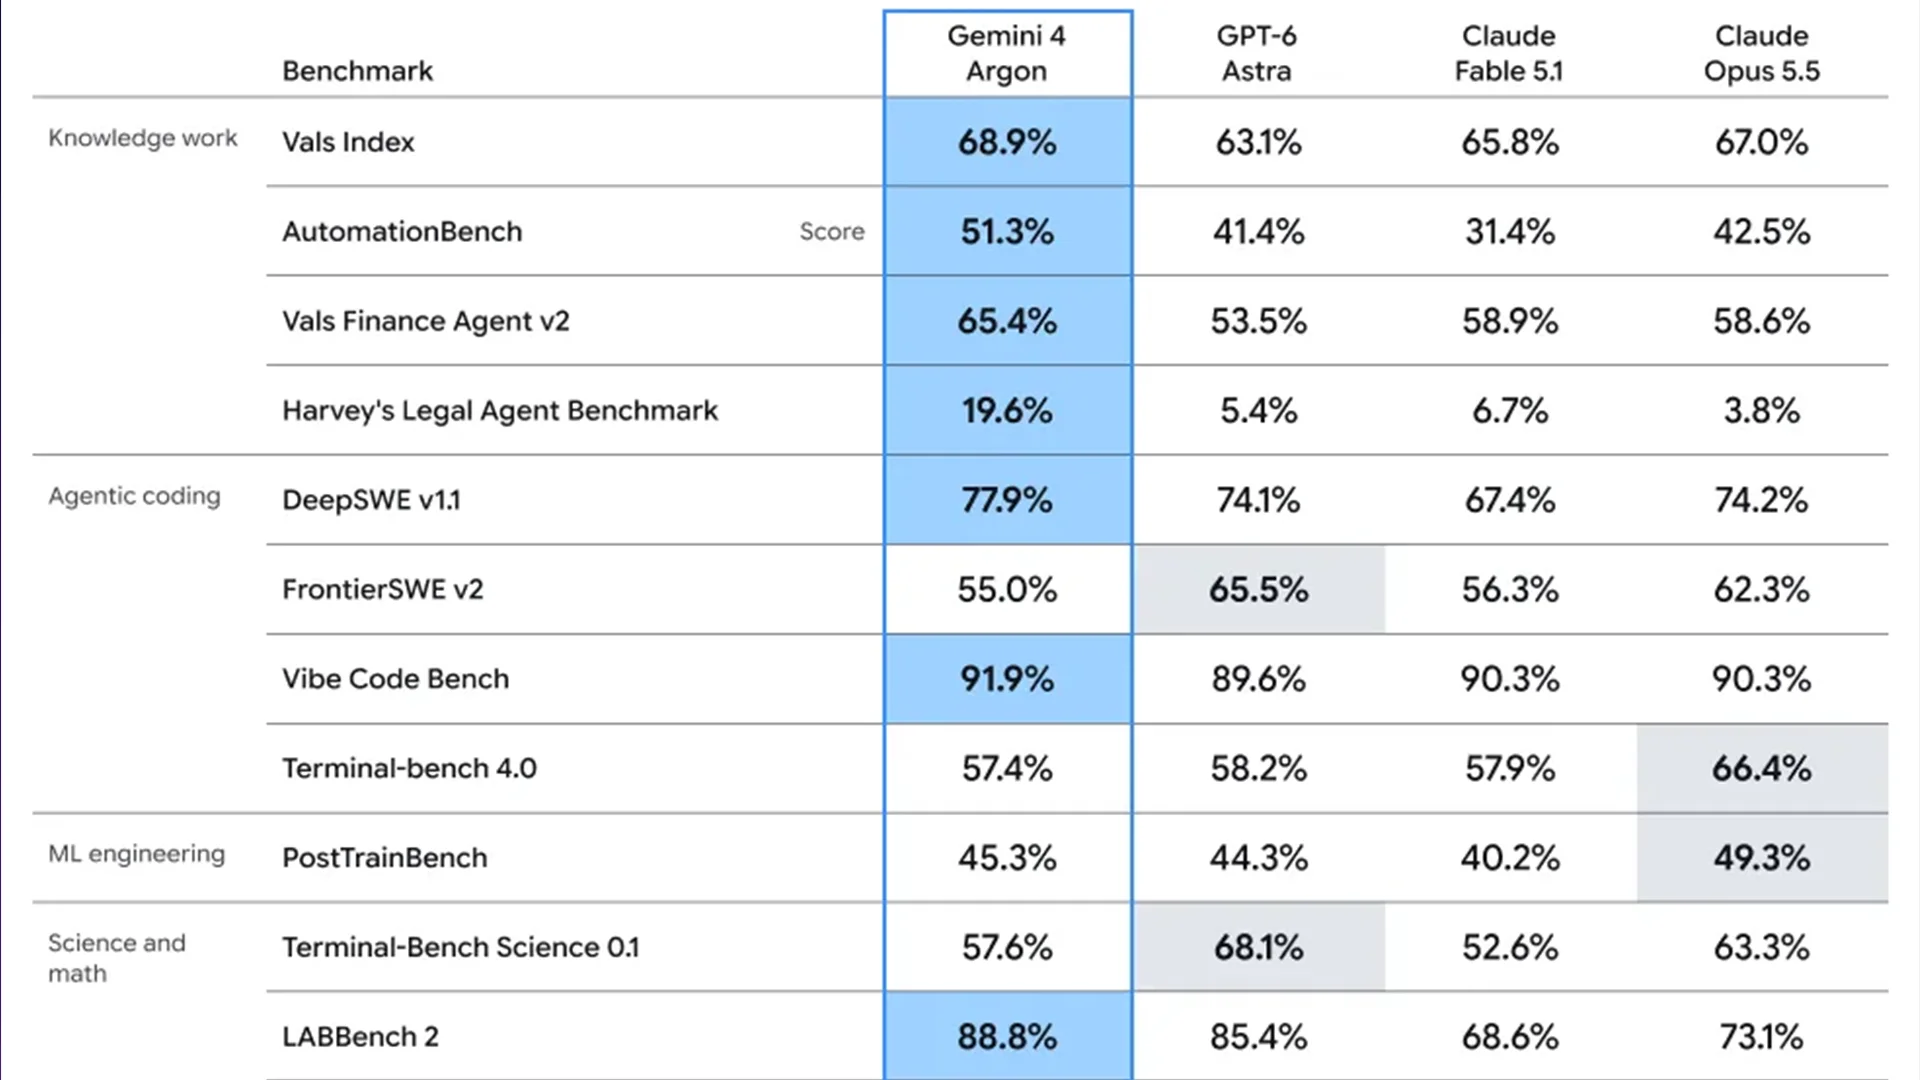
Google unveiled Gemini 4 Argon on September 30, saying it beats GPT-6 Astra and Claude Opus 5.5 on 13 of 19 be…
Yann LeCun told Fortune’s Emily Forlini he has zero concerns about rogue AI incidents, including OpenAI agents…
A Preply survey of over 5,000 professionals in nine countries found 92% of Gen Z respondents used AI for learn…