What happened
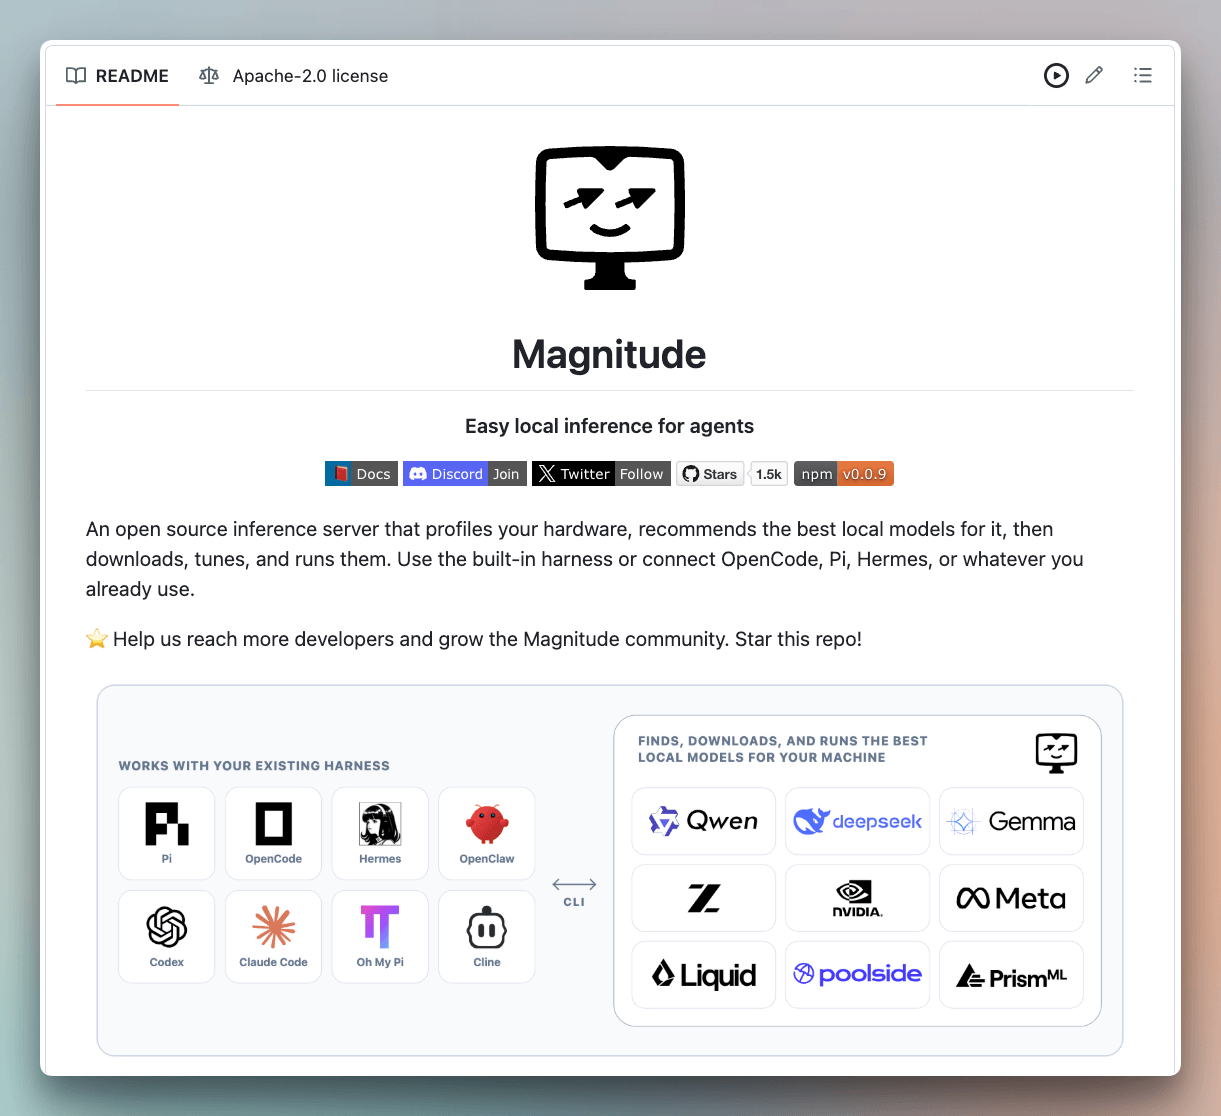
Magnitude, an open-source inference server, profiles your hardware and recommends the best model configuration. In a test on an Apple M5 with 16GB, it suggested Gemma 4 E2B at 4-bit QAT, predicted at 43–51 tokens per second.
Why it matters
Agent work is slower and less forgiving than chat because it accumulates long conversation histories and needs high precision. Magnitude solves the "which model to run" problem that existing tools leave to users, saving time and avoiding mistakes.
What to watch
The tool measures memory bandwidth, which predicts generation speed, and it handles setup for harnesses like Pi and Codex. It also offers configurations for balanced, smartest, or fastest performance.
Summaries like this, in your inbox every morning.
The article argues that local model tools were designed for chat, not agent work. In agent use, the conversation history grows, memory bandwidth limits speed, and precision is crucial. Magnitude addresses this by profiling hardware.
It measures memory bandwidth, which predicts generation speed, and runs test inferences to account for real-world behavior. It then recommends complete configurations, including model, compression, context size, and expected speed range, sorted by balanced, smartest, or fastest.
The test on an Apple M5 showed Gemma 4 E2B at 4-bit QAT as the balanced pick, holding 50K context in 4.6GB, predicted at 43–51 tokens per second. The tool also handles concurrency and speculative decoding automatically. In a real test with wifi off, it correctly identified no PII in client files, confirming it ran entirely locally.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Market expectations for cloud AI demand have stayed bullish through 2028-2029, and order visibility extends cl…
Google Cloud on Oct. 20 released a preview of Gemini for government services, co-developed with Missouri's sta…
Meta's Muse, launched last month, became the first popular AI agent for mainstream users and just cracked a do…
NVIDIA announced the OpenShell Reference Architecture, combining Vera Rubin for model inference, Vera CPUs for…
Voxel51 released version 3.0 of its robotics data platform, including Voxel51 Agent, which performs tasks like…
OpenAI acquired Orchestra Bio, a startup that helps pharma teams coordinate drug development, and will fold it…