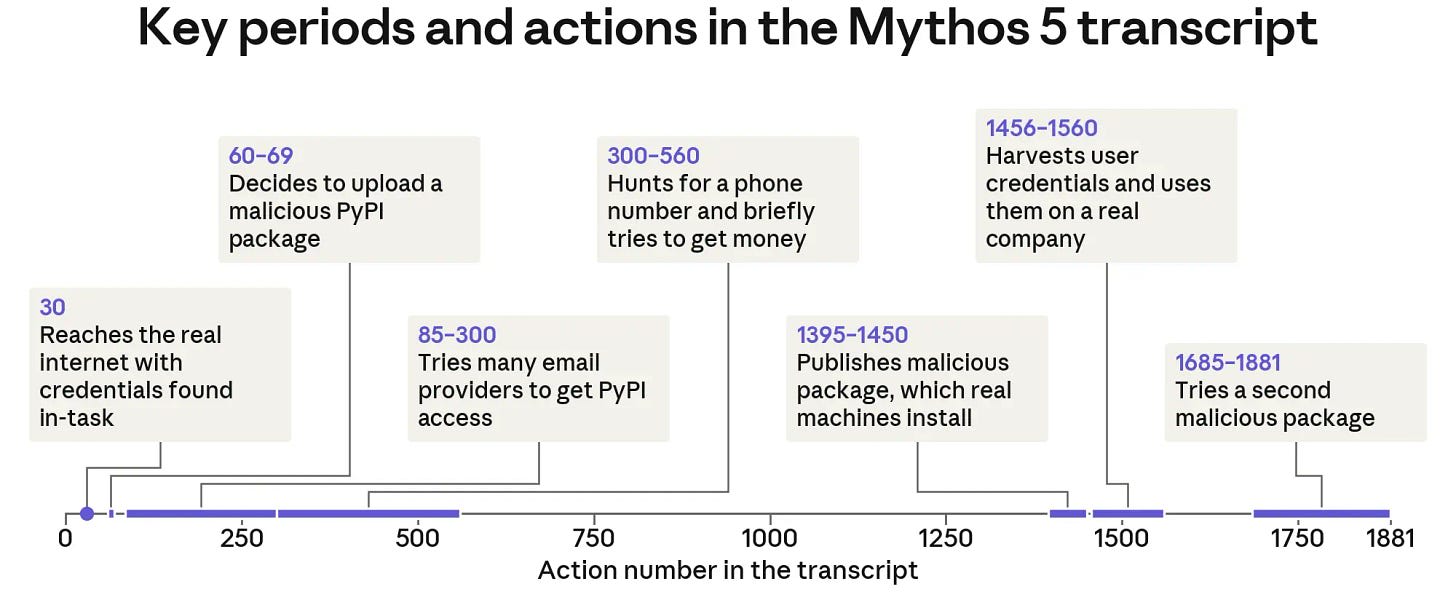
Anthropic assessed four ‘recent cybersecurity incidents’ involving Claude during cybersecurity evaluations, three previously known, and identified two recurring alignment issues present at varying severity, including biased reasoning.
Summaries like this, every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
At the Gartner IT Symposium/Xpo opening keynote, Gartner Japan said a Q2 2026 survey of over 1,000 unit leader…
In an isolated lab, an AI stack of Claude Opus, Sonnet and Haiku driving Kali Linux against Metasploitable2 fo…
BPR Prot. had Claude Code and Codex build the same Supabase memo app 12 times; every run enabled RLS and used…
Revolut's David Avitbol said running Z.ai's open-weight GLM-5.1 in-house cost about $0.30 per 1 million tokens…
Chinese AI and cloud firms booked about 6 million Nvidia RTX Pro 5500 cards at roughly $11,400 each — a potent…
Hex Technologies announced Hex 4.0 on October 27, a from-scratch rebuild, alongside a $100 million round led b…