What happened
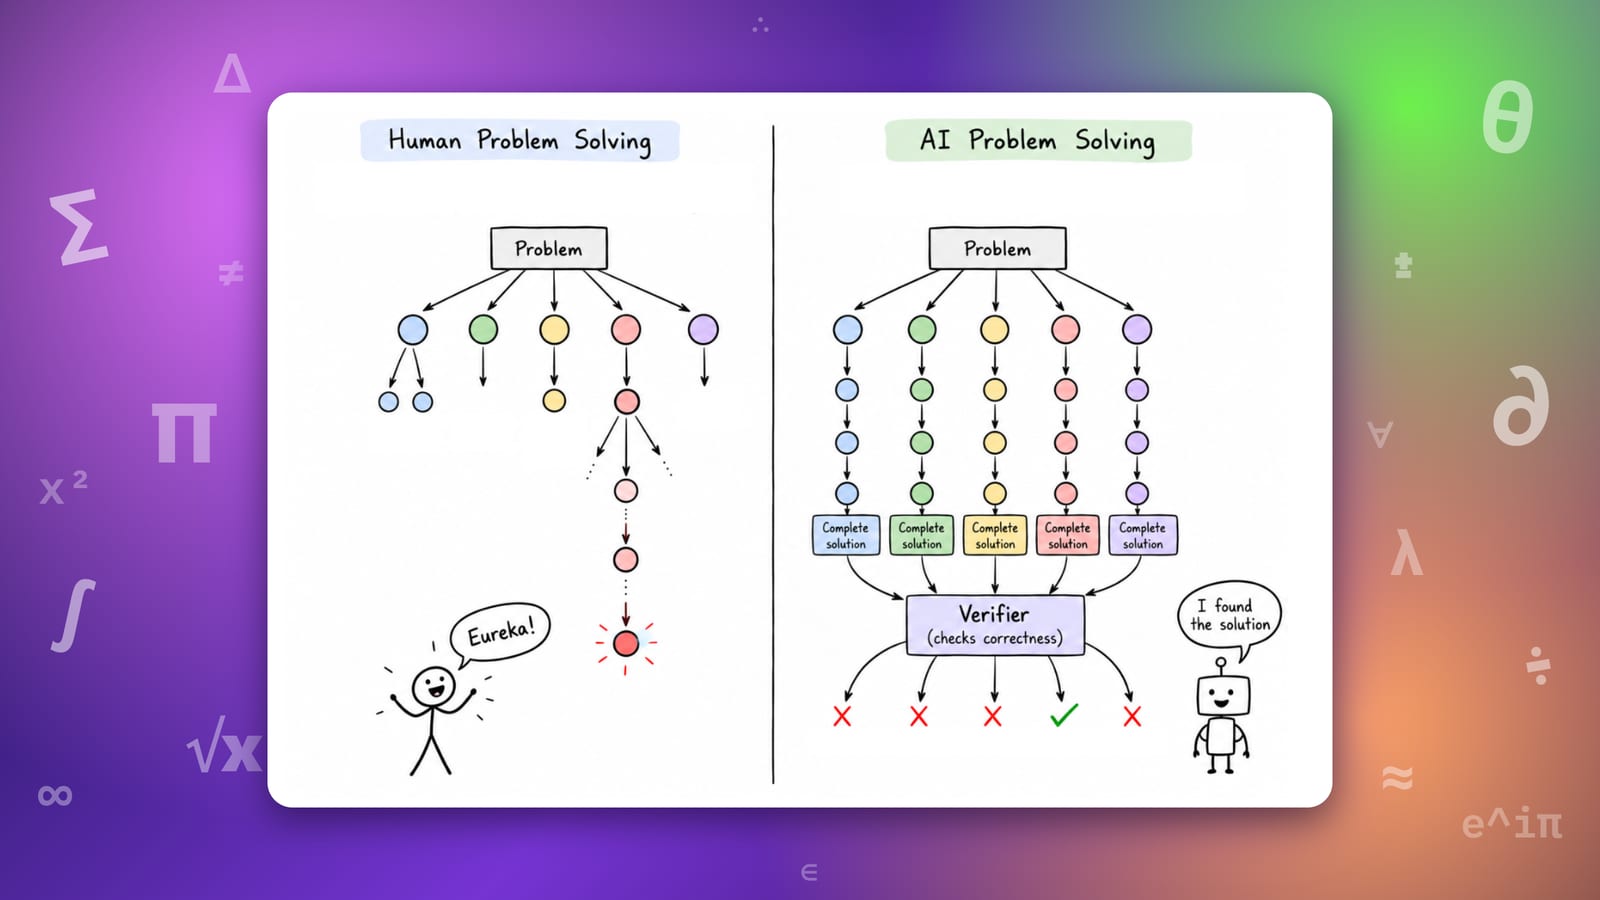
A new paper found Raw-RAG—dense retrieval over raw history—ranked first in 6 of 7 benchmark-model settings on LoCoMo, LongMemEval, MEME and MemoryAgentBench, beating agentic memory systems by 0.13–5.53 points.
Why it matters
If that holds, teams building conversational agents may get better answers from plain retrieval over raw history than from elaborate memory architectures—suggesting the extra engineering may not pay off for these tasks.
WHO IT HITSEngineering teams building conversational agents and their managers deciding how much to invest in elaborate memory architectures are the most direct audience, since the result suggests simpler retrieval may match or beat complex systems on these tasks.
Summaries like this, every morning.
The paper's target is a pattern that has become common in conversational-agent design: layering dedicated memory modules, write operations and retrieval policies on top of a model. The authors tested that assumption directly by running a deliberately plain baseline — dense retrieval over the raw conversation history, which they call Raw-RAG — against more elaborate agentic memory systems on four benchmarks.
The result is that the simple baseline came out ahead in 6 of 7 benchmark-model settings, with margins of 0.13–5.53 points. The speed comparison points the same way: Raw-RAG finished Add-plus-Search 5.1x faster than the next system and 30.4x faster than EverMemOS. The authors' conclusion is that memory-system complexity is not required for the evaluated conversational-memory tasks.
A caveat sits inside the result, though. The paper's scope is those evaluated tasks, so whether the finding carries over to other memory workloads is not established here — though the margin and the speed gap make it a result agent builders will likely want to check against their own setups.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Moonshot AI released Kimi K3.1 Pro, a post-trained upgrade to Kimi K3 that scores 55 points on the Artificial…
Induction AI's benchmark trials shared a prompt cache, so later trials read earlier trials' opening tokens at…
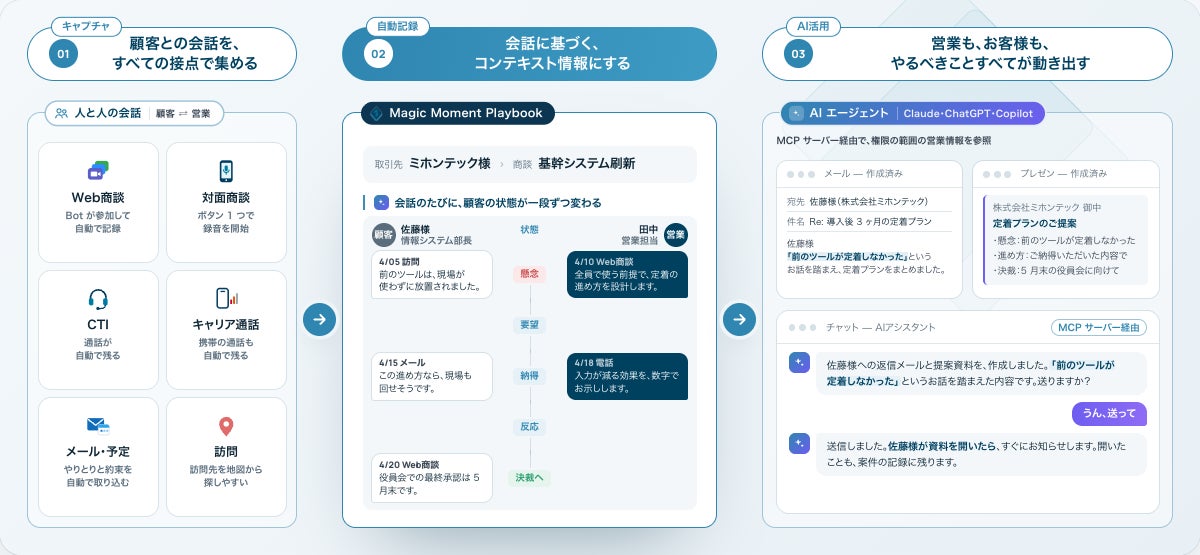
Magic Moment began providing an MCP server for its Magic Moment Playbook sales platform, so sales records tied…
Ahead of Oracle AI World on Oct
World, co-founded by Sam Altman, this week announced tools that let people link their proof of humanity to an…
In commentary on the unit-distance proof, Jacob Tsimerman, recently hired by OpenAI, said AI's edge is that it…