What happened
In a measured test on Ollama 0.40.4 for Windows 11, the qwen2.5:0.5b model (936 MB in ollama ps) stayed on the GPU 5 minutes by default; keep_alive = "30m" pushed UNTIL to 29 minutes, and keep_alive = "0" cleared it within 2 seconds.
Why it matters
Anyone sharing one GPU between local AI models and video editing or games can now control when VRAM is handed back, instead of watching GPU memory stay pinned and guessing the cause.
Summaries like this, every morning.
The test targets a practical gap in local AI tooling: loading a model into VRAM is visible, but the unload schedule is not, and Ollama's own status output can mislead. Because ollama ps reports the UNTIL column as time remaining rather than the configured duration, the default 5-minute keep-alive shows up as "4 minutes from now", which the author initially mistook for a 4-minute setting. The same display quirk explains the other results: an explicit keep_alive of "30m" surfaced as "29 minutes from now", and a keep_alive of "0" produced an empty table only after a short delay.
The three scenarios map onto distinct workloads. The default suits occasional prompts; the 30-minute setting is aimed at workloads that call the model repeatedly and would otherwise pay a reload cost each time; and the "0" setting is for the end of a batch job, when the GPU should go back to other work. The author's suggested habit is to send one request with keep_alive: "0" when finished, rather than relying on the timer.
The measurement was run on Ollama 0.40.4 under Windows 11 build 10.0.26200, using qwen2.5:0.5b as a small test model that occupied 936 MB and ran 100% on GPU. Since the numbers come from one setup, users on other versions or hardware may see different timings, and the author frames the 1–2 second release lag as an observation rather than a fixed rule.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Moonshot AI released Kimi K3.1 Pro, a post-trained upgrade to Kimi K3 that scores 55 points on the Artificial…
Induction AI's benchmark trials shared a prompt cache, so later trials read earlier trials' opening tokens at…
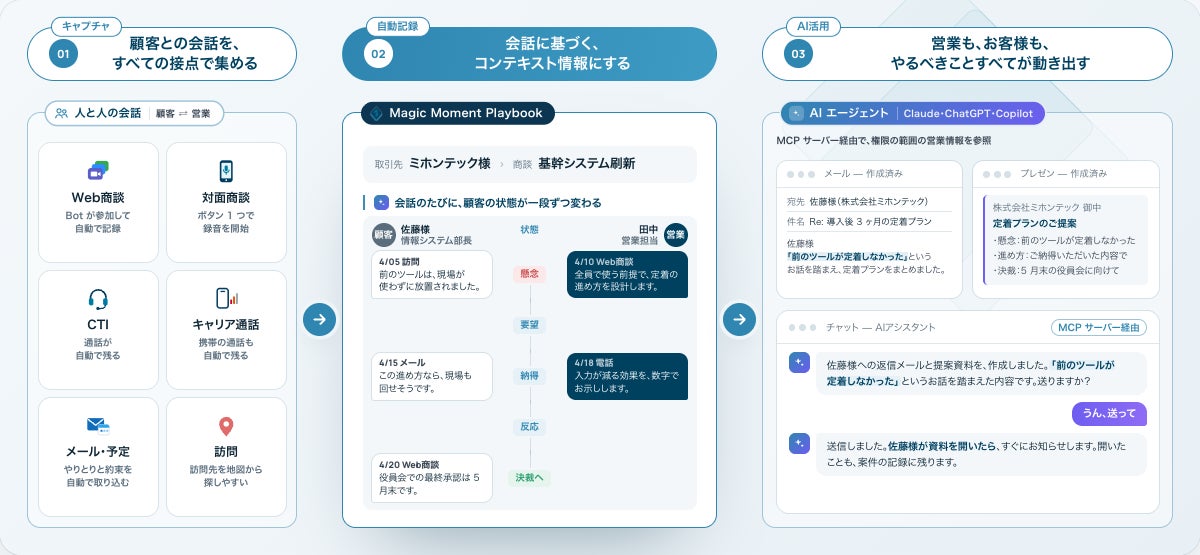
Magic Moment began providing an MCP server for its Magic Moment Playbook sales platform, so sales records tied…
Ahead of Oracle AI World on Oct
World, co-founded by Sam Altman, this week announced tools that let people link their proof of humanity to an…
In commentary on the unit-distance proof, Jacob Tsimerman, recently hired by OpenAI, said AI's edge is that it…