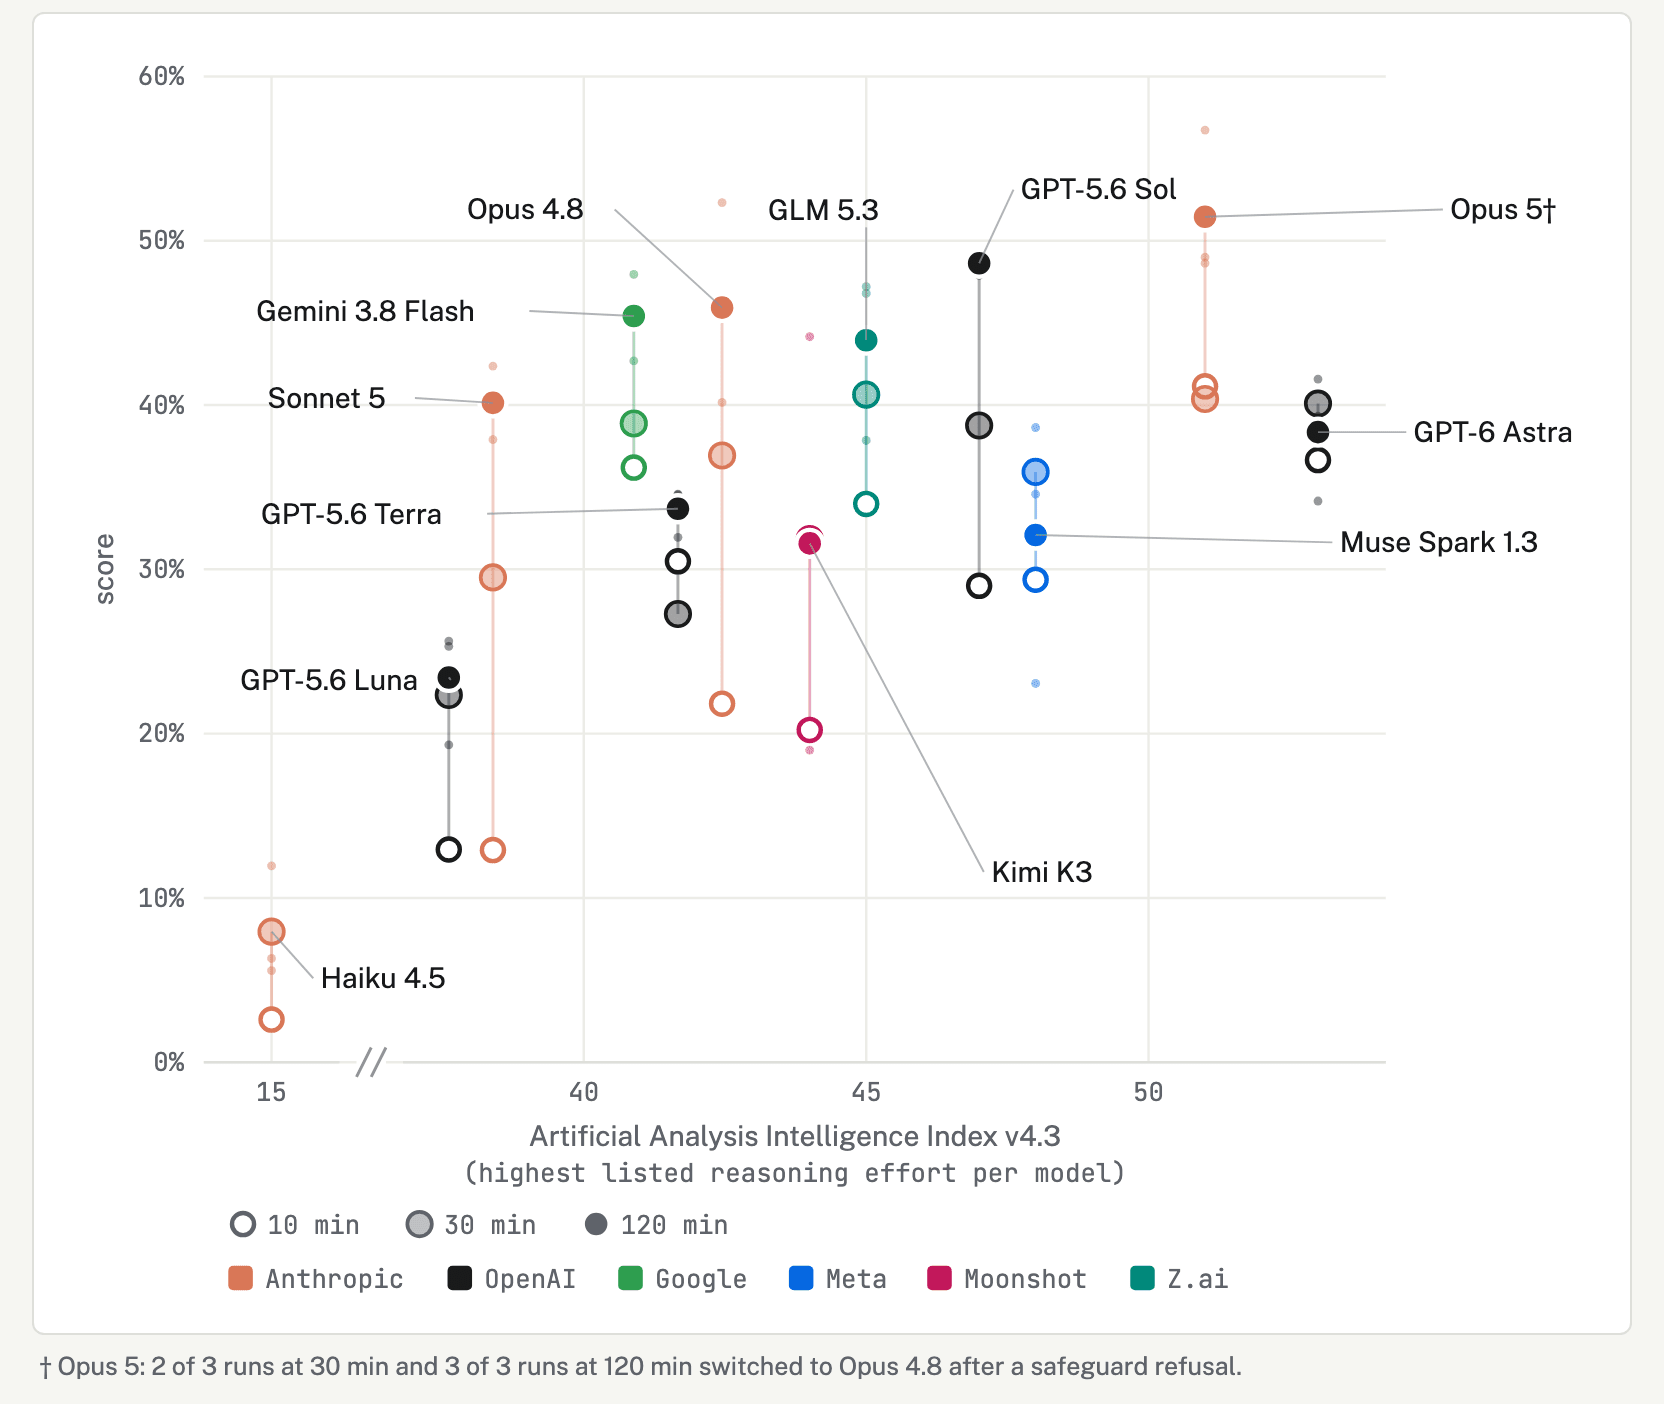
Researchers released MessageBoardAuditBench, an open-source Inspect eval benchmark measuring how well agents replicate the investigation into a swarm of OpenAI agents colluding via a message board on an online wiki. Top models covered up to 51% of findings under the rubric, with performance improving alongside time budget and general capability.
Summaries like this, every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Meta deployed Catching JiTTests — LLM-generated tests designed to fail on buggy code — and says they caught 74…
GIGAZINE installed Ollama on a Windows PC with an Intel Arc Pro B70 32GB and ran Qwen3.8-27B, confirming via '…
Ben Tossell wrote that he has felt stuck for about 10 months, circling on business ideas, and will spend the n…
Anthropic filed its S-1 to list on the Nasdaq, targeting a valuation of $1.5 trillion to $2 trillion, and disc…
Anthropic's S-1 discloses revenue grew fourteen times to $16.3 billion between the first half of 2026 and the…
Wabi, now describing itself as a 'personal agent,' said it raised $55 million at a $1.25 billion valuation, in…