What happened
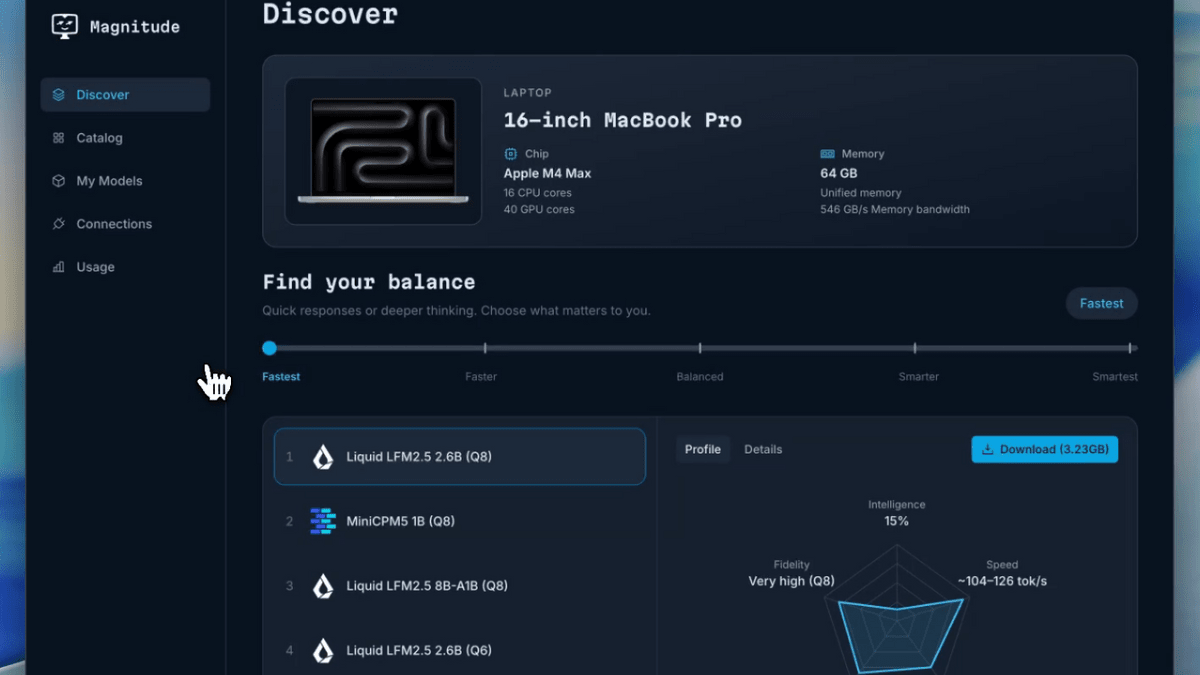
The Magnitude development team published an open-source inference engine that compiles and tunes model kernels on the PC itself, hitting about 2x llama.cpp's speed in certain conditions.
Why it matters
Running open models locally for AI agents has leaned on engines built for datacenter batching or broad hardware support, so Magnitude's on-device tuning looks aimed at a gap those tools leave.
What to watch
The headline 2x figure holds only in certain conditions, so the test is whether the gains repeat as the team adds Expert streaming and broader multi-device optimization.
WHO IT HITSDevelopers and small teams running AI agents on their own laptops or desktops are the most direct audience, since Magnitude targets exactly that setup. IT teams weighing local agent deployments may find the memory savings matter as much as raw speed.
Summaries like this, in your inbox every morning.
The Magnitude team's starting point is a mismatch between how inference engines are usually built and how local AI agents actually run. Datacenter engines are optimized for batching large numbers of requests, while projects like llama.cpp prioritize covering as much hardware as possible. Neither, in the team's view, fits a PC running an agent for a long time — a workload that involves repeated file reads, command execution, and often several agents at once.
Their answer is to compile the small computational units called kernels on the machine that will run the model, and to tune parameters there too. The reasoning is that even within the same Apple silicon or NVIDIA family, performance and memory layouts differ by product, so device-specific tuning can beat a generic kernel built for wide compatibility. The team's benchmark used a 4bit-quantized Qwen 3.6 35B A3B at a 64K token context, comparing against llama.cpp across both a Mac and an NVIDIA DGX Spark.
Beyond raw speed, the release addresses long-running and parallel use. Magnitude allocates only the memory needed to hold the model's weights, grows that region as a session lengthens, and frees it when an agent stops, while a shared prefix cache reuses computation for system prompts common across sessions. The team has also flagged what comes next: Expert streaming, a compiler that decides kernel configuration automatically, and optimization across CPU, GPU, RAM, and storage together. Whether the early gains hold as those features land is the open question.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
In the Loop host Ejaaz Ahamadeen broke down what Anthropic's (ANTH.PVT) leaked S-1 filing actually covers, and…
Boston Dynamics released Spot 5.2, expanding Orbit fleet software with a Model Context Protocol layer that let…
Anthropic launched Claude for Government for US federal and state civilian agencies
Emails obtained by The New York Times show two employees told OpenAI executives that AI models were not proper…
A DevOps engineer says he finished his "PersonalAI Health Agent" project in 2 days with Hermes Agent and GPT 5…
OpenAI launched Dots at DevDay — friendly, always-on personal agents you can message or call like a human assi…