What happened
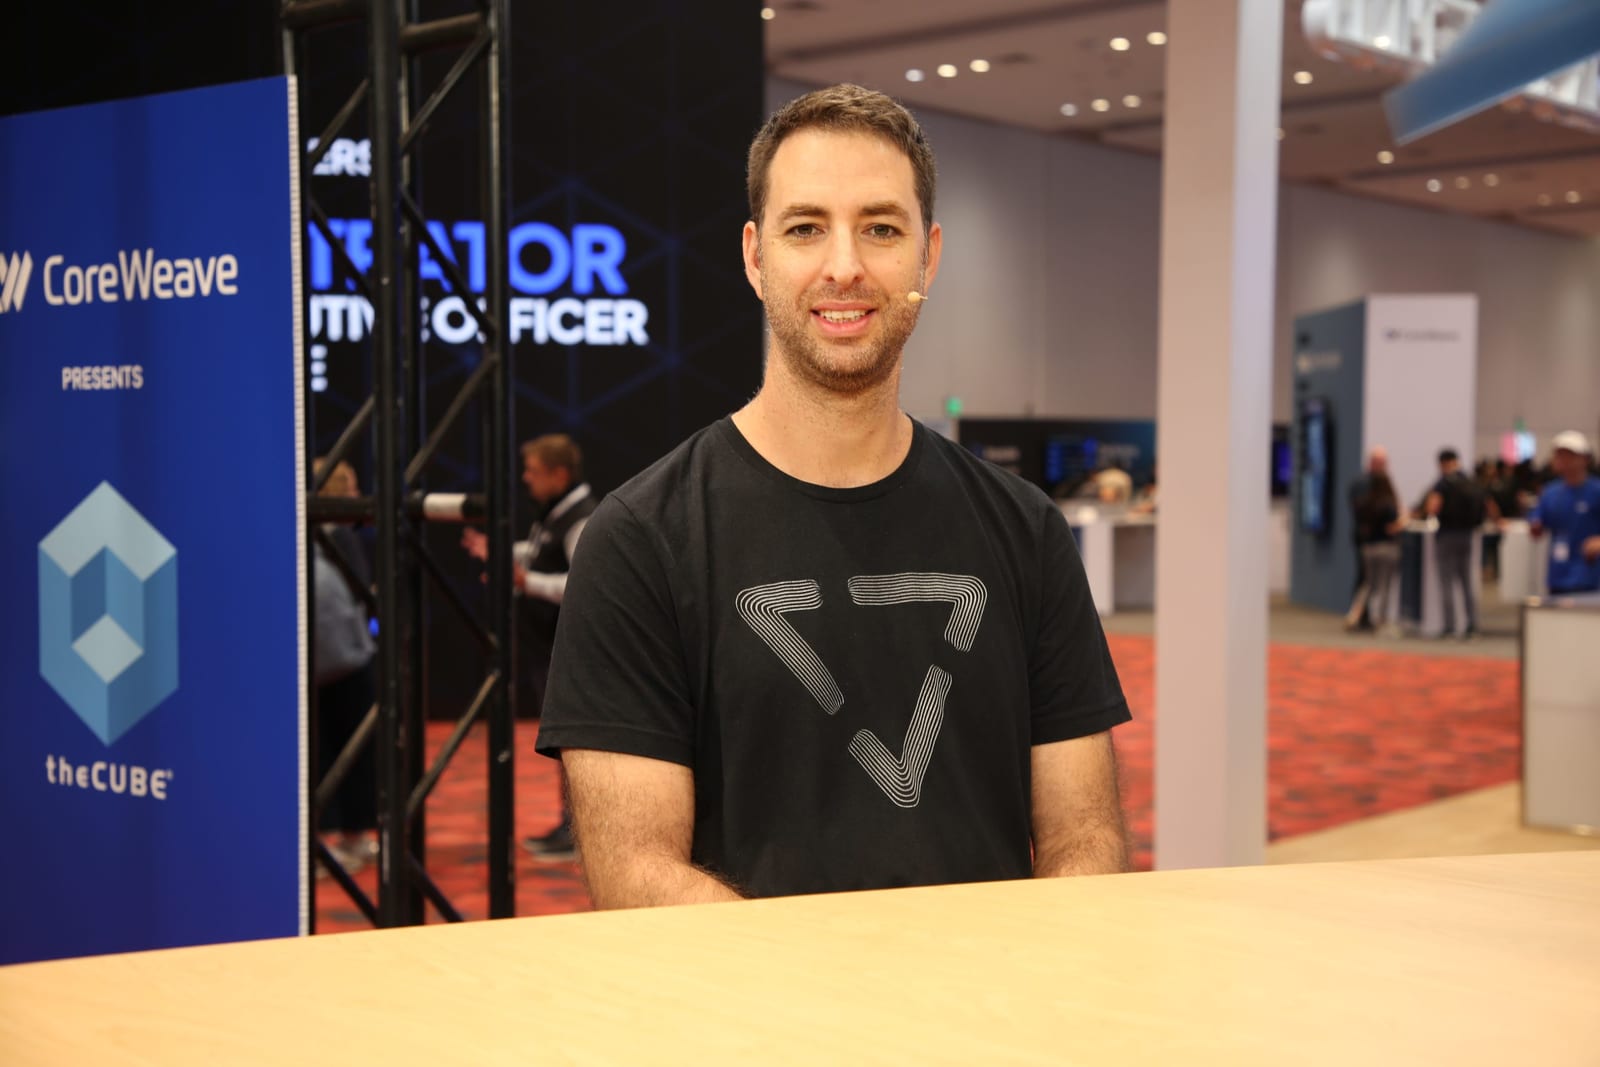
Alon Horev, co-founder and CTO of Vast, said at Fully Connected 2026 that agent sessions of half a million tokens can use one-tenth to one-twentieth of GPU memory, so Vast tiers KV cache across GPU memory, CPU memory, and persistent media holding petabytes, orchestrated by Nvidia Corp.'s Dynamo.
Why it matters
Long agent sessions can outlast GPU memory, so offloading KV cache to storage lets enterprises avoid repeat recalculation and schedule across a fleet, Horev said. He also argued agent conversations are governance and training assets.
What to watch
The approach hinges on whether enterprises with thousands of agents handling sensitive data actually adopt tiered storage and record everything their agents do. Vast has launched a confidential computing service for sensitive workloads.
WHO IT HITSEnterprise infrastructure teams running AI agents in production and storage buyers evaluating how to hold persistent agent context will face decisions about GPU memory limits and KV cache offloading. IT and compliance staff, especially those handling sensitive data, may need to record and retain agent actions.
Summaries like this, in your inbox every morning.
Vast's argument rests on a shift in how AI inference is expected to work. Horev described sessions that hold a KV cache in GPU memory and then go idle when the agent compiles code, tests software, or pauses for a person. Offloading a session to storage keeps that memory wall from forcing a repeat calculation, he said. The tiering order he outlined runs from GPU memory to CPU memory on the same machine to persistent media holding petabytes of KV cache, with Nvidia Corp.'s Dynamo software orchestrating the process.
Horev framed this as treating inference as a distributed problem across a fleet of machines. Moving a session from a busy GPU to a less busy one, and reading KV cache either over the network or from Vast, gives operators more optionality and more optimized scheduling, he said. That matters differently from ordinary context handling, he argued, because enterprise agents also need shared knowledge that persists across sessions, including long-term memory of past conversations.
He also tied agent memory to governance and training. Companies running thousands of agents that handle sensitive data and act for customers need to record everything those agents do and retain it for a set period, he said, and Vast has launched a confidential computing service for sensitive workloads. The stakes appear to hinge on whether enterprises adopt this tiered model at fleet scale and whether persistent KV cache proves to be as valuable as Horev suggests. Horev's claim that agent conversations are "gold" for fine-tuning, training, or purpose-built models is his view, not a stated benchmark.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
MasterClass Executive, MasterClass's new AI-native business program, runs a multi-agent system using about 10…
Taiwan's National Science and Technology Council (NSTC) has issued a call for proposals on "high-performance p…
Microsoft, Amazon, and Oracle disclosed huge contracted AI cloud backlogs: Azure at roughly $100 billion a yea…
NVIDIA said it plans to spend $12.9 billion, the largest acquisition in its history, to buy Hugging Face, wher…
Overview AI launched the OV Spark and OV Spark Pro, all-in-one inspection cameras with an onboard agent called…
Microsoft published Nobel Prize-winning economist Daron Acemoglu's forecast that AI will boost GDP by about 1.…