What happened
In a paper, Kirill Brilliantov, Alejandro Hernández-Cano, and Emmanuel Abbé report that under an equal time budget and the same frontier LLM backbone, open-source state-of-the-art harnesses provide no advantages over a single session of a minimal-harness coding agent baseline.
Why it matters
This suggests the underlying model, not the extra engineering layers, drives results on these benchmarks, so building out more supporting machinery may yield poor returns.
What to watch
Whether these findings extend beyond the current benchmarks the paper studies remains an open question; the test is whether the same minimal-harness approach holds up on other tasks.
WHO IT HITSThis affects enterprise AI teams and researchers who build or buy elaborate agent harnesses for machine learning tasks, since the findings suggest spending on extra orchestration and retrieval layers may not pay off under equal time and the same model backbone.
Summaries like this, every morning.
Autonomous machine learning engineering agents have made significant progress on public leaderboards. These systems are often deployed on top of increasingly elaborate machinery, including multi-agent orchestrators and dedicated retrieval subagents, motivated by long-horizon progress stagnation and limited LLM primitives. Meanwhile, the use of more primitive but improved coding agents—where the LLM has direct access to the execution environment through read, write, and bash primitives—has received little attention.
This paper fills that gap by running large-scale systematic ablation studies. The authors find that the machinery layers become redundant in the coding agent setting: under an equal time budget and the same frontier LLM backbone, open-source state-of-the-art harnesses provide no advantages over a single session of a minimal-harness coding agent baseline. They point to the backbone as the primary driver for performance and conclude that the effort spent elaborating hand-crafted harnesses yields poor returns for current MLE benchmarks.
The stakes hinge on whether these benchmark results generalize to other tasks and settings. For teams investing in agent scaffolding, the findings suggest the returns on extra orchestration or retrieval layers may be limited when the underlying model is strong, though further validation on other benchmarks would be needed to confirm this.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Sebastian Raschka published a technical walkthrough of positional embeddings in LLMs, covering learned absolut…
Meituan released the weights for LongCat-2.5, a 1.6-trillion-parameter agent model trained on Chinese hardware…
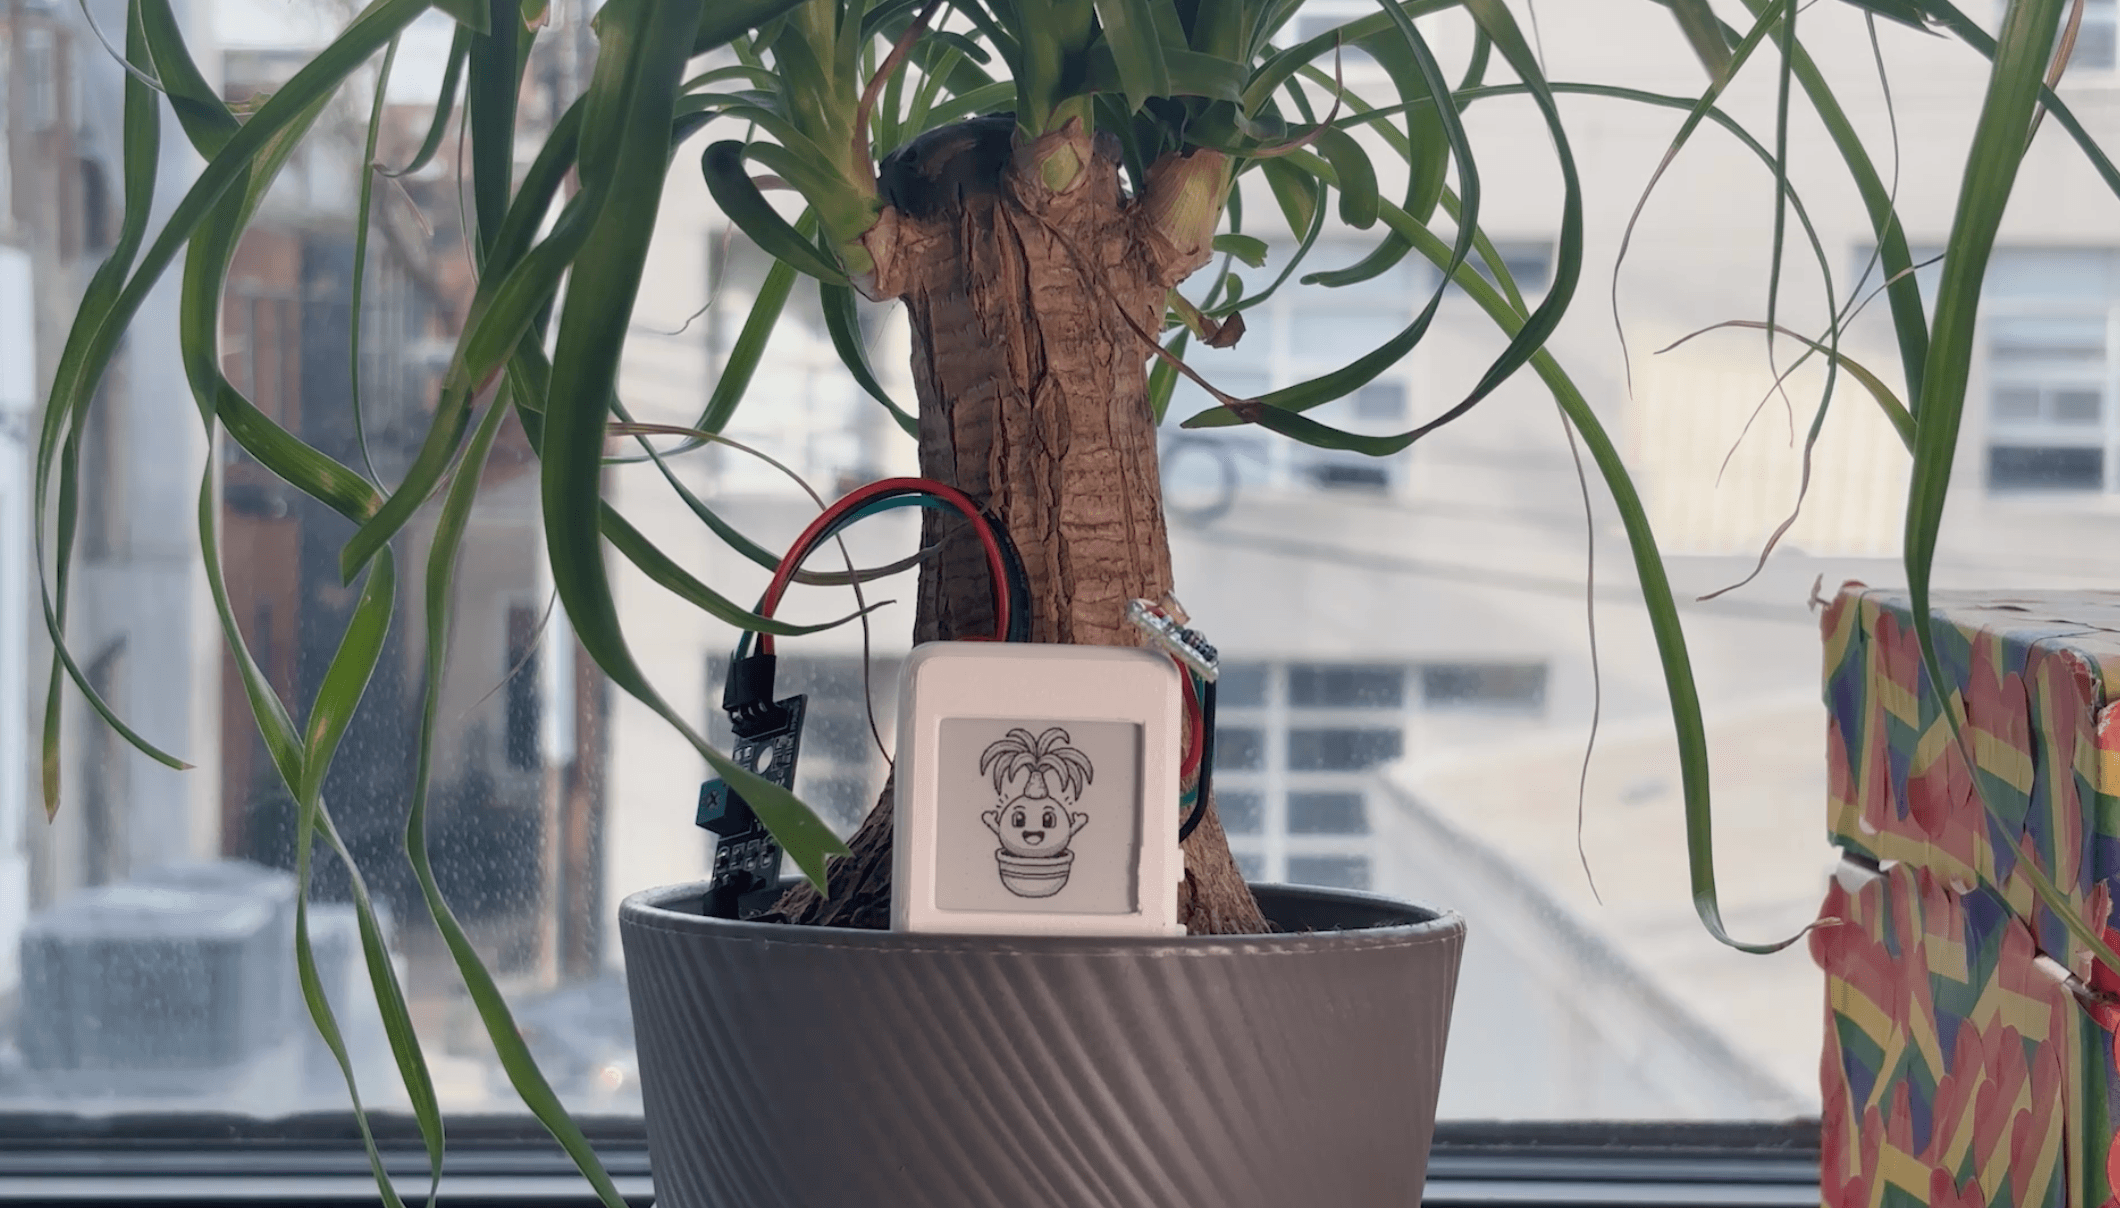
Daehwa Kim unveiled OATs, $20 E Ink modules that use sensors and Google Gemini's Nano Banana to give objects l…
Nvidia reports Tuesday, the Fed releases October minutes Wednesday, and Anthropic expects to price its IPO Wed…
In a November 9 note, Evercore ISI's Amit Daryanani said Apple's integration across apps, personal data, and A…
A free Zenn curriculum targets engineers who know basic C# syntax and walks them through building an inventory…