What happened
Given a roughly 8,400-character Japanese article and told to summarize it in 3–5 bullet points, gemma4:e4b responded in one pass in 93 seconds, while qwen3.5:9b took 178 seconds and returned zero characters of content, its entire output budget consumed by thinking.
Why it matters
Both models produced lengthy multi-section reports with emoji headings and tables instead of the requested concise bullets, so for drafting and summarization work users cannot rely on a simple 'be concise' instruction and likely need stronger constraints on output format and length.
Summaries like this, every morning.
This post is the sixth in a series that had previously covered only coding-related tasks, so it shifts the lens to drafting and summarization. The method was deliberately simple: the author fed a roughly 8,400-character technical article of their own into Ollama's API with no background load and asked for a 3–5 bullet Japanese summary.
The most striking result is not speed but the empty response from qwen3.5:9b. Its done_reason of "length" indicates the model consumed the entire generation cap on thinking, a failure the author says reproduced with the Ornith-family models in study4 and study5. Setting think: false fixed it, making the case that thinking-capable models used directly through an API carry a risk of blank output unless that flag is explicit.
On quality, both models were accurate in content but ignored the format instruction, producing long strategic reports with emoji headings, comparison tables, and even code blocks. The author's practical lesson is that 'be concise' alone does not work; prompts need hard limits on character count and output format. They also flag that the test was a single run on one task and that different document types or prompts could change the instruction-following results.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
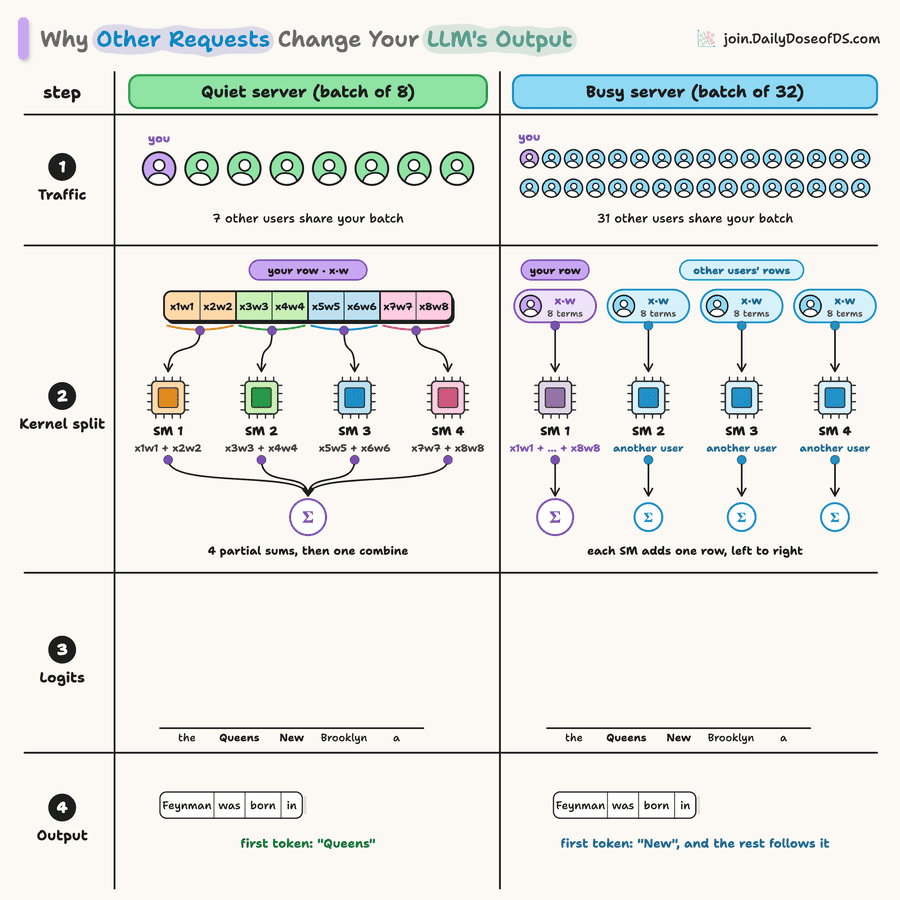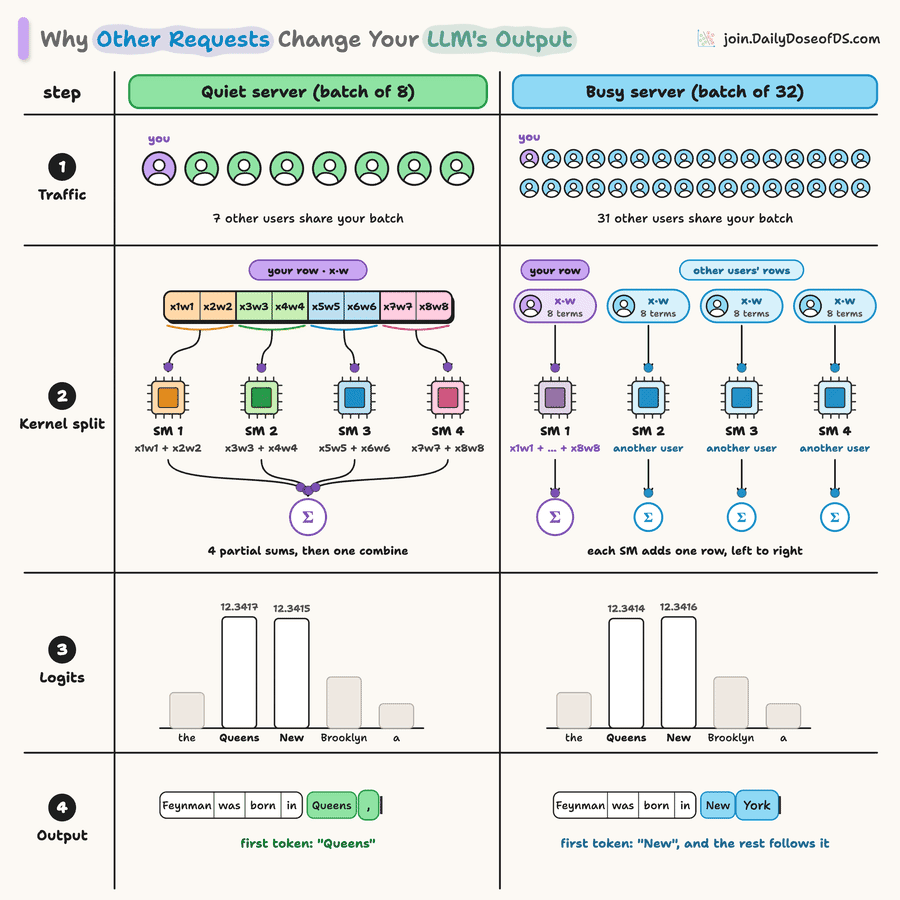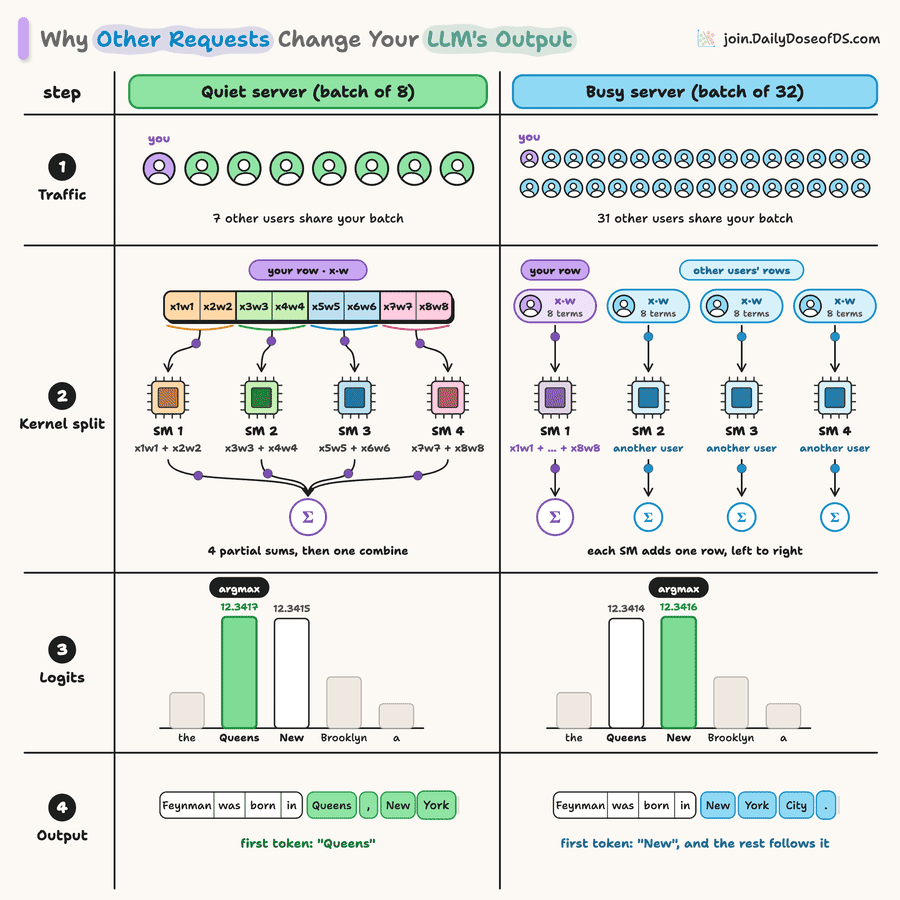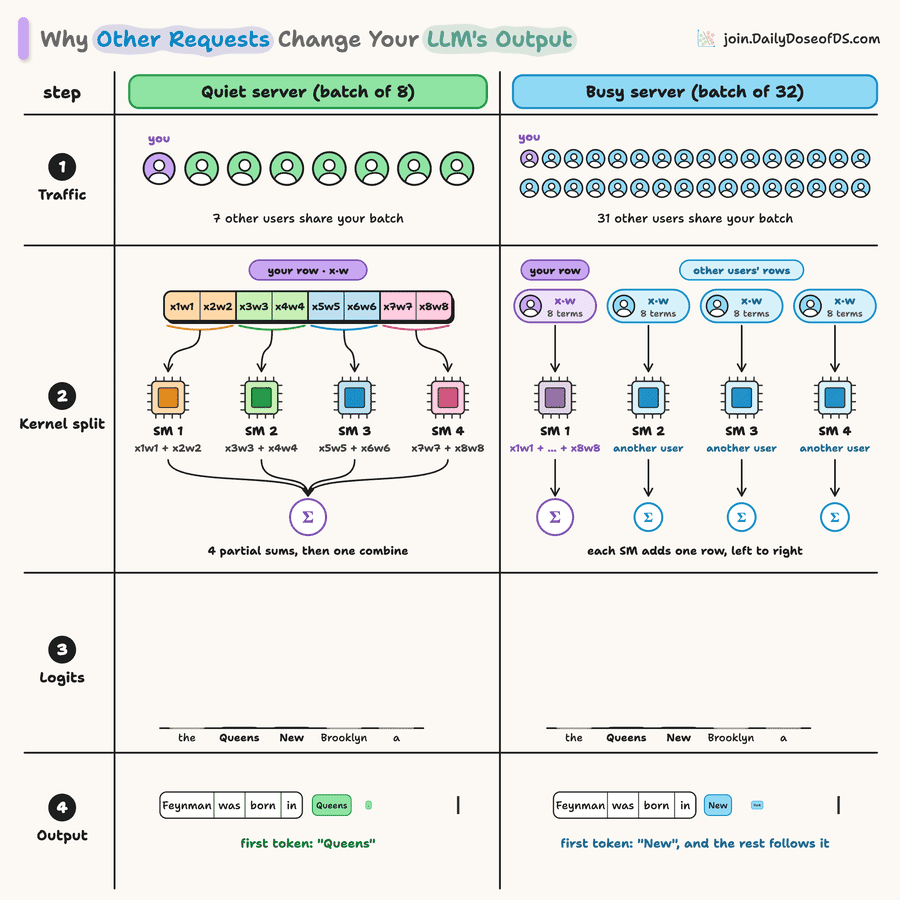
Thinking Machines Lab ran 1,000 completions of "Tell me about Richard Feynman" from Qwen3-235B at temperature…
Anthropic told API customers it will watermark Claude Mythos 5, Claude Opus 4.7, Claude Opus 4.6, and Claude S…
A walkthrough wires the open-source Hindsight memory system (vectorize-io, MIT license) into a plain Claude AP…
The book documents a working kit for scheduled Claude Code runs — a starter, task instructions, a STATE.md kep…
OpenAI told Trusted Access members that from November 29, Daybreak Blue session data will be used for training…
Arca, which recently raised $48.5 Million led by General Catalyst, built its own agent harness and a per-clien…