What happened
Nathan Langley (ninjahawk) of the University of North Carolina released livenerf, a benchmark built on Britain's AISI Inspect framework, to test whether AI models degrade after launch. It has run on Claude Opus 5.5 since its September 22, 2026 release.
Why it matters
Livenerf focuses on the 78 questions Claude Opus 5.5 sometimes gets right and sometimes wrong, where accuracy sits near 50%, so shifts there may be a cleaner signal of real decline than user complaints alone.
What to watch
Livenerf uses the first 10 days after release as a baseline and then tracks the following 10-day average, and it runs on the subscription version of Claude Opus 5.5, so results may not match the raw API model. Some biology and math questions were refused by safeguards and show as blank.
WHO IT HITSThis lands on teams that rely on subscription or API AI models for production work, since livenerf offers a way to check whether a model they depend on is quietly changing after release. It also gives model providers a public yardstick they may be measured against.
Summaries like this, every morning.
Complaints that an AI model has gotten worse after launch are common, but they can stem from several things: quantization to cut running costs, shrinking the model, lower thinking effort, or routing changes. They can also be pure perception, where experienced users start noticing only the bad answers. Livenerf tries to separate those cases by collecting clean test data continuously from a model's release date, so the question of whether a model truly degraded can be argued with evidence rather than impressions.
The benchmark is built on Inspect, the open-source evaluation framework published by Britain's AI Security Institute, and it deliberately avoids questions a model always gets right or always gets wrong. Instead, it watches the ones a model sometimes gets right and sometimes wrong, where a real drop should be easier to see. For Claude Opus 5.5, that means 78 questions sitting near 50% accuracy.
The current read is that Claude Opus 5.5's accuracy moved up and down day to day from September 24 to 30 but stayed within a band. Livenerf's method is to set a baseline from the first 10 days after release and then track the next 10-day average, so a clearer verdict depends on that comparison playing out. One caveat is that livenerf runs on the subscription version of Claude Opus 5.5 rather than the raw API model, and some biology and math questions were refused by safeguards and left blank, which may limit how completely the results reflect what developers actually use.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Microsoft hosts Ignite from Nov
PostgreSQL 19 RC2 was published on November 12, after beta 4 in late September reverted features including SQL…
On November 12, Google launched Gemini 4 Hydrogen, aimed at everyday coding and multi-step agent tasks, and it…
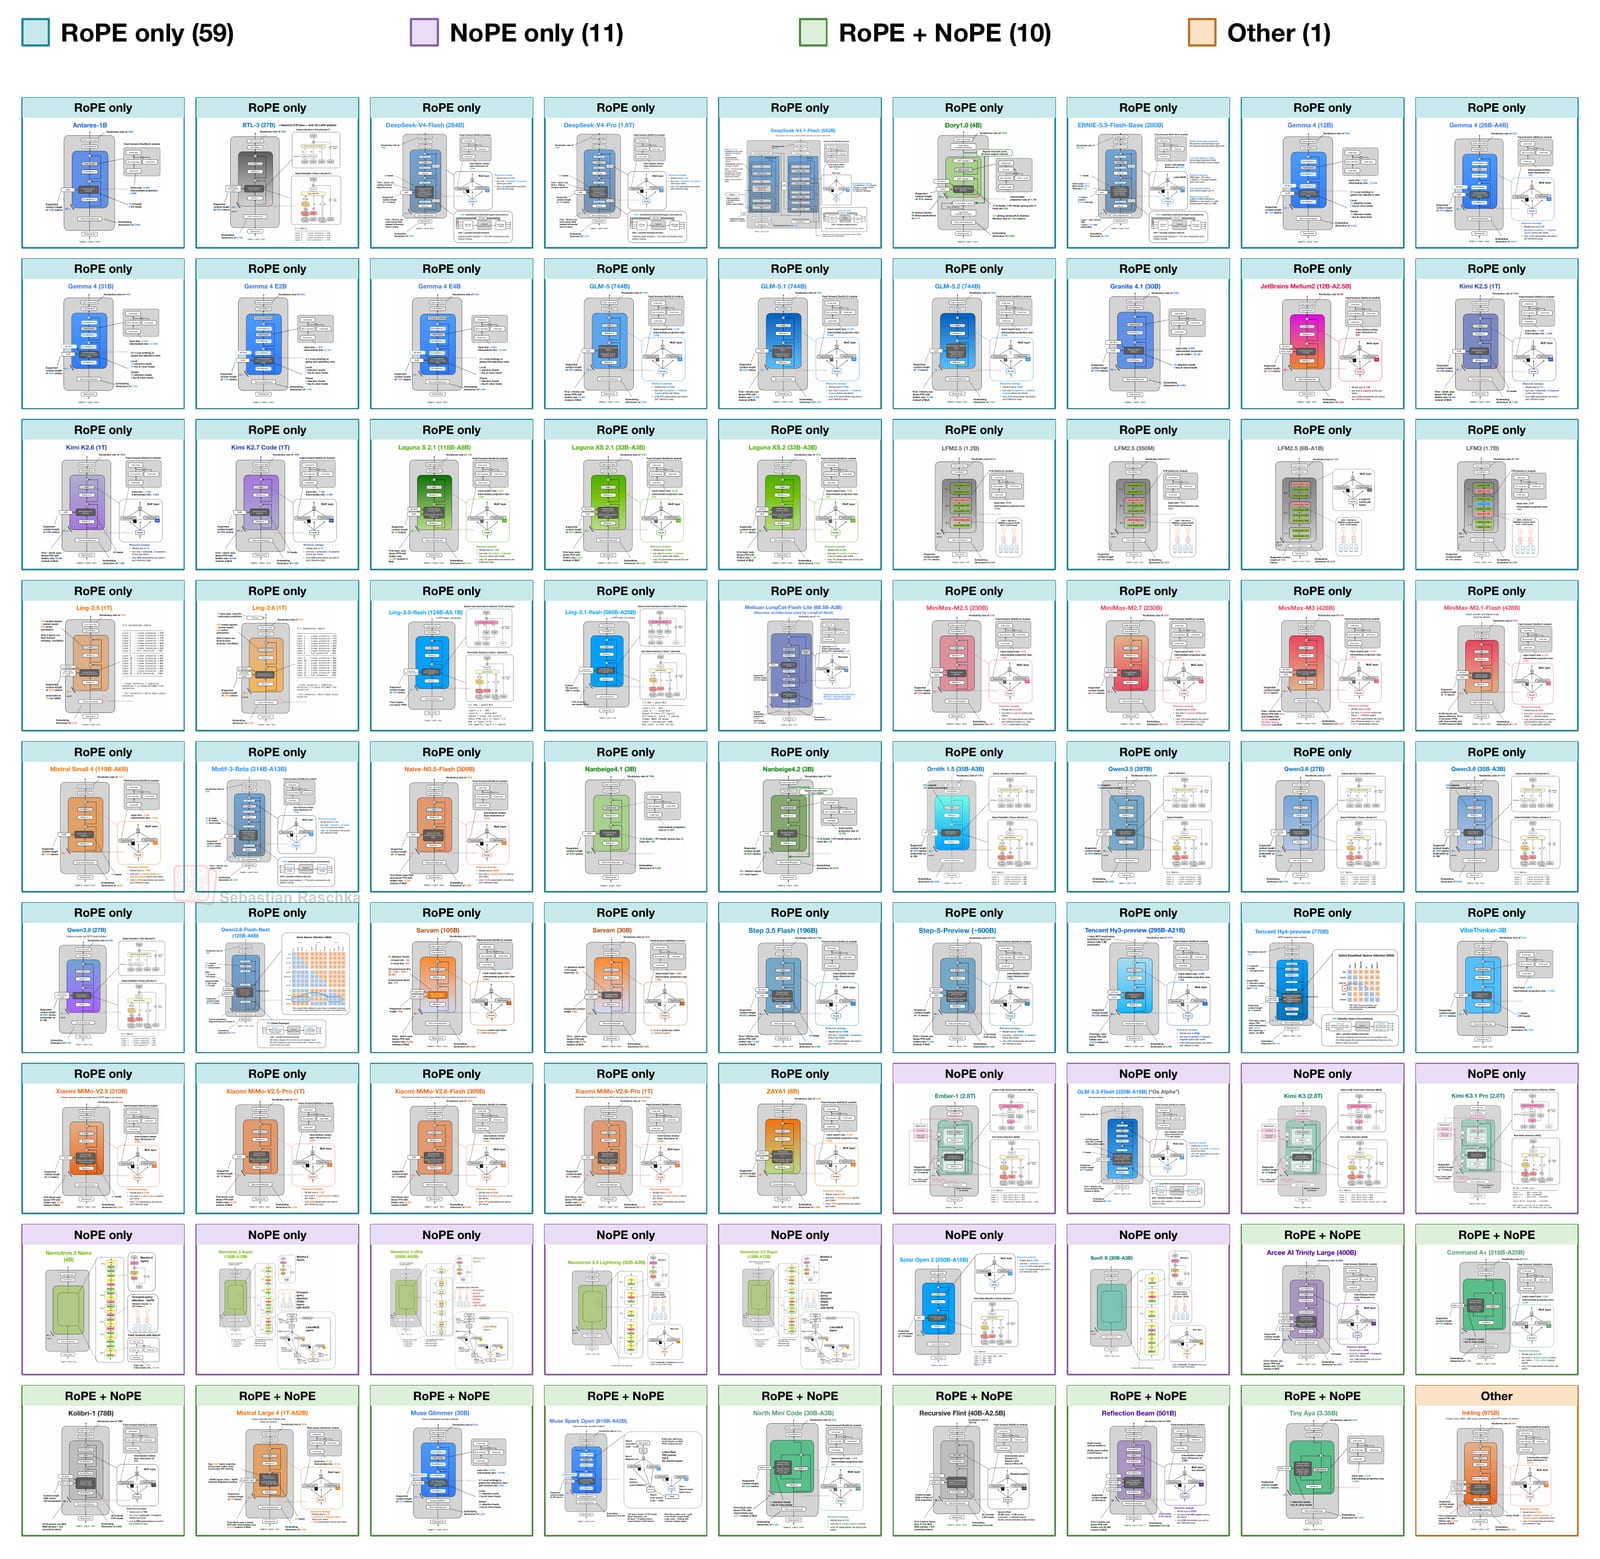
Sebastian Raschka published a technical walkthrough of positional embeddings in LLMs, covering learned absolut…
An RBA analysis by Mike Major found job postings fell across all groups since ChatGPT launched in late 2022, w…
Meituan released the weights for LongCat-2.5, a 1.6-trillion-parameter agent model trained on Chinese hardware…