What happened
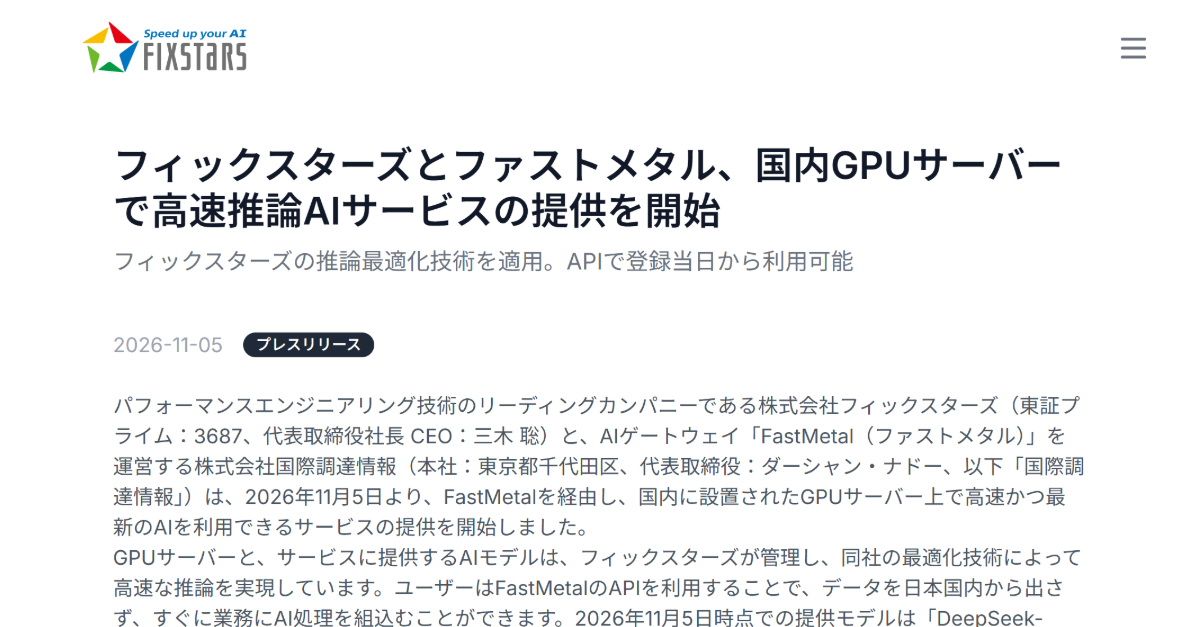
Fixstars said on Nov 5 it began offering open-weight models on GPU servers in Japan, working with Kokusai Chotatsu Joho; the first model is DeepSeek's DeepSeek-V4.1-Flash-1017, delivered through the FastMetal API.
Why it matters
Input data is processed only on Fixstars' domestic GPU servers, which the company says do not store input or output data — a setup likely aimed at firms wary of sending data abroad.
WHO IT HITSJapanese companies that want to use open-weight AI models but need data to stay inside the country — particularly legal, medical or public-sector IT teams — get a domestic option, though the model lineup currently starts with a single DeepSeek model.
Summaries like this, every morning.
The service pairs Fixstars, a software developer based in Minato, Tokyo, with Kokusai Chotatsu Joho, a domain-registration and procurement-information company in Chiyoda, Tokyo. Fixstars handles the GPU servers and the management and optimization of the AI models, while access is delivered through Kokusai Chotatsu Joho's AI gateway service, FastMetal.
The arrangement splits the work so that the model runs on hardware inside Japan. Fixstars says input data is processed only on its domestic GPU servers, that its technology speeds up the AI processing, and that the servers do not retain input or output data. For buyers, that combination of domestic processing and no data retention is likely to be the main draw.
Commercial terms are published up front: 48 yen per 1 million input tokens, 192 yen per 1 million output tokens, and 0.96 yen for cache reads. Fixstars says it intends to add more models beyond DeepSeek-V4.1-Flash-1017, so the breadth of the catalog may be the thing to watch as the service develops.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Hitachi Energy is expanding its partnership with Celonis, the process-intelligence leader, to scale AI use acr…
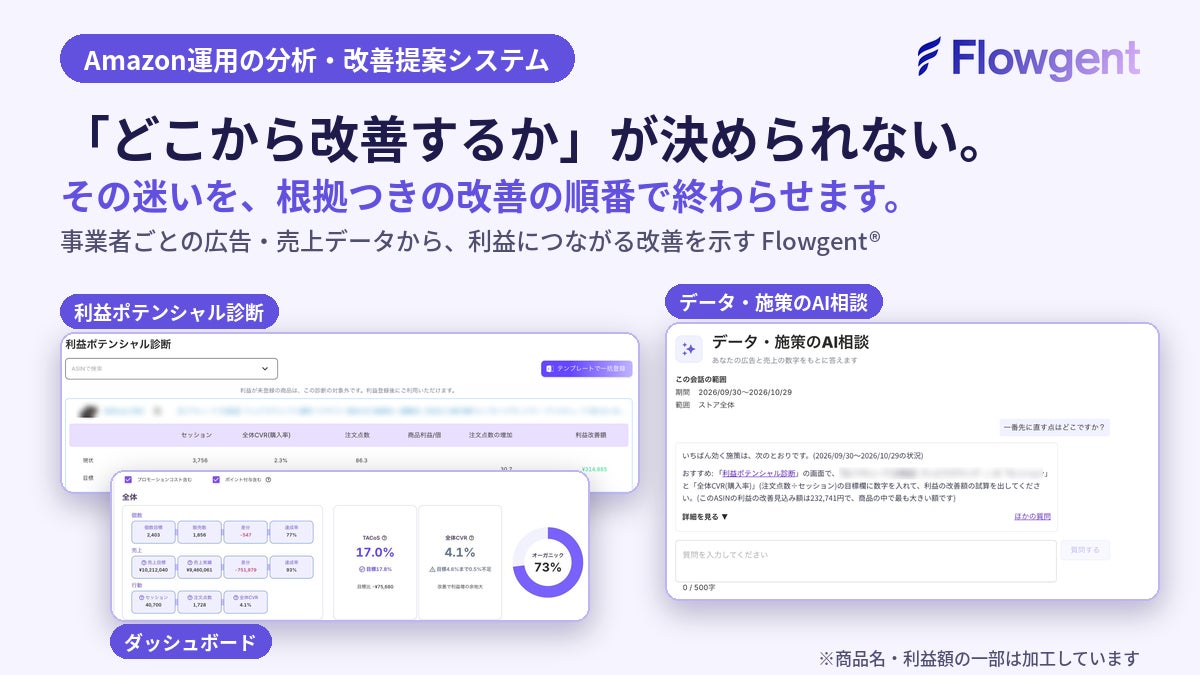
Spesia added an "AI consultation on data and measures" chat to Flowgent, its Amazon operations analysis system
In Branding Works' October 2026 survey of ChatGPT and Gemini answers, 辻・本郷税理士法人 appeared in 50% of responses…

At its Global Brand Launch on October 21, LUXEED introduced the LLounge MPV and Stormax SUV, both with AI smar…
Metanomaly launched the beta of "Jashin-chan Loid P (AI Jashin-chan Chat)" on November 6; the first 10 convers…
Box announced Box for Industries, an industry-specific solution set, and began offering Box for Banking, Box f…