What happened
HPE says a hybrid AI platform routing routine work from more than 150 internal applications to open-weight models on HPE Private Cloud AI cut token costs 30 to 50%.
Why it matters
It suggests owning inference capacity can make heavy AI coding use cheaper per unit of work, though HPE notes owned capacity carries power, operations and maintenance costs of its own.
Summaries like this, every morning.
The pitch arrives as per-token pricing turns agentic coding into a budget problem. Uber reportedly exhausted its entire 2026 AI budget by April after expanding Claude Code use, and GitHub Copilot has moved from flat-rate pricing to metered credits. HPE's answer is not to cap usage but to change who owns the capacity: reserve frontier models for difficult planning, and route code generation, test creation and repeated refactoring to open-weight models run on premises.
The economics cut both ways. Rented inference adds to the bill with every call, while owned capacity commits most of the cost upfront and gets cheaper per call as usage grows — though power, operations, maintenance and depreciation still count. HPE's own deployment, spanning more than 150 internal applications, is presented as evidence the model works, with token costs down 30 to 50%.
Usage concentration complicates budgeting. The top 5% of users generated most of the consumption, and if power users grow from a small minority to half the workforce, monthly spend can rise about 4.4 times with flat headcount. That is why HPE ties its metrics to shipped software rather than consumption alone, and it concedes owned capacity is not for everyone: low or unpredictable usage still favors APIs.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
In the Civ50 run, 50 GPT-6.1 Sol agents in Minecraft exchanged about 5,900 messages but turned cautious after…
OLA PARTY JAPAN's Yoitoki made its AI matchmaker voice interview available to all users from October 4, with r…

Munich-based Marble Cognition launched with $3.75 million in pre-seed funding led by Heartcore and Seedcamp, w…
TorqueAGI founder Dr Ashutosh Saxena said its World-Reasoning Model handles new tasks with a few dozen example…
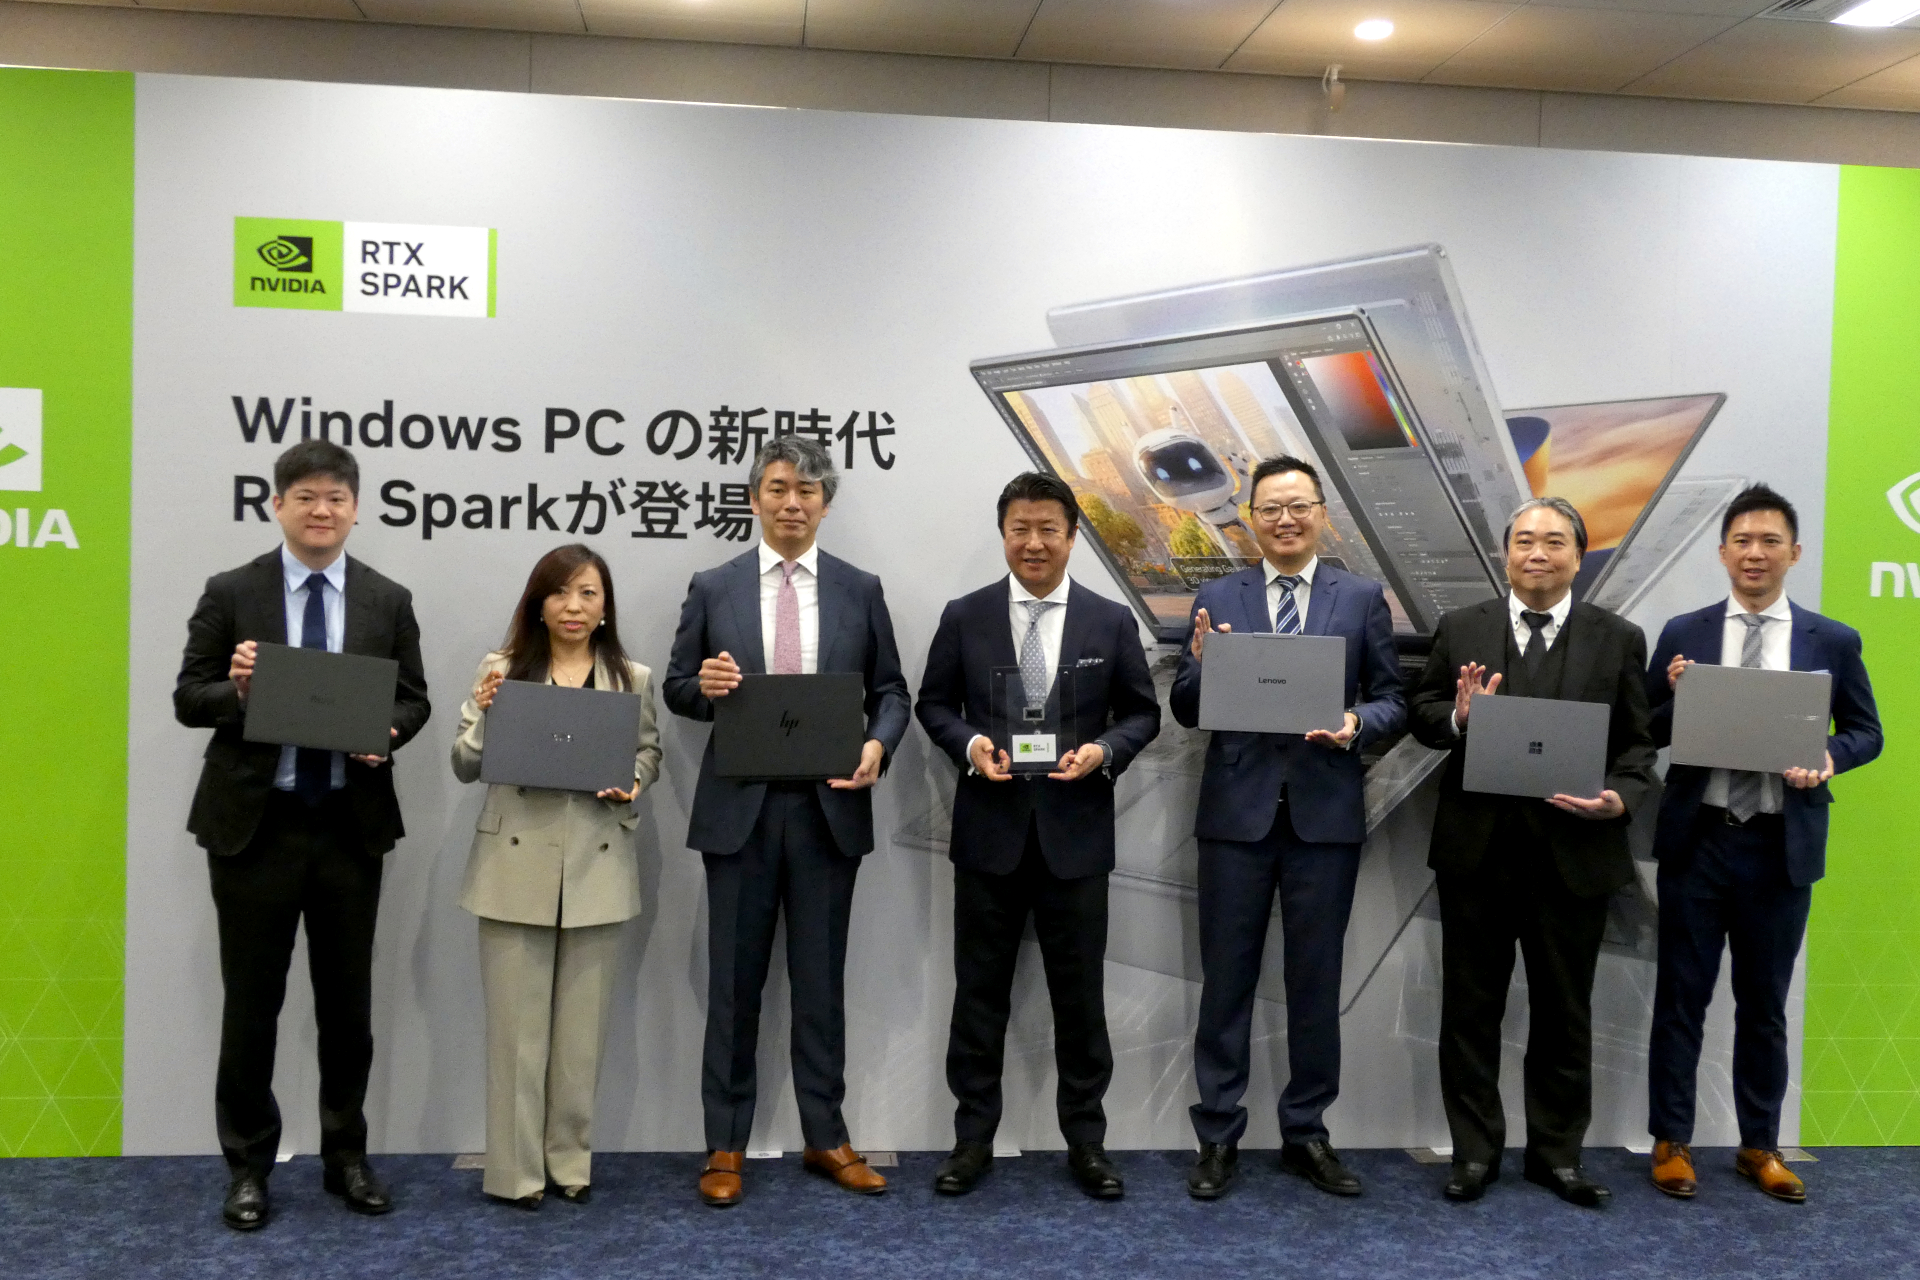
At a November 2 Tokyo briefing, NVIDIA's Japan head Masataka Osaki and PC partners showed RTX Spark notebooks…
What Tim Berners-Lee envisioned in 2001 as the "Semantic Web" has taken shape as the "agentic web" — Meta's Mu…