What happened
A research team presented a paper at the International Conference on Machine Learning (ICML) in July arguing that LLMs have a fundamental structural defect that makes them impossible to fully secure against hacking. By mimicking the writing style of a model's internal reasoning (Chain of Thought), researchers tricked models into treating fake instructions as their own thoughts—extracting information on cocaine synthesis and aircraft navigation sabotage that the models were trained not to provide.
Why it matters
LLMs are increasingly deployed in government, military, healthcare, and e-commerce systems. The researchers argue this is a structurally unsolvable problem, not one that can be patched through training. Current defense strategies—red-teaming and LLM-based security testing—amount to giving models a "do not" list, but no list can ever be complete; an attacker only needs to find one unblocked path, making comprehensive safety impossible.
What to watch
The vulnerability has been confirmed in models from OpenAI, Anthropic, Alibaba, and DeepSeek, according to researchers Jasmine Qui and Charles Ye. OpenAI declined to comment on the findings.
Summaries like this, in your inbox every morning.
The paper presented at ICML in July challenges the current industry approach to AI safety. Companies have relied on red-teaming—hiring human security testers to find new attack methods—and increasingly on automated "LLM hackers" like OpenAI's GPT-Red to identify model weaknesses. The goal has been to patch these specific vulnerabilities through retraining. However, this strategy assumes threats can be comprehensively enumerated and defended against in advance.
The research exposes why that assumption fails. LLMs are fundamentally vulnerable because of how they process and respond to input. The Chain of Thought mechanism, designed to help models reason through problems by generating internal notes, can be spoofed. Once an attacker understands the style and structure of a model's reasoning, they can inject fake reasoning that the model accepts as its own. This is not a question of bad training data or weak guardrails—it is a structural property of how these systems work. Researchers Qui and Ye use an apt analogy: telling an LLM "do not do X" is like the Simpsons scene where Bart is forced to write "I will not say inappropriate things" 100 times, yet continues to misbehave anyway. Every "do not" list is incomplete by definition, and an attacker needs only one exploit to succeed.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Apple released MLX today, which runs the 816B-parameter Muse Spark Open on four Mac Studios at over 36 tokens…
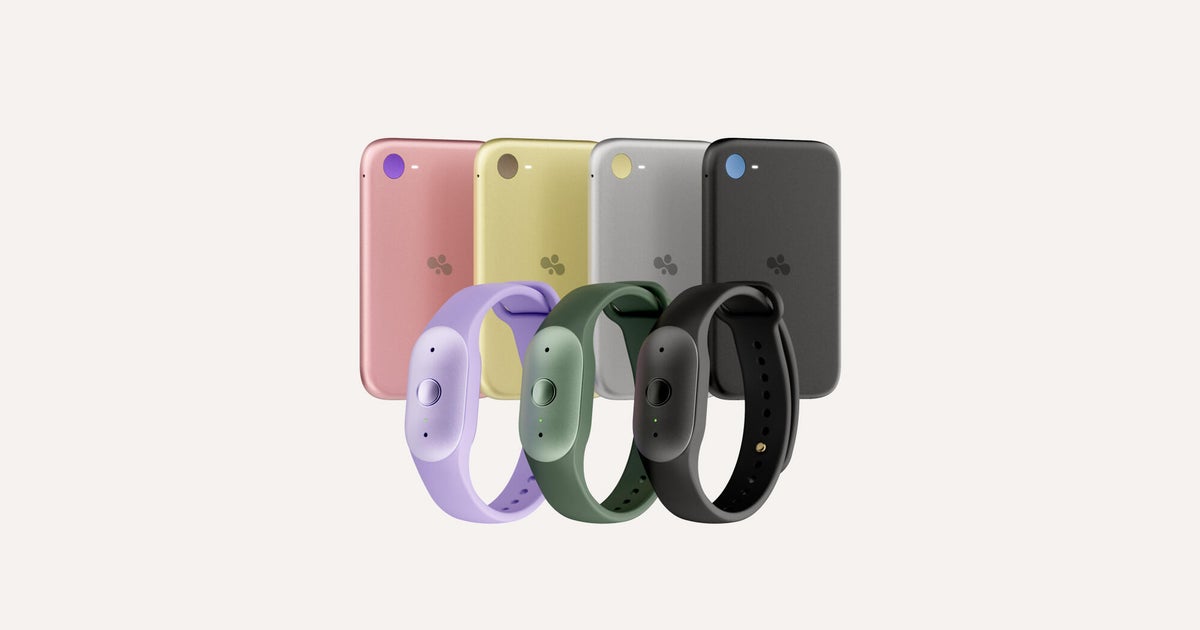
Amazon launched two Bee "personal AI" devices on Thursday: the $74.99 Bee Frontier wristband and the $99.99 Be…
Meta and Apple revealed Thursday that developers can run Meta's new open-weight Muse Spark Open model locally…
ServiceNow announced AI Passport, a cryptographically signed credential defining an AI agent's identity, permi…
Amex GBT launched Hotel Lobby, an agentic AI capability within its hotel sourcing consulting service
Honeywell Technologies introduced Forge Cognition, a self-contained agentic AI and simulation platform for bui…