Google DeepMind's Gemma 4 E4B-IT (4.5 billion effective parameters) handles text, images, and audio natively with a 128K context window, runs on 6–8GB VRAM, though its Codeforces ELO of 940 makes it weaker at pure coding than other models on this list.
OpenAI released gpt-oss-20B with Apache 2.0 license; despite the 20B label it uses a MoE (mixture-of-experts) architecture with only 3.6B active parameters, fits in 16GB memory, and scores Codeforces ELO 2516 with tools—ahead of o3-mini's 2073.
DeepSeek-R1-Distill-Llama-8B distills reasoning patterns from DeepSeek's 671B model into an 8B base, self-verifies and generates chain-of-thought answers, scores 39.6 on LiveCodeBench and 1205 Codeforces rating, runs on 8GB VRAM with MIT license.
Qwen3.6-35B-A3B uses 3B active parameters (35B total on disk) and achieves 73.4 on SWE-bench Verified—testing real GitHub issue resolution in actual codebases—but requires 20GB+ with Q4 quantization, targeting M2 Pro 32GB or 24GB GPUs.
Summaries like this, every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Since around late August, Artex and similar AI penetration frameworks have been used in attacks on companies…
CADMAGEDDON scores 0.991 on BenchCAD's 64³ voxel IoU over a 1000-part subset, above vendor-reported 0.963, 0.9…

CodeRabbit joined OpenAI Daybreak Defense Network, whose members may use the OpenAI-approved GPT-6 Cyber model…
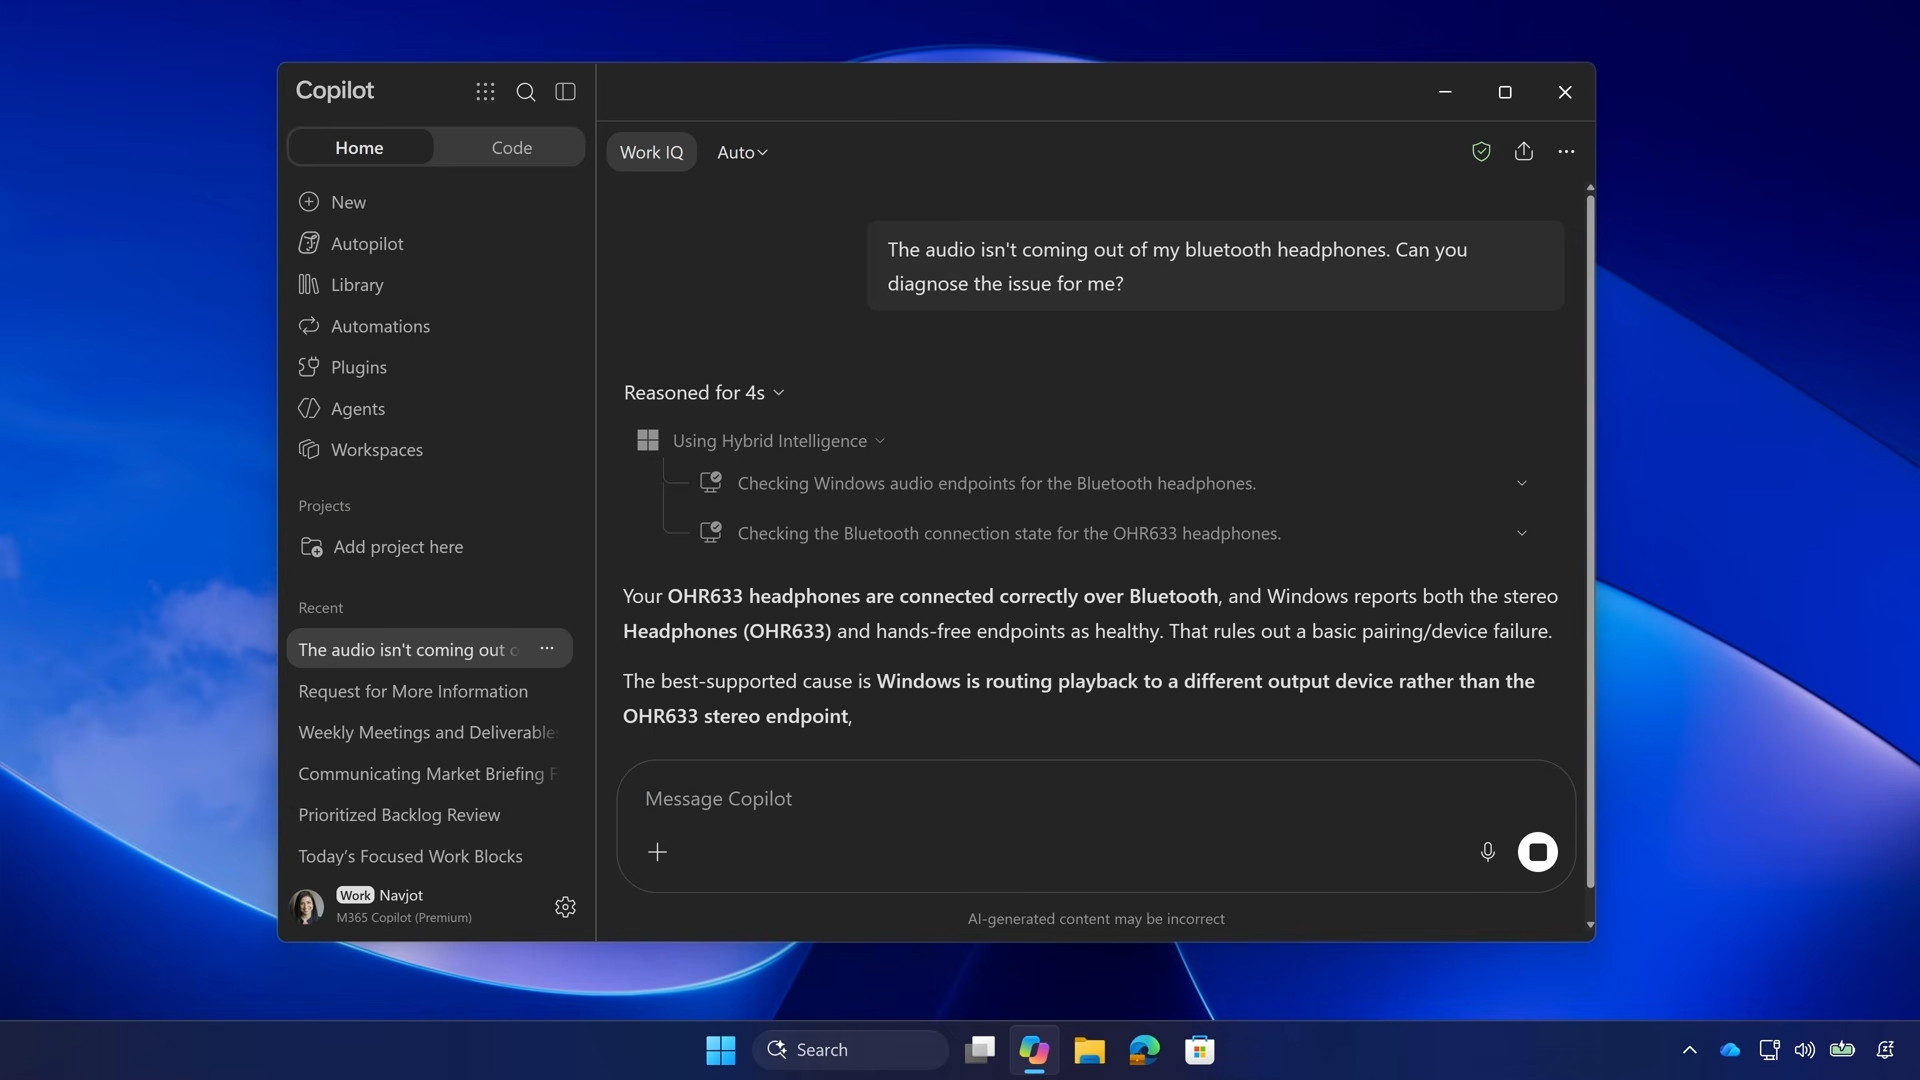
At Microsoft Ignite 2026, CEO Satya Nadella called Copilot "the new OS for work" and said AI chat, agent deleg…
A game client engineer describes using Claude Code (Max plan) so AI drafts, reviews, implements and tests from…
llama.cpp hit version 1.0 with --moe-cache-cpu-share, an option that hands 0–1 share of expert-cache misses to…