What happened
A Zenn explainer breaks down RAG (Retrieval-Augmented Generation) — which retrieves external data before an LLM answers — covering chunking, Embedding, and the difference from vector search alone.
Why it matters
RAG does not eliminate hallucination; even when retrieval succeeds, an LLM may misread or add unsupported details, so developers need access controls and answer verification.
Summaries like this, every morning.
The explainer frames RAG as a practical response to a basic limitation of large language models: they are trained on large datasets but do not know a company's latest manuals, internal rules, or customer information, and they cannot automatically learn information added after training. RAG addresses this by searching external data before the model answers. A concrete example — an internal rule stating expense reports are due on the 25th of each month — shows how relevant text is retrieved and handed to the LLM.
The mechanics divide into preparation and answering. Documents are split into chunks, converted into vectors by an Embedding model, and stored. When a user asks a question, the question is also vectorized, compared against stored vectors, and the closest passages are passed to the LLM along with the question. RAG is not limited to vector search; keyword search and hybrid methods also count, so equating RAG with Embedding-based search understates its scope.
The cautionary section is the most business-relevant. RAG can fail when retrieval finds nothing useful or when the LLM misreads correct material and adds unsupported specifics — an example is an AI answering "by 5 p.m. on the 25th" when the manual only says the 25th. Suggested safeguards include instructing the model to say when information is unavailable, showing source documents, and adding human review for important decisions. Building RAG requires design across data ingestion, search, permission management, evaluation, and operations — not just choosing a model.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
The Japan Foundation, asked by the Ministry of Foreign Affairs and backed by next fiscal year's budget, will d…
SHL's June–July survey found 19.1% of U.S
In a simulated queue of 1,000 requests, the median wait for the first token fell from 452 seconds (7.5 minutes…
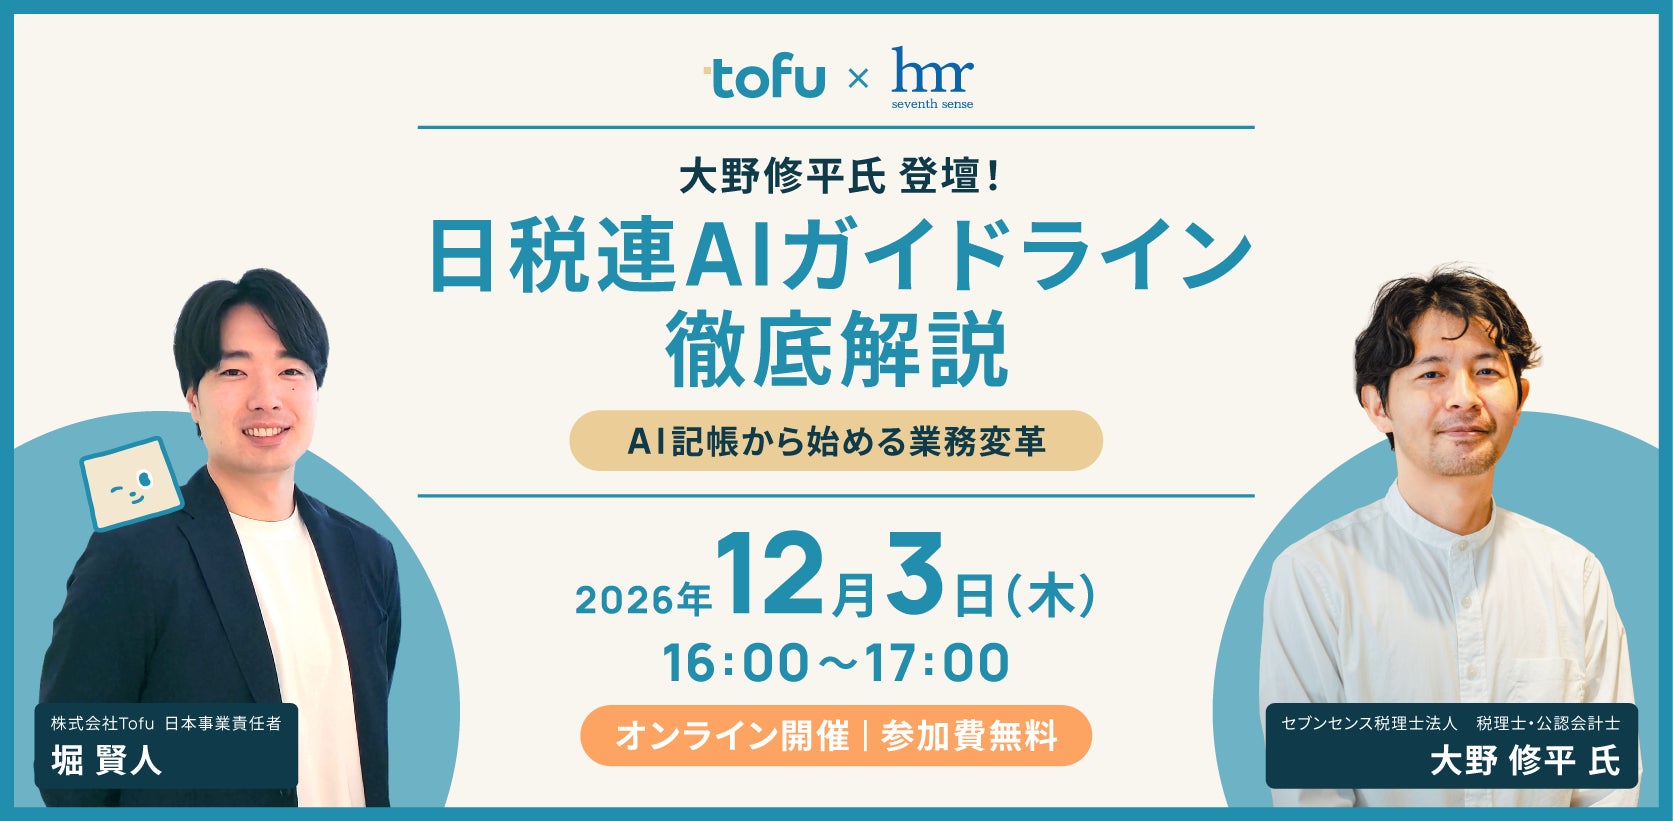
Tofu announced a webinar featuring tax accountant Shuhei Ohno, who will give a full explanation of the Japan F…
ISFnet started offering the Microsoft 365 Copilot 導入フルサポートパッケージ, bundling three trainings and AI agent require…
Shizuku AI技術部 said on 11月5日 it released a prototype letting users talk to AI VTuber Shizuku through an iPhone…