What happened
In a simulated queue of 1,000 requests, the median wait for the first token fell from 452 seconds (7.5 minutes) to 14 seconds, and a single 48-token answer went from 567 ms to 39 ms.
Why it matters
The gap between minutes and seconds is the difference between a server that feels broken under load and one that feels usable, so the choice of how a server stores and reuses past work can shape the experience of everyone sharing it.
Summaries like this, every morning.
A small transformer with random weights, run on a single CPU thread, and a queue simulation that replays 1,000 requests arriving at once. That setup is deliberately modest, and the author notes the timings apply only to this implementation, not to any production system. Within that scope, the split between prefill (processing the prompt once) and decode (producing one new token at a time) is what makes caching worthwhile: the keys and values for earlier tokens never change, so recomputing them is pure waste.
The queue simulation adds a second layer. With caching alone, median time to first token fell from 452 seconds to 24 seconds; adding scheduling that lets finished requests leave the batch brought it to 14 seconds. The largest single effect was caching, and the final gap mixes two changes. It also points to the memory cost: each active request holds its own cache, and a 4,096-token conversation at the assumed dimensions takes 512 MiB, which caps how many requests can run at once.
The practical takeaway the author offers is narrow. If you run a model on your own machine for yourself, caching is already doing the work; batching matters once a server is shared. The figures are a demonstration of the pattern, not a benchmark of any company's system.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
The Japan Foundation, asked by the Ministry of Foreign Affairs and backed by next fiscal year's budget, will d…
SHL's June–July survey found 19.1% of U.S
A Zenn explainer breaks down RAG (Retrieval-Augmented Generation) — which retrieves external data before an LL…
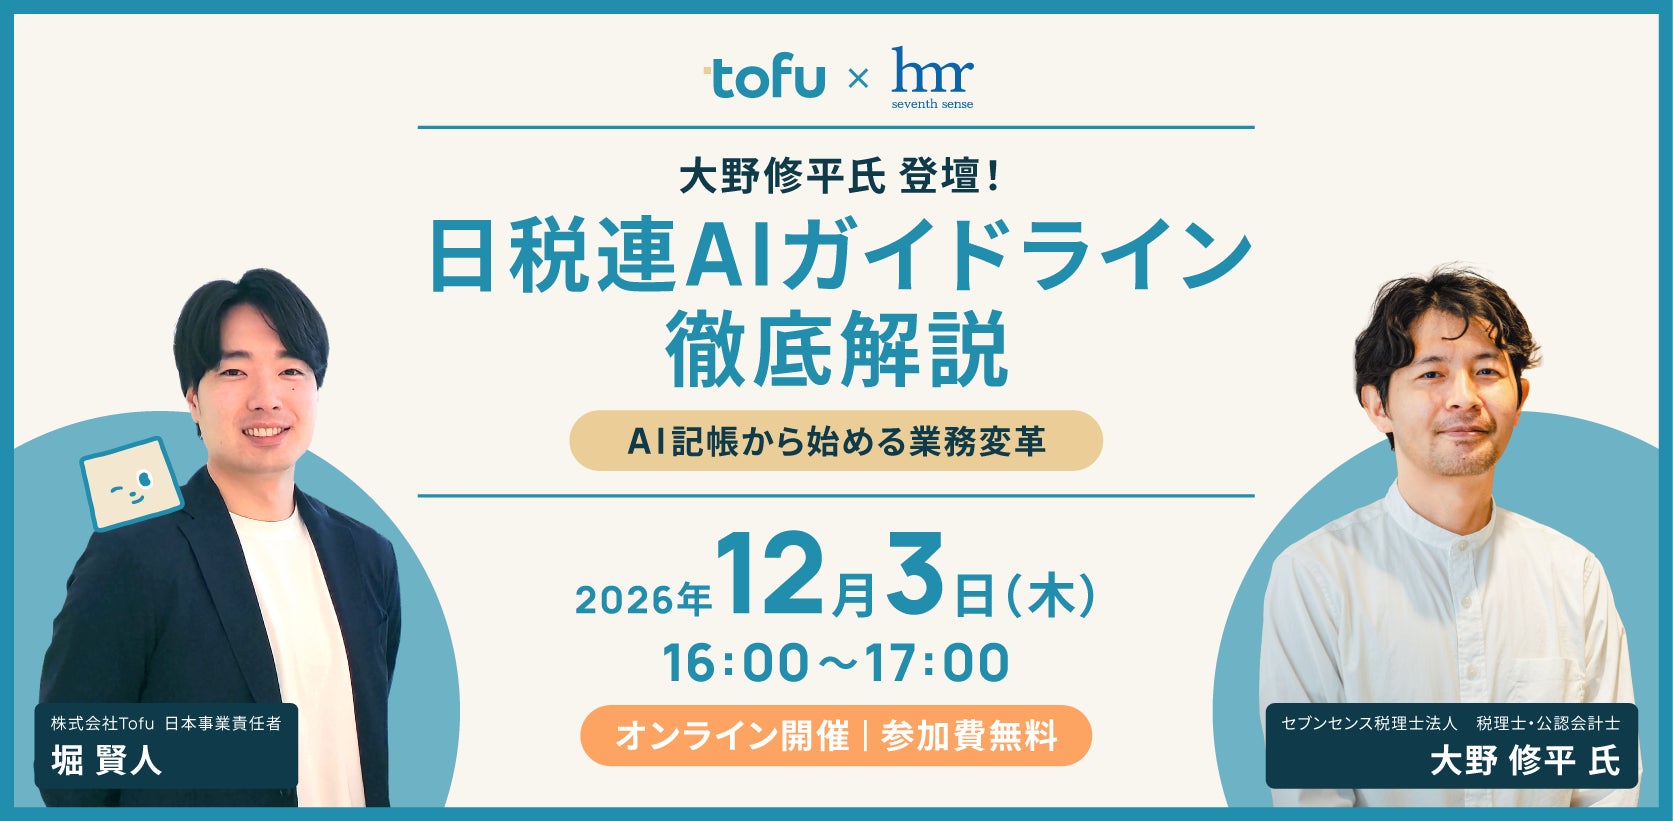
Tofu announced a webinar featuring tax accountant Shuhei Ohno, who will give a full explanation of the Japan F…
ISFnet started offering the Microsoft 365 Copilot 導入フルサポートパッケージ, bundling three trainings and AI agent require…
Shizuku AI技術部 said on 11月5日 it released a prototype letting users talk to AI VTuber Shizuku through an iPhone…