
What happened
Using only NVIDIA's official figures from P100 (2016) to Rubin (2026), the same 10 years divides out to roughly 2,360× on headline numbers, but about 189× when FP16 and dense conditions are aligned.
Why it matters
The two ratios come from the same decade and the same company, so the choice of precision and comparison conditions — not the hardware alone — can change the apparent speedup by roughly an order of magnitude, the author argues.
What to watch
The analysis hinges on condition-matching — reviewers reading NVIDIA's launch figures in October 2026 should check whether precision and dense or sparse assumptions are aligned, and whether bandwidth and capacity kept pace with compute.
WHO IT HITSBusiness readers tracking AI infrastructure budgets and vendor claims will need to ask vendors which precision and dense or sparse conditions back any 'X× faster' figure, since the same 10-year P100-to-Rubin span yields roughly 2,360× or about 189× depending on those choices.
Summaries like this, in your inbox every morning.
The article's method is deliberately narrow: it uses only NVIDIA's official figures and re-normalizes them onto a single ruler, FP16 and dense. On that ruler, the 2016 P100 moves from 29 FLOPs/byte to 139 at V100 (2017), 153 at A100 (2020), and 295 at H100 (2022). That rise reflects Tensor Cores and lower-precision arithmetic, which the author says should be separated from gains in the silicon itself. In the 2024-to-2026 stretch, the picture flips: bandwidth catches up, and FLOPs/byte falls from 295 at H100 to 281 at B200 and 182 at Rubin.
The author also flags limits of the comparison. Rubin's memory bandwidth is listed as 22 TB/s in NVIDIA's developer blog and DGX Rubin NVL8 page, but a Vera Rubin NVL72 specification page shows 19.2 TB/s; the article adopts 22 TB/s and notes that the 19.2 TB/s figure would push Rubin's FP16 FLOPs/byte to about 208, without changing the direction of the trend. Power figures for Rubin were not found in NVIDIA's official materials, and the B200 1,000W value comes from a Lenovo document. The article's comparison to human history is presented as analogy only, not a causal claim.
Read this as a framework for reading launch numbers, not a verdict on any single chip. The stakes land on anyone sizing AI infrastructure or evaluating vendor claims, since a headline 'X×' figure can move by roughly an order of magnitude depending on precision and density assumptions, and capacity and power may shift where the next constraint sits.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Anthropic released Claude Haiku 5.5, a small model for repetitive work, with list prices of 10 cents per milli…
TIMEWELL said on October 1, 2026 it was chosen as a Shinshu AI GEARS subsidy recipient, working with Orion Kik…
Mecka AI announced a $60 million Series B led by Sequoia, with Nvidia, Microsoft's venture fund M12 and others…
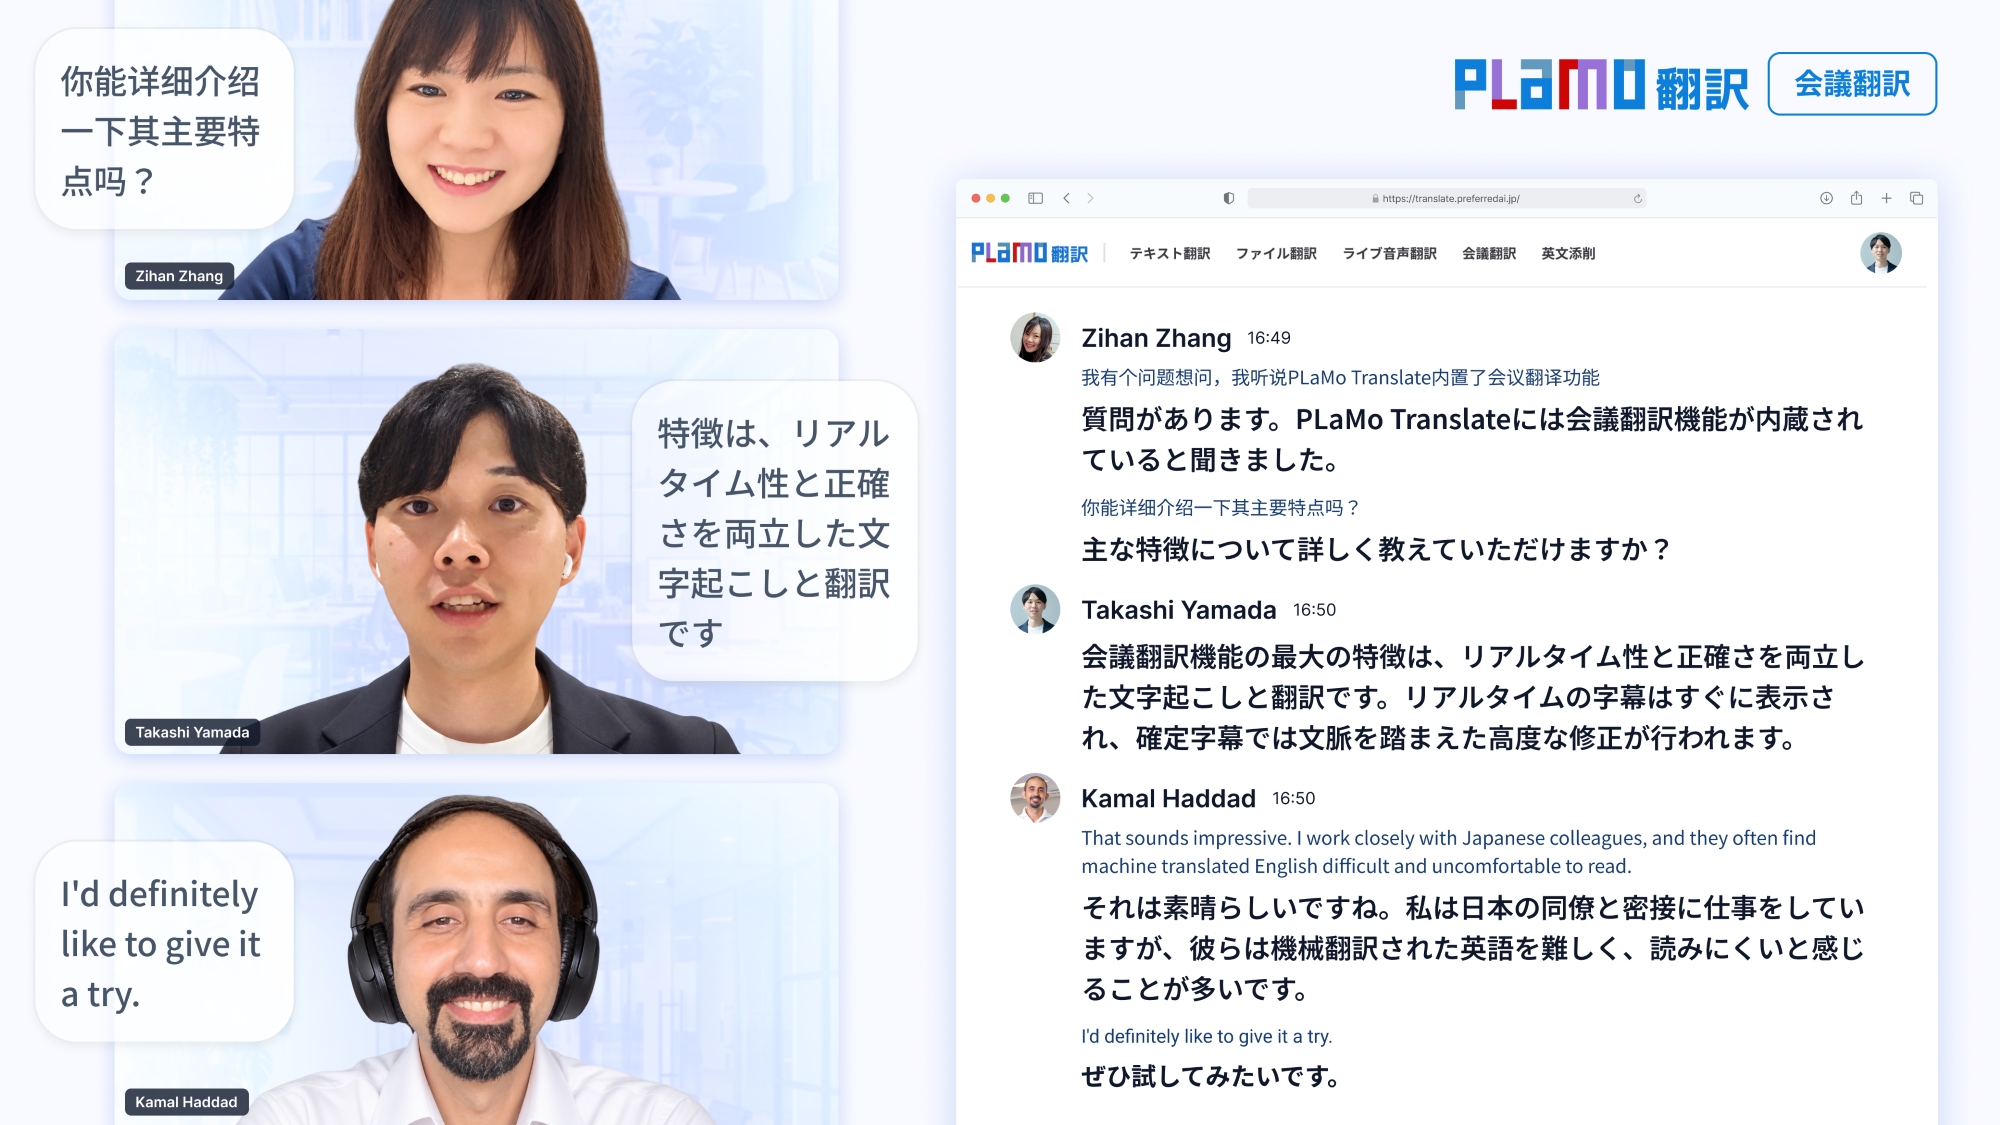
Preferred Networks began offering a major update to its Japan-focused AI translation service PLaMo翻訳, claiming…
Analysts estimate China's best models are now just four months behind OpenAI and Anthropic, versus seven month…
At Sequoia AI Ascent, DeepMind CEO Demis Hassabis said AGI arrives in 2030 and described a two-step mission: b…

