What happened
Baidu released ERNIE-5.5-Flash-Base, an open foundation model with 280 billion parameters (14 billion active per input), pre-trained on 33.5 trillion tokens and available on Hugging Face in FP8 and BF16.
Why it matters
Because the model ships without fine-tuning or post-training, developers must decide themselves where to take it, and Baidu says a post-trained version is supposed to follow.
Summaries like this, every morning.
Baidu's ERNIE-5.5-Flash-Base arrives as a deliberately unfinished product: the company released the base weights without fine-tuning or post-training, so the model's usefulness depends on what developers build on top of it. That choice shifts effort to the open-source community, while Baidu says a post-trained version is supposed to follow.
The architecture details explain the design. ERNIE 5.5 uses a mixture-of-experts setup with 280 billion parameters, only 14 billion of which are active per input, and it was pre-trained on 33.5 trillion tokens with a training context of up to 128,000 tokens. Baidu says the model is designed to support a context of up to one million tokens during fine-tuning and inference, a range that matters for long-document and code tasks.
Baidu says that in benchmarks for reasoning, code, and long-context tasks the model competes with similarly sized open foundation models. The weights are on Hugging Face in FP8 and BF16, giving developers a concrete starting point to adapt.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Hitachi Energy is expanding its partnership with Celonis, the process-intelligence leader, to scale AI use acr…
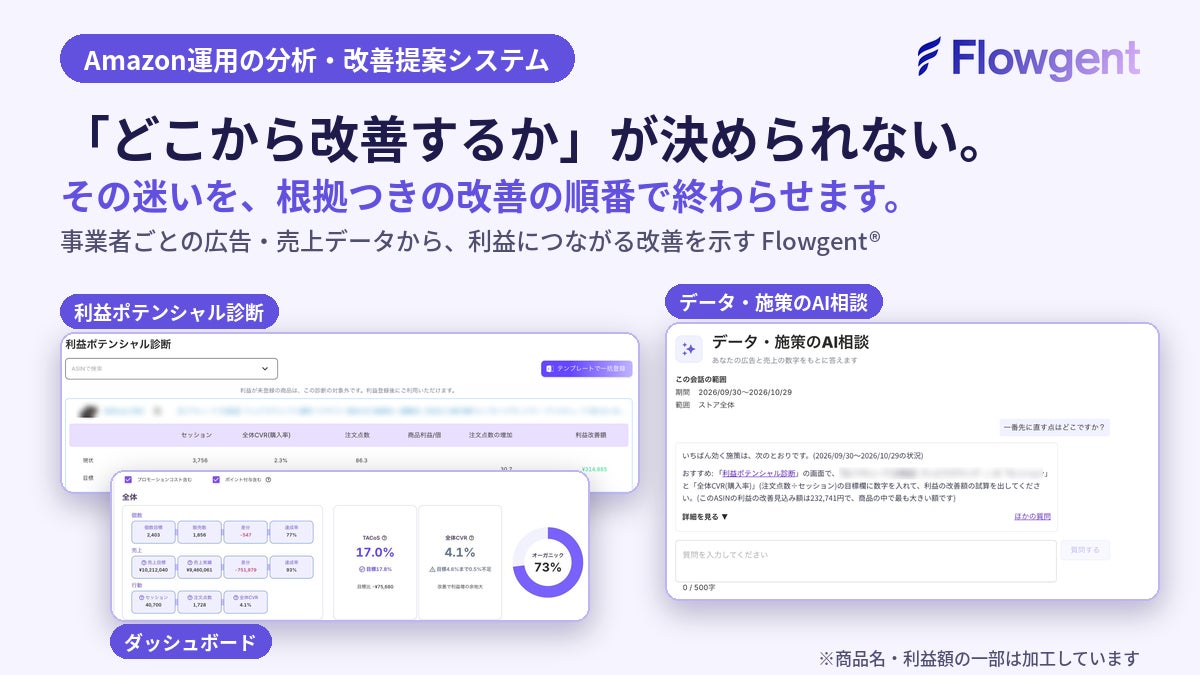
Spesia added an "AI consultation on data and measures" chat to Flowgent, its Amazon operations analysis system
In Branding Works' October 2026 survey of ChatGPT and Gemini answers, 辻・本郷税理士法人 appeared in 50% of responses…

Fixstars said on Nov 5 it began offering open-weight models on GPU servers in Japan, working with Kokusai Chot…
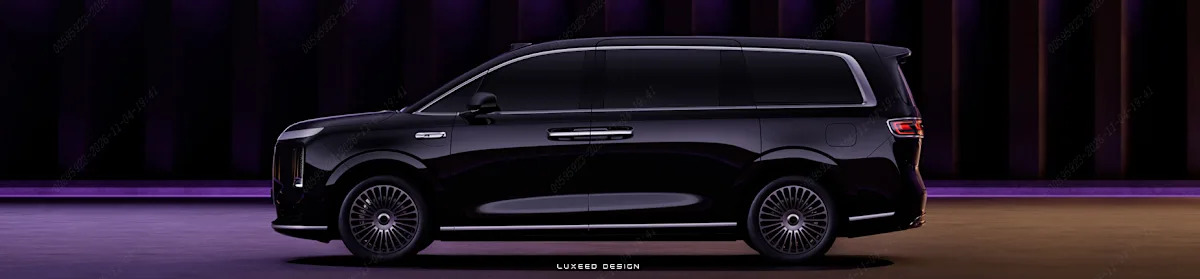
At its Global Brand Launch on October 21, LUXEED introduced the LLounge MPV and Stormax SUV, both with AI smar…
Box announced Box for Industries, an industry-specific solution set, and began offering Box for Banking, Box f…