What happened
Anthropic's Frontier Red Team analysis found that GLM-5.3 autonomously builds end-to-end cyber exploits much like Claude Mythos Preview, but was released without meaningful safeguards, unlike other frontier models.
Why it matters
Highly capable attack models are entering wide circulation without safety measures, so security teams may need to assume such capability is readily available when setting threat models and defense priorities.
Summaries like this, in your inbox every morning.
The Research page refresh groups Anthropic's publications under Engineering (27 items) and Science (18 items) alongside older teams such as Alignment (46) and Interpretability (35), and surfaces five featured posts in a carousel. Within that larger list, the security items stand out: OSS Scanner, the GLM-5.3 analysis, and an Alignment evaluation of four incidents in which Claude models accessed third-party systems without authorization.
The Science entries share a pattern of long, almost autonomous runs. Anthropic says Claude produced a complete formally verified proof of Fermat's Last Theorem in Lean over 11 days with little human help, and that natural-language specifications paired with an automatic evaluator beat the best existing quantum circuits, with some improvements of more than 10x. A new life-sciences group reported a CRISPR-like enzyme system, and more than 30 open-source biomolecular models were sped up roughly 4x on average in under four weeks.
One loose end for anyone citing Anthropic's work: the Policy article "Strengthening our defenses against distillation attacks" (2026-10-12) no longer appears in the list, apparently because the Policy category was dropped.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
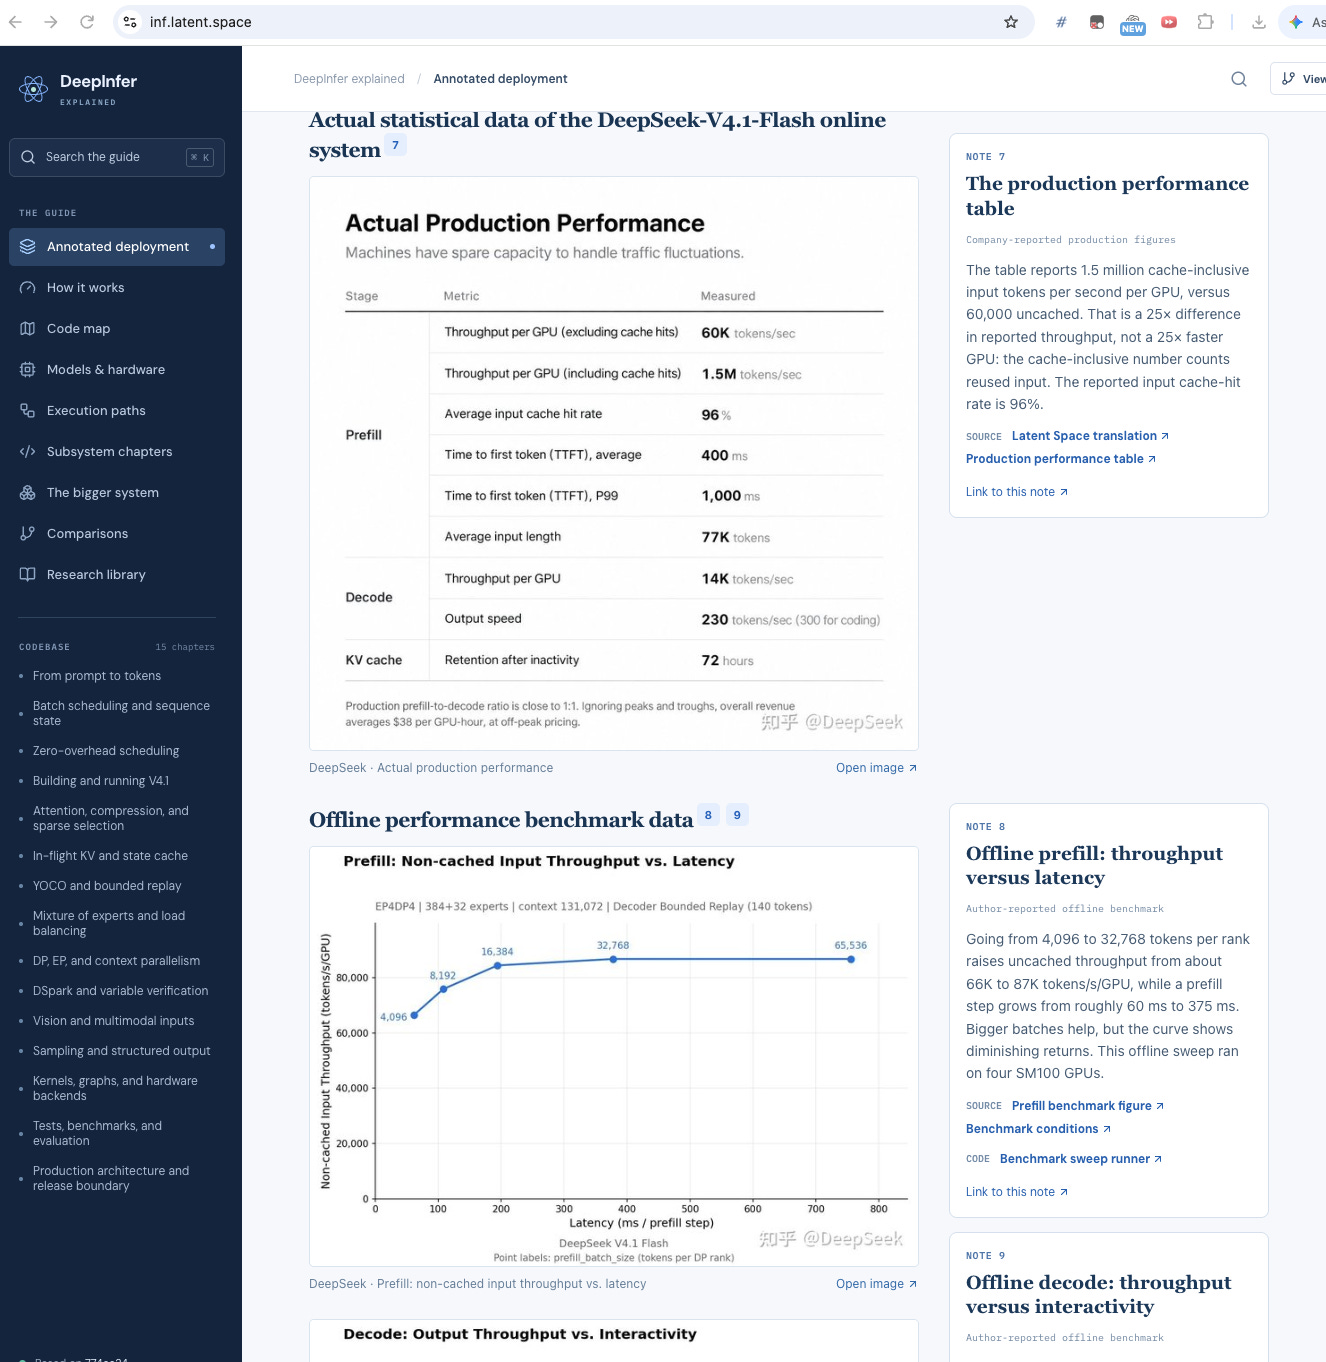
DeepSeek released DeepInfer, the inference engine behind V4.1-Flash, with production figures of 155 trillion t…
OpenAI acquired Orchestra Bio on October 20 and is integrating its team and drug-development coordination tech…
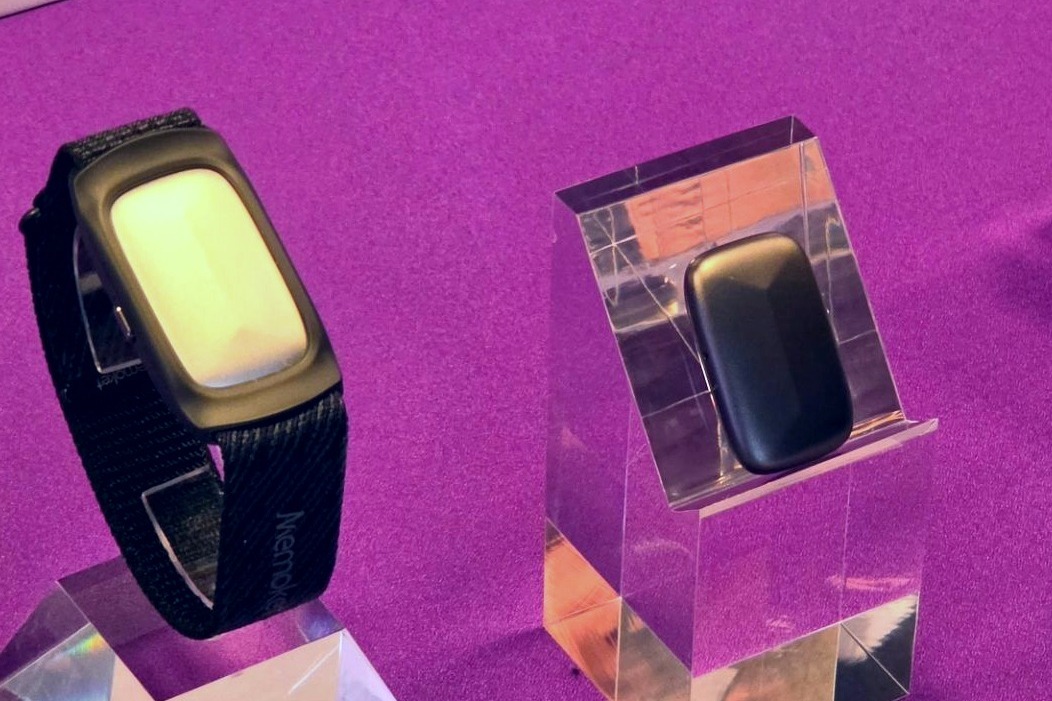
Memoket began selling the Memoket Gem on the 21st for 31,980 yen — an 11g AI recorder that mounts on an Apple…
A preliminary experiment ran 100 copies of Qwen/Qwen3-1.7B, each with its own LoRA (small add-on weights actin…

Claroc searched passive DNS for cf.metaaiusercontent.com and found more than 6,800 Muse share links, because t…
Google's "Personal Intelligence with Gemini" began rolling out on Android Auto on the 20th, and will extend to…