OpenAI began offering a ChatGPT feature that accepts uploaded audio files and can transcribe them, summarize t…
NECネクサソリューションズ started offering "対話型音声AIエージェント Powered by DEN.Ai" on 2026年10月6日
Automation Anywhere announced Wednesday an agreement to acquire Boost.ai, a conversational voice AI company, f…
Willow Care Inc., maker of the AI dictation app Willow Voice, picked CoreWeave Inc
Abu Dhabi's state-run Technology Innovation Institute released Falcon-Emirati models trained on the Emirati Ar…
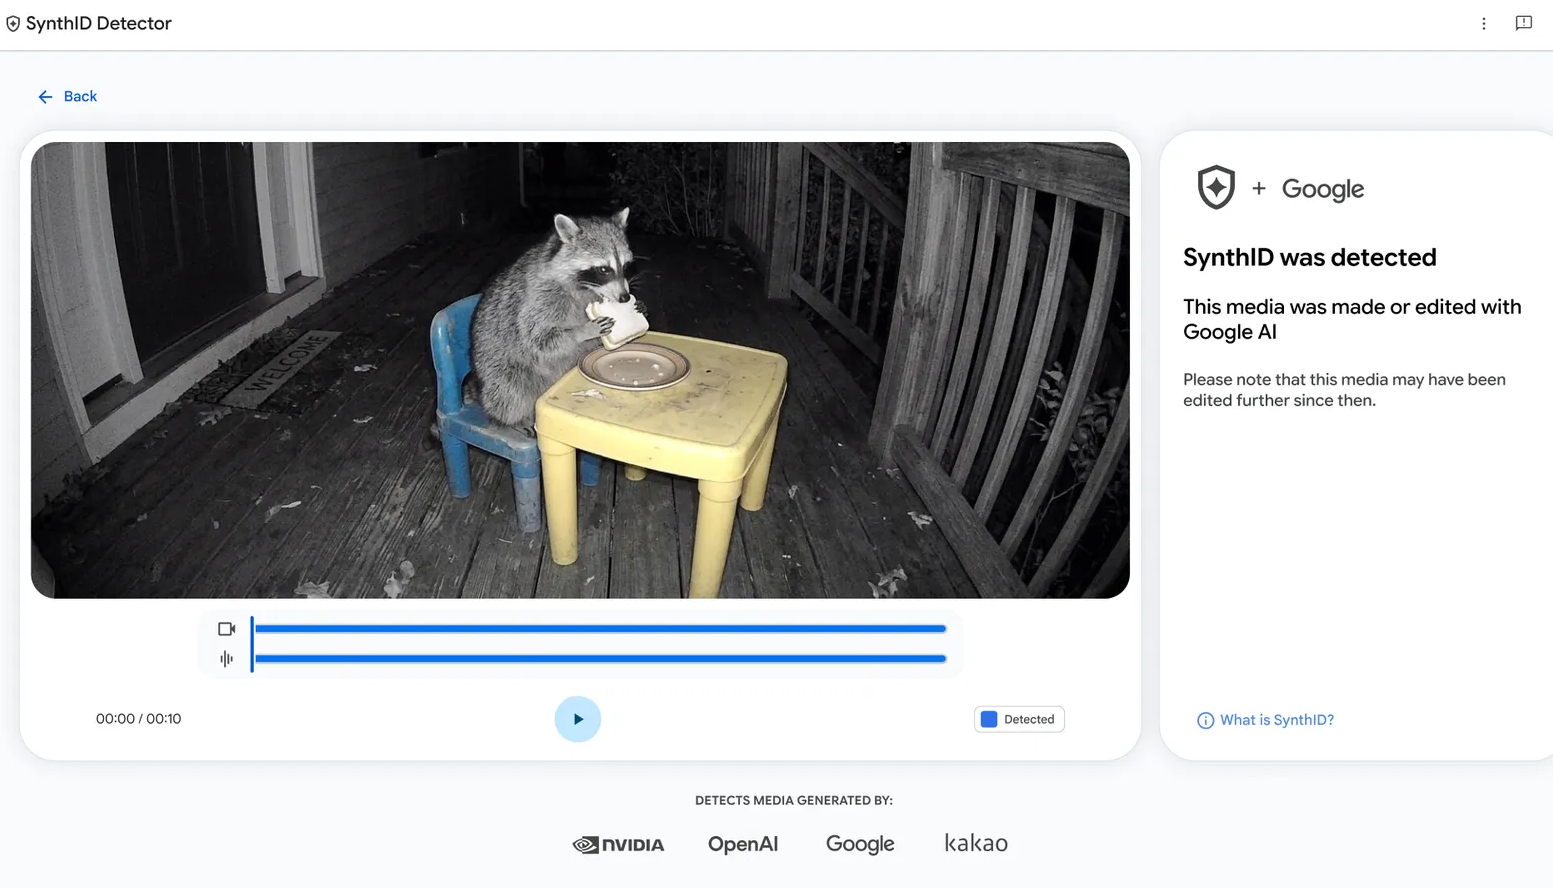
Google LLC launched the web-based SynthID Detector, which flags AI-made images, video and audio from Google, O…
The FCC is considering allowing more political robocalls before the midterms, including those created with AI
Google launched Playground, a browser-based AI platform that lets adults in the US create games using only tex…
Google's Gemini 3.5 Transcribe, launched in August 2026, is a transcription-only model that separates speakers…

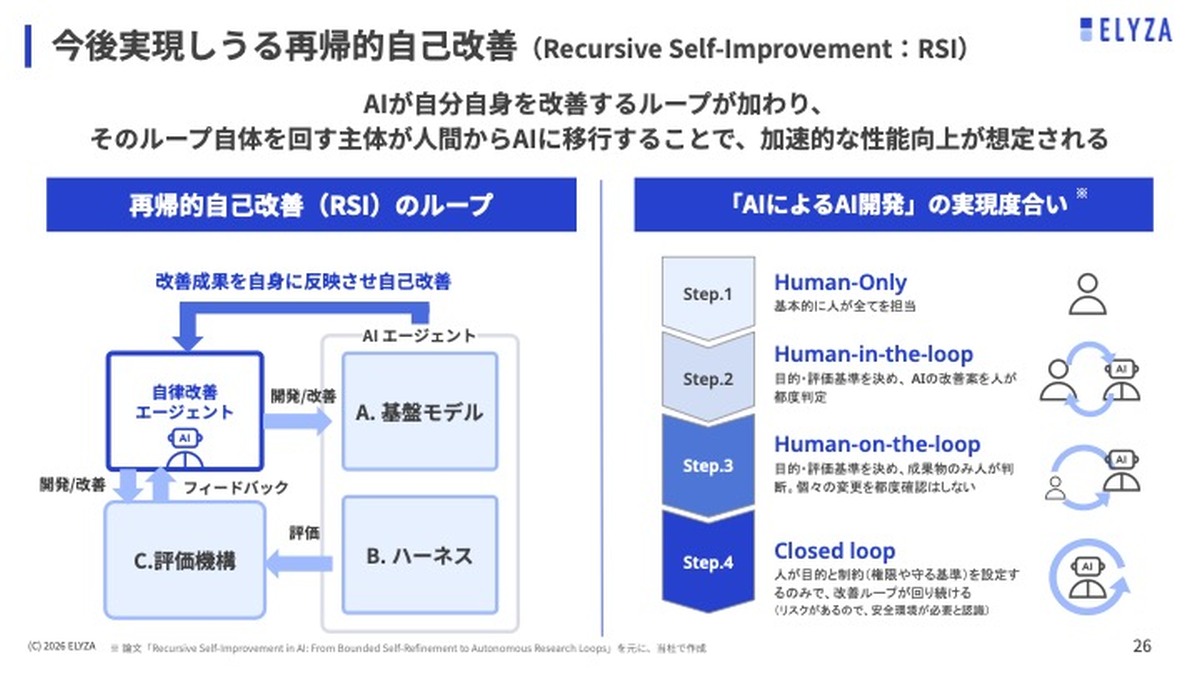
ELYZA announced ELYZA RSI Research at a Tokyo press conference on October 2, 2026, and also showed ELYZA Voice…
After GPT-Live (gpt-live-1) GA'd on September 10, 2026, the Kikuren developer swapped out gpt-realtime-2.1, an…
The developer added Nemotron 3.5 Streaming ASR 0.6B 560ms INT8 to the Koehaku voice runtime, and a 100-turn te…
Sean Parker and Prem Akkaraju are rebuilding Stability AI as a music toolmaker; in late August it announced $7…
Microsoft and LG Electronics unveiled a Speech-to-Speech AI agent at the Microsoft Industry Summit in Seoul, e…
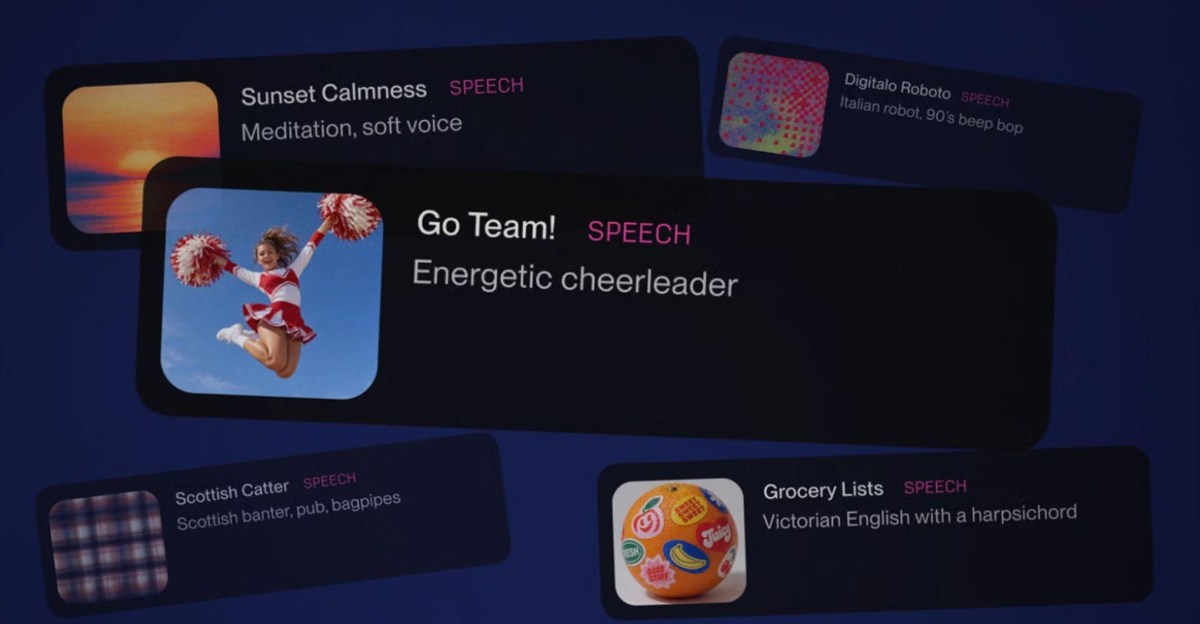
Suno, the AI music generator, launched a feature called Speech that turns typed text into spoken words with ma…
An explainer describes AI song covers as original melody, lyrics and backing kept intact, with only the vocals…

In a controlled English/French HuBERT setting, two interventions — an auxiliary language classifier and per-la…
Microsoft AI launched MAI-Transcribe-2-Streaming, which Microsoft says ranks first for accuracy on Artificial…
Suno launched Speech in public beta across its web and mobile platforms, letting users generate voiceovers and…
Microsoft launched MAI-Transcribe-2-Streaming, its first streaming transcription model, priced at 54 cents per…
Microsoft AI said it released MAI-Transcribe-2-Streaming, which returns provisional results in just over 100 m…
Microsoft released MAI-Transcribe-2-Streaming on October 1, 2026
Starkey announced Omega AI+, succeeding last year's Omega AI
Airbnb CEO Brian Chesky said he has used Airbnb on the agents Muse and Instinct and "it doesn't work very well…
Creatune's Alex wrote that the current AI cover screen offers two paths — a Voice Cover, which keeps the song'…
A Reddit analysis of audio.cpp mapped shared building blocks across 100+ audio models
Aditya Shinde is recruiting beta users for MeetTwins, an AI assistant built with Sarvam's AI models and a Siml…
ElevenLabs let employees sell a portion of their vested shares at a $22 billion valuation, double the $11 bill…
Hugging Face launched the Open TTS Leaderboard, ranking models by word error rate (WER/CER), H200 GPU speed me…
GENIEE's tech blog team named its three most-read posts from September 2025 to September 2026, led by an SRE t…
Running Hugging Face's speech-to-speech all-local on an RTX PRO 6000 Blackwell, reply audio began on average 2…
The Tokyo District Court dismissed Kenjiro Tsuda's demand that TikTok remove AI voice-clone videos, citing pri…
DeepL opened general availability of real-time speech-to-speech translation in DeepL Voice, supported by a new…
ElevenLabs released Eleven v4, which handles up to 10,000 characters per request and supports more than 90 lan…
AHS launched two voice databases for Synthesizer V 2 on September 29 — the female Synthesizer V 2 AI Nanami an…
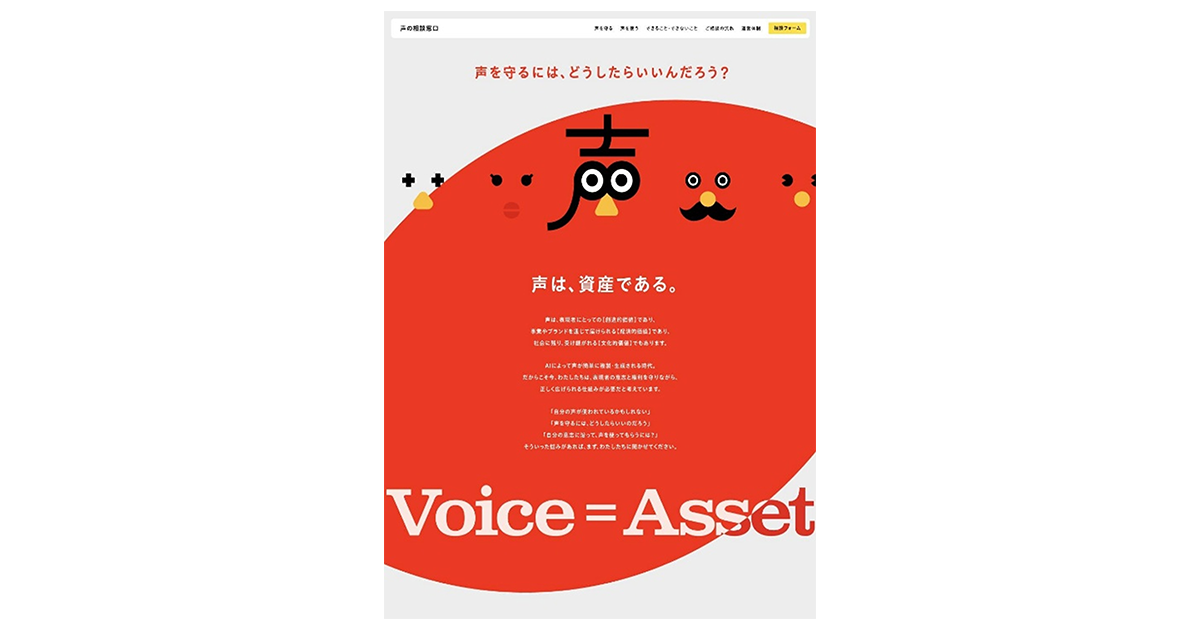
NTT West's VOICENCE company said it will open a free "Voice Consultation Desk" on September 28, 2026
Turn today's AI news into today's work.
The day's essentials from 100+ sources, delivered to Email, LINE, or Slack. Free to start.
60,000+ monthly readersAWS published Part 1 of a tutorial that deploys Qwen3-TTS on Amazon SageMaker AI using the vLLM-Omni Deep Lear…
Modulate raised $25 million, led by Future Ventures with returning investors Hyperplane and Lakestar, bringing…
ElevenLabs launched Eleven v4 and low-latency Eleven v4 Turbo, ranked #1 by Artificial Analysis and preferred…
Tarini Padmanabhuni founded DetectifAI after a deepfake of her grandfather's brother's voice tricked him into…
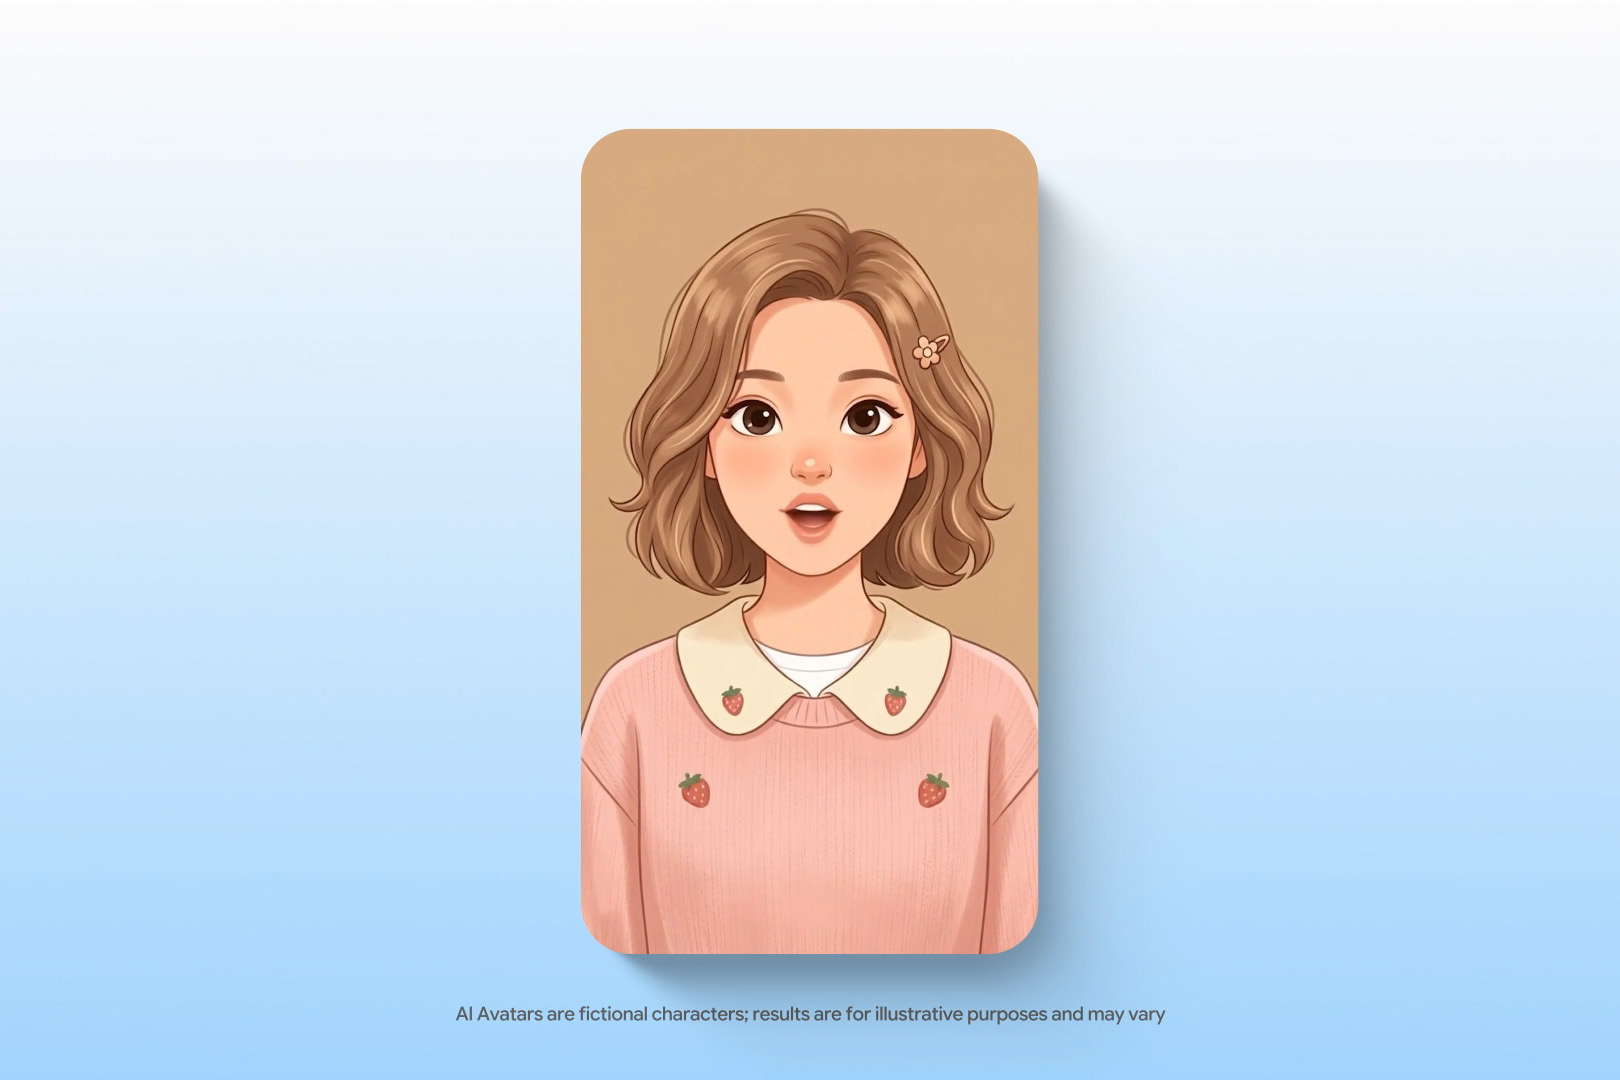
Google said its Gemini 3.8 Live voice model now has a Live Avatar feature, and that Live Avatar-equipped Gemin…
OpenAI said on 9月24日 that ChatGPT Voice on mobile and web can now handle work using connected apps and tools…
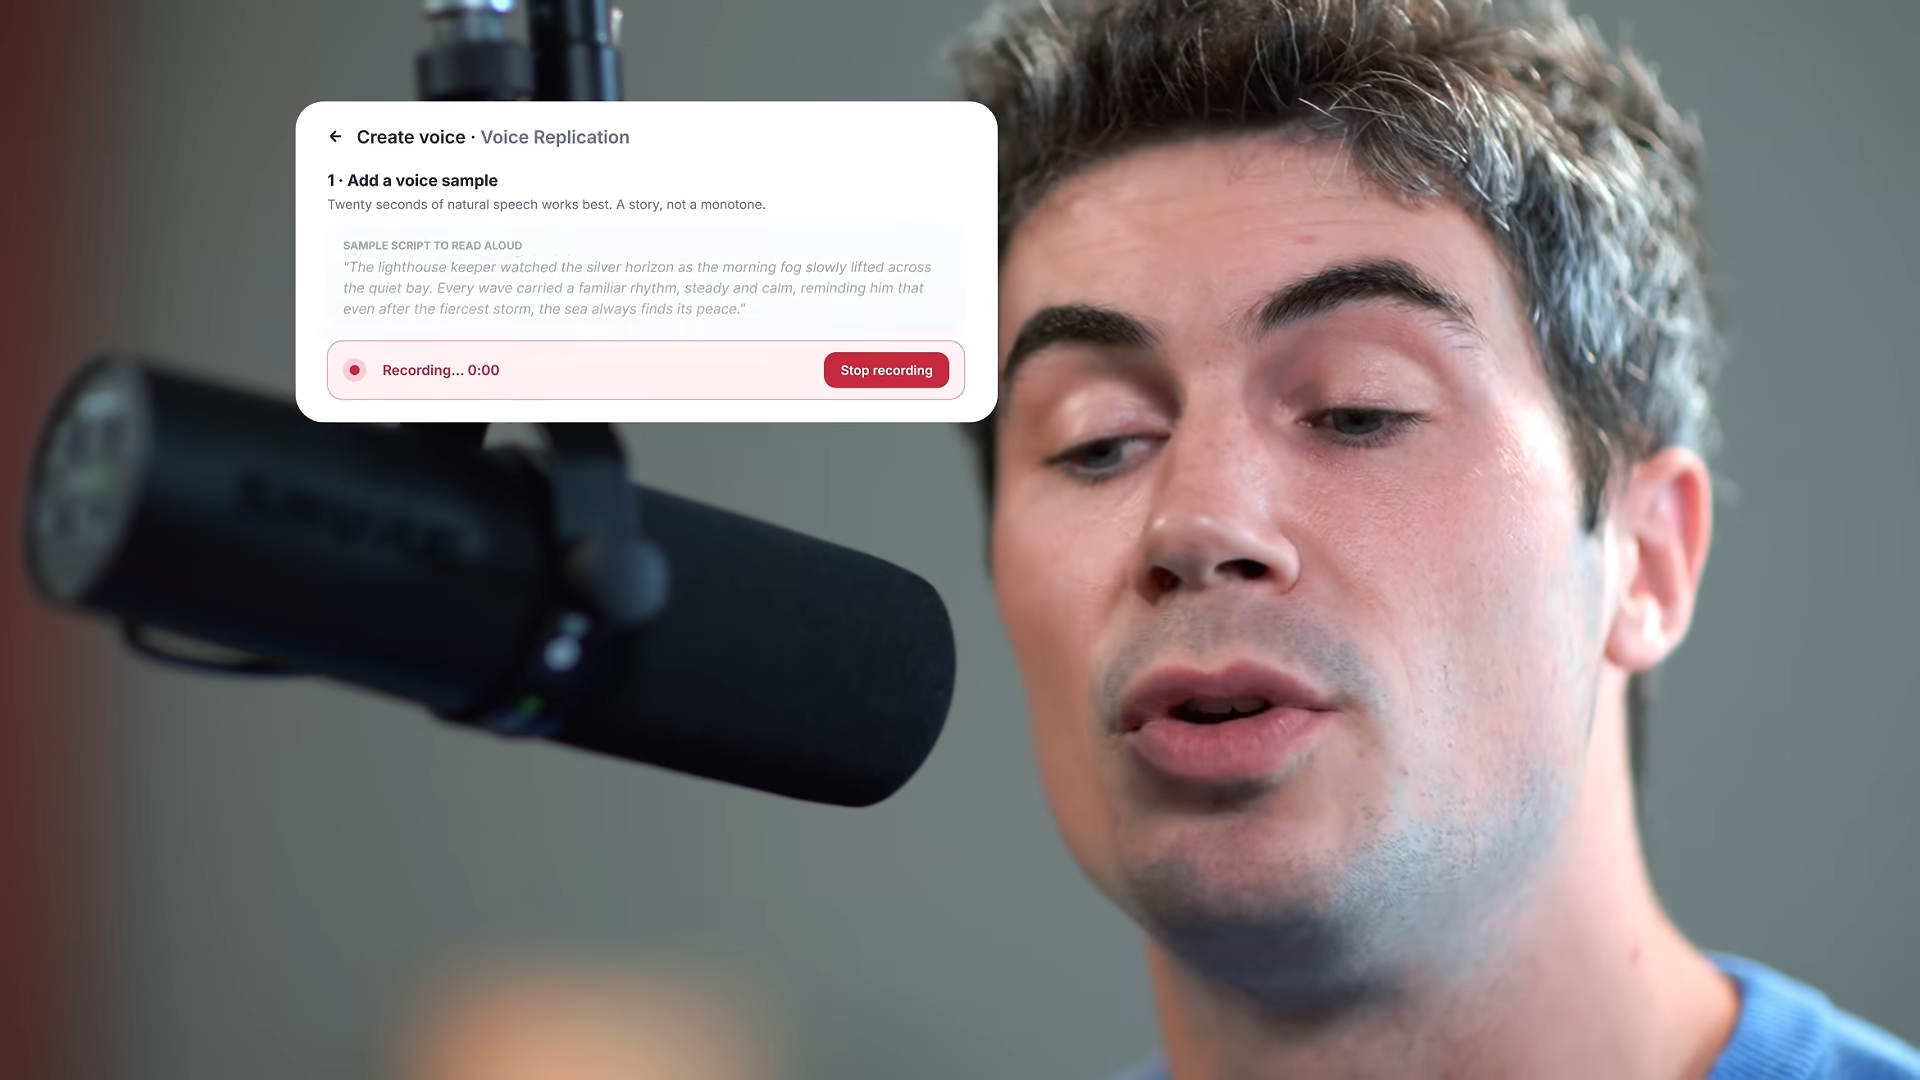
Google announced Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, text-to-speech models that recreate a voi…
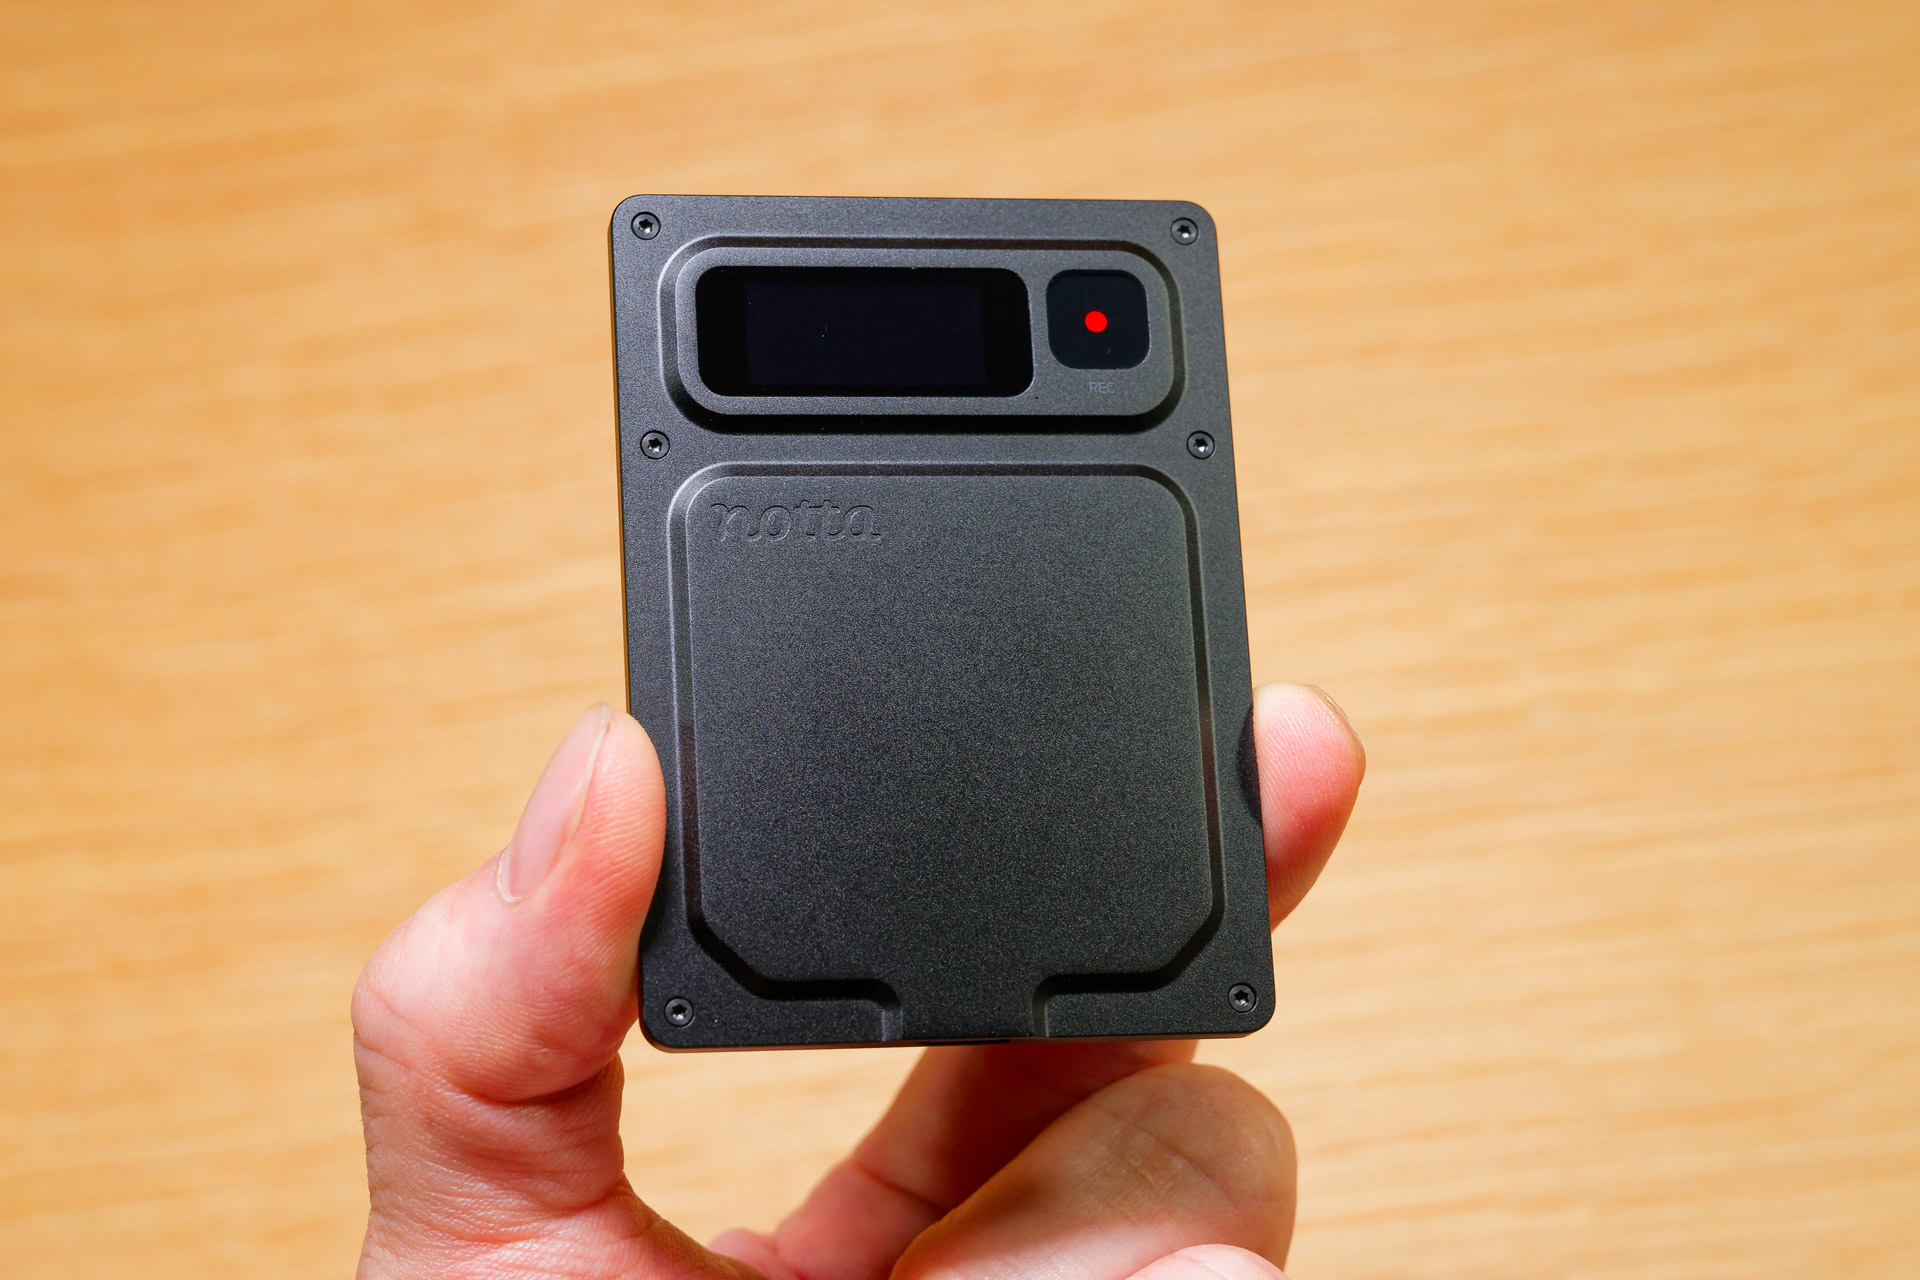
Notta's "Notta Memo Pro" is an AI voice recorder (a device that records and automatically converts speech to t…
Google announced voice-generation models Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, plus Gemini 3.8 L…
Nvidia released Nemotron 3 Diarization, a free AI model with about 100 million parameters that identifies up t…
Voice actor Kenjiro Tsuda sued TikTok over videos he says use an AI clone of his "lustrous" baritone
Synthesia, a digital avatar startup valued at $4 billion, made an interactive avatar for a TechCrunch reporter…
McDonald's unveiled "Archy," an English- and Spanish-speaking AI drive-thru system it says exceeds 90% accurac…
AWS detailed deploying Qwen3-TTS-12Hz-1.7B-Base from Alibaba Cloud's Qwen team via Amazon SageMaker JumpStart…
Sony and Universal Music Group filed yet another suit against Suno, saying its v6 model is trained on user out…
Google is testing "Call for Me," letting Gemini call businesses for US Pixel 11 owners with a paid Gemini subs…
AWS released the WhisperX Deep Learning Container, a GPU-ready image bundling Whisper, wav2vec2 forced alignme…
Apple researchers studied how to compress the tokenizer behind System-wide Dictation, the on-device encoder th…
Google launched Gemini 3.8 Flash TTS and Flash-Lite TTS on its cloud platform, with Flash TTS supporting 130 l…
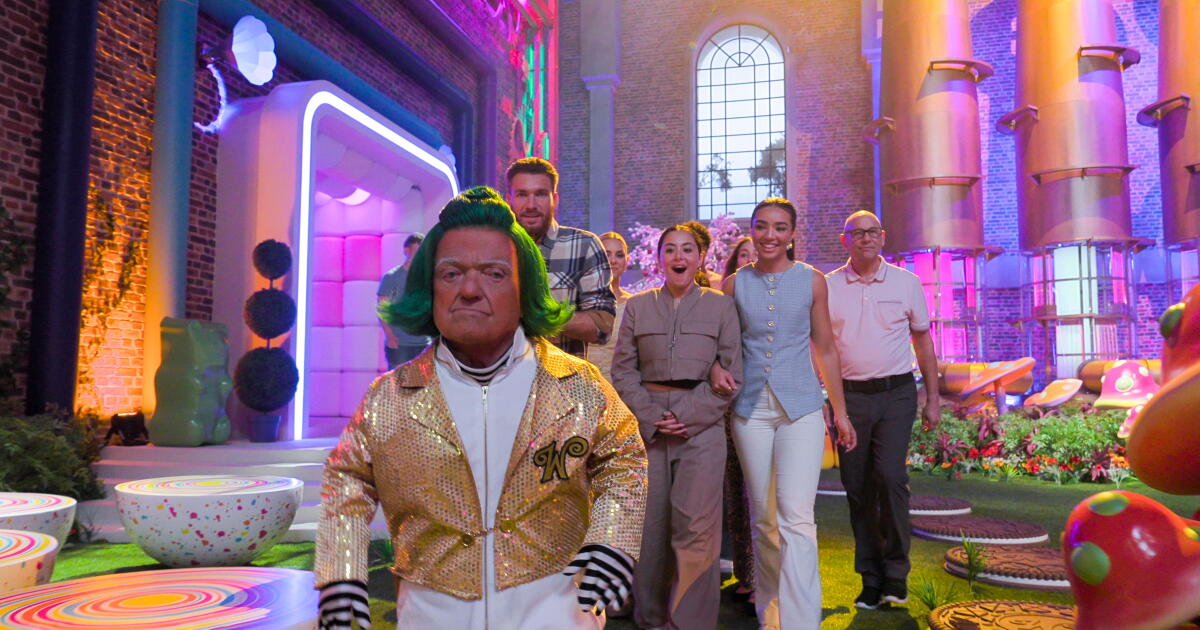
Netflix premieres "Wonka's the Golden Ticket" on Wednesday, a reality competition based on the 1971 film, usin…
Google released gemini-3.8-flash-tts and gemini-3.8-flash-lite-tts, offering over 2,000 voices and custom voic…
Google is rolling out Gemini 3.8 Flash TTS and Flash-Lite TTS through the Gemini API and Google AI Studio, sup…
ChatGPT Voice now runs on OpenAI's new GPT-6 Astra, Sol, and Luna models and can access plugins like email, ca…
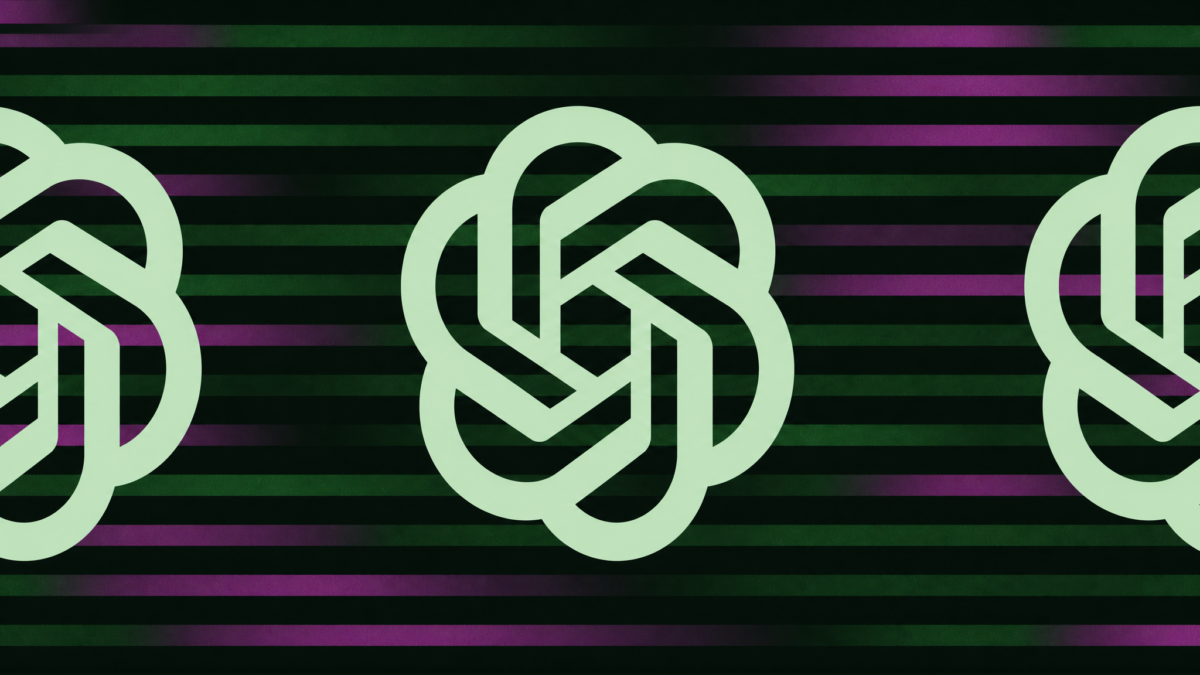
At its Made On YouTube event, YouTube announced Ask Music, a conversational tool built into the YouTube Music…
NVIDIA released Nemotron 3 Diarization, an open-weight, 100M-parameter model that ranks #1 on VoiceArena's Dia…
Alibaba's Qwen released Qwen-Audio-3.1, five models for speech recognition, text-to-speech and real-time inter…
A weekly roundup covers five new generative AI technologies, including YuE2, a music generator compared with S…
Tencent's Hunyuan Speech team and university researchers introduced Gander, which splits real-time conversatio…
McDonald's unveiled ArchIQ and its Archy voice assistant in limited testing at a handful of US drive-thrus, af…
Treble raised $18 million in a Series A extension led by Paladin Capital Group, with KOMPAS VC, Frumtak Ventur…
Spotify and industry groups are moving to label, restrict or ban AI-generated tracks, after the New York Times…
Google announced Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking on September 15 and began offering them…
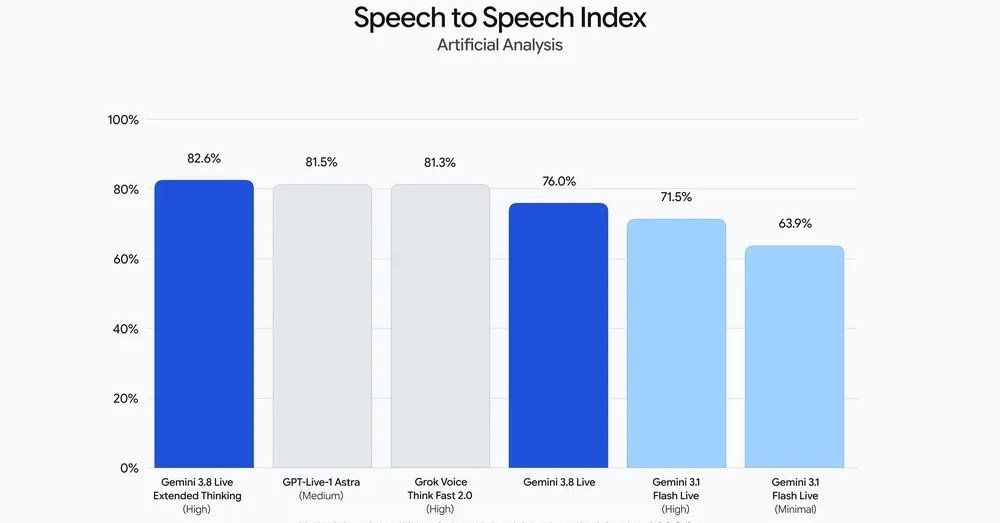
Google Deepmind released Gemini 3.8 Live and 3.8 Live Extended Thinking via the Gemini API and Google AI Studi…
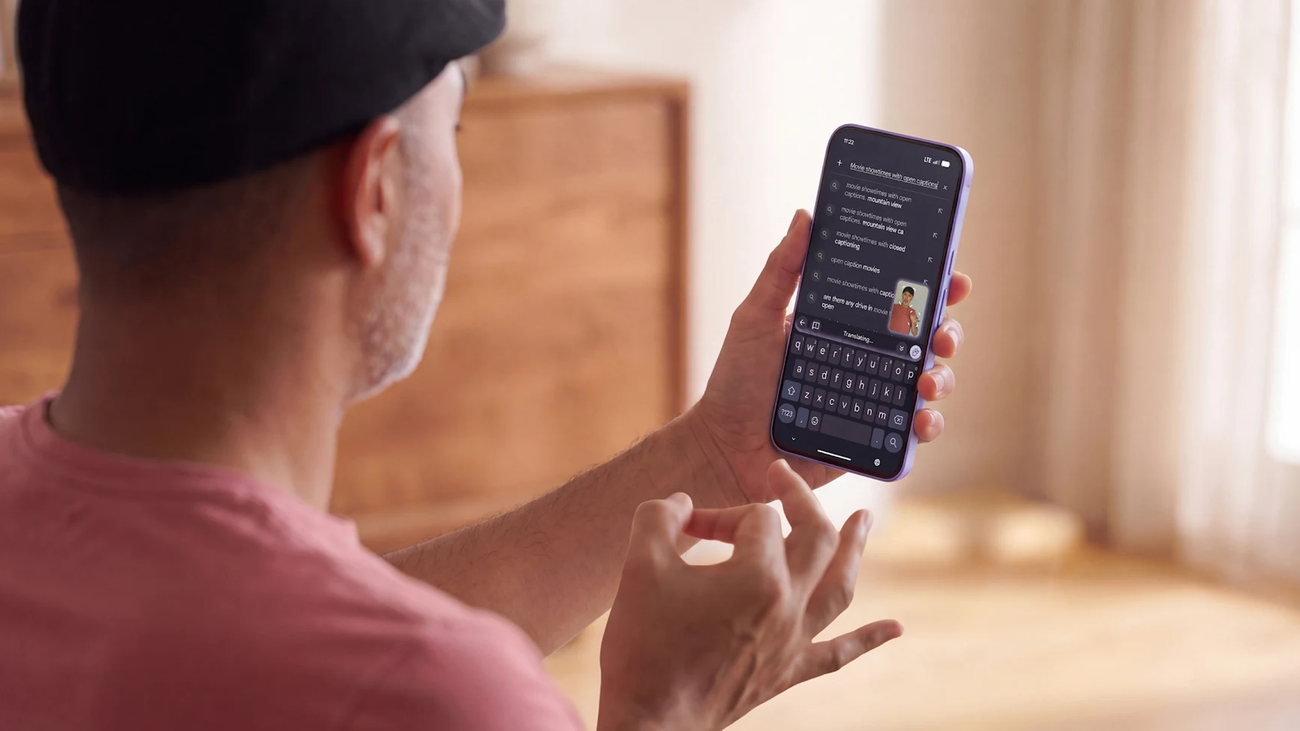
Google says its products now support more than 300 languages used by over 7 billion people, 86% of the global…
Nuance Labs, a Seattle startup led by ex-Apple researcher Fangchang Ma, closed a $50 million Series A led by L…
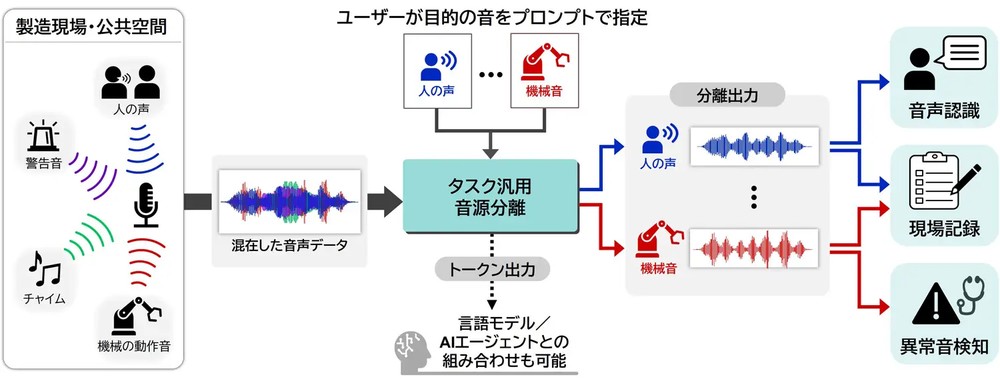
Mitsubishi Electric said it developed a single AI model, Task-Specific Sound Source Separation Technology, tha…
Get curated AI news from 100+ sources delivered daily to your inbox. Free to use.
60,000+ monthly readers
Get Started FreeFree · 30 seconds with Google · unsubscribe anytime

