AIToday

Today's AI, for Today's work.

Start free60,000+ monthly readers

Latest AI News

Earlier

TypeWhisper 1.4 release candidate adds unified workflows, system-wide dictation, and support for ten transcription engines on macOS

TypeWhisper 1.4 is the current release-candidate line for macOS, featuring system-wide dictation, file transcr…

Hacker NewsMay 9, 2026

Dikaletus: open-source meeting agent script automates audio recording, transcription, and note generation using Mistral AI

The Meeting Agent is a script that records audio from microphone and speaker outputs using PulseAudio and FFmp…
Hacker NewsMay 9, 2026

OpenAI launches GPT-Realtime-2, GPT-Realtime-Translate, and GPT-Realtime-Whisper voice models in Realtime API with expanded context and reasoning controls

OpenAI released three streaming audio models: GPT-Realtime-2 (a native speech-to-speech model for voice agents…
Latent SpaceMay 8, 2026

OpenAI releases GPT-Realtime-2 voice model with reasoning capabilities, plus live translation and transcription models

OpenAI shipped three new voice models: GPT-Realtime-2 (for reasoning and real-time conversation), GPT-Realtime…

THE DECODERMay 7, 2026

Google Home gets Gemini 3.1 voice assistant with improved reasoning for multi-step commands and expands Ask Home chatbot to web interface

Google rolled out Gemini 3.1 to Google Home smart speakers, initially available to early access users

Ars Technica AIMay 5, 2026

ElevenLabs reveals new investors in $500 million Series D, including BlackRock, NVIDIA, and celebrity backers; company surpassed $500 million in ARR and reached $11 billion valuation

ElevenLabs announced additional investors in its Series D fundraise first announced in February, including ins…

TechCrunch AIMay 5, 2026

InterviewDen launches free AI voice mock interviews for software engineering, consulting, banking, and quantitative finance roles.

InterviewDen offers live voice and text mock interviews that listen, speak, and grade responses

Hacker NewsApr 29, 2026

AWS publishes guide for migrating text agents to voice assistants using Amazon Nova 2 Sonic

AWS published a blog post exploring how to convert a traditional text agent into a conversational voice assist…

Amazon AI BlogApr 28, 2026

Arietta Voice: open-source local-first framework for building wake-word-driven voice assistants on Apple Silicon Macs

Arietta Voice combines local speech-to-text (Moonshine), text-to-speech (Kokoro), turn detection (Silero VAD a…

Hacker NewsApr 28, 2026

VoiceGoat: Open-source vulnerable voice agent platform for security training released on GitHub

VoiceGoat is a modular platform designed for security practitioners to practice exploiting voice-based AI syst…

Hacker NewsApr 28, 2026

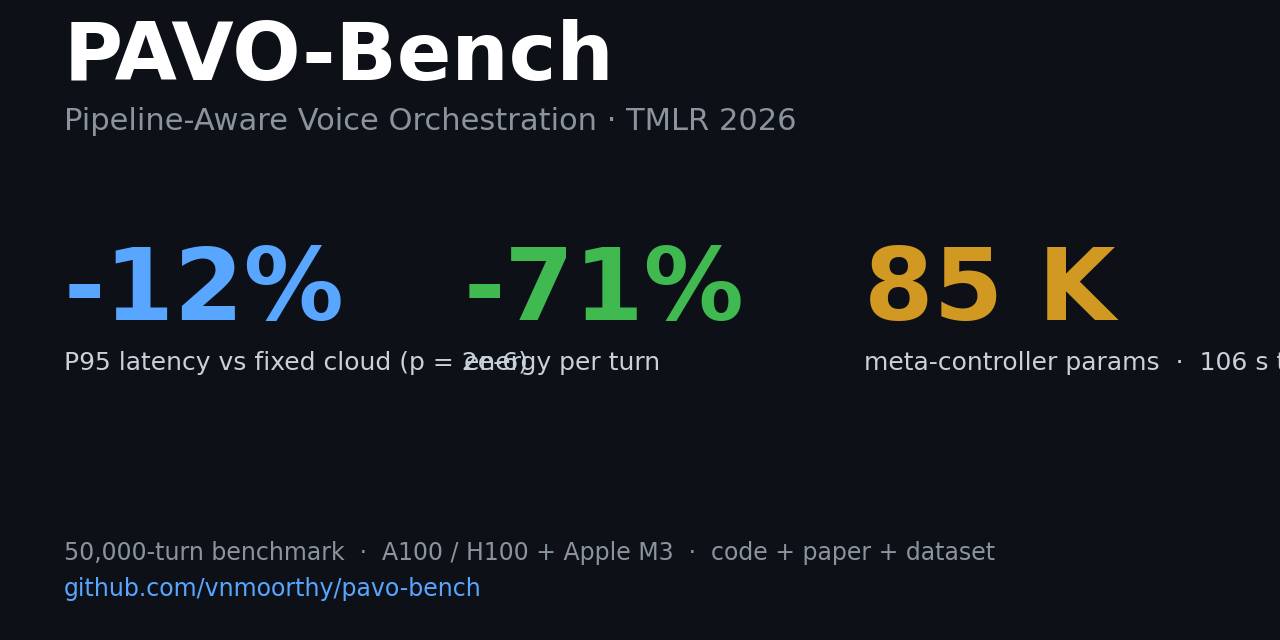
PAVO: an 85,041-parameter router for voice pipelines cuts P95 latency 10.3% and energy 71% versus fixed-cloud, trained via PPO in 106 seconds on a 50,000-turn benchmark.

Researchers at University of Pennsylvania and Google released PAVO-Bench, a 50,000-turn voice interaction data…
Hacker NewsApr 28, 2026

Microsoft VibeVoice ASR integrated into Hugging Face Transformers; voice AI framework now supports 60-minute speech recognition in single pass

VibeVoice-ASR, a speech-to-text model, is now part of a Transformers release and available directly through th…

Hacker NewsApr 28, 2026

Canonical plans to add AI features to Ubuntu Linux throughout 2026, prioritizing model transparency and local inference

Jon Seager, VP of engineering at Canonical, shared a blog post on Monday detailing plans to add AI features to…
The Verge AIApr 27, 2026

ComfyUI raises $30M at $500M valuation, giving creators manual control over AI-generated images, videos, and audio

ComfyUI, a startup building AI creation tools, closed a $30 million funding round that values the company at $…

TechCrunch AIApr 24, 2026

Over 50% of American workers now use AI daily — but most are experimenting quietly, not following influencer tutorials

A LessWrong author surveyed their own AI usage patterns and found themselves using AI assistance for hours eve…

LessWrong AIApr 21, 2026

New text-to-speech platform TTS.ai launches with minimal early traction on Hacker News

TTS.ai is a new text-to-speech service that was shared on Hacker News

Hacker NewsApr 18, 2026

Developer launches PrivaKit, a privacy-first AI workspace that runs entirely in the browser using WebGPU to eliminate cloud API risks for sensitive document processing.

PrivaKit uses transformers.js, Whisper, and WebGPU to perform AI tasks like transcription, OCR, and image proc…

Hacker NewsApr 18, 2026

Sony Music sues Udio for allegedly scraping YouTube music to train its AI music generation model without licensing.

Sony Music filed a lawsuit against Udio, claiming the AI music startup used stream ripping to extract audio fr…

Hacker NewsApr 15, 2026

Google's Gemini 3.1 Flash now includes native text-to-speech capabilities for faster audio generation

Gemini 3.1 Flash model adds integrated text-to-speech (TTS) functionality

Simon Willison's WeblogApr 15, 2026

Google rolls out Gemini 3.1 Flash TTS across its product suite, bringing more expressive and natural AI-generated speech capabilities to users.

Gemini 3.1 Flash TTS is now available across multiple Google products and services

Google AI BlogApr 15, 2026

Developer creates a 24/7 AI-powered YouTube livestream that generates unique songs every few minutes with lyrics describing the current time.

Fully automated system using Suno's API generates new AI songs in different genres every few minutes, with lyr…

Hacker NewsApr 14, 2026

Video essay explores concerns about AI music generation tools like Suno and their potential negative impacts on the music industry and creators

Suno is an AI music generation platform that raises questions about the future of music creation and industry…

Hacker NewsApr 12, 2026

Turn today's AI news into today's work.

The day's essentials from 100+ sources, delivered to Email, LINE, or Slack. Free to start.

60,000+ monthly readers
Get Started Free

OpenAI's ChatGPT voice mode reportedly uses a less capable underlying model than the text-based version

ChatGPT's voice interface appears to be powered by a weaker AI model compared to the standard text-based ChatG…

Simon Willison's WeblogApr 10, 2026

ByteDance introduces Seeduplex, a full-duplex voice AI system enabling natural two-way conversations without turn-taking delays.

Seeduplex represents ByteDance's advancement in conversational AI, allowing simultaneous speaking and listenin…

Hacker NewsApr 10, 2026

New speech recognition benchmark reveals academic tests miss real-world challenges like custom vocabulary that matters most to users

Contextual Earnings-22 dataset created to address gap between academic benchmarks and actual industrial speech…

arXiv cs.CLApr 10, 2026

Discrete speech units struggle to preserve lexical tone information in Mandarin and Yorùbá despite SSL models encoding it naturally

Self-supervised learning (SSL) models successfully capture tone information in their latent representations, b…

arXiv cs.CLApr 10, 2026

ElevenLabs expands its voice AI capabilities with local deployment options for enterprise customers

ElevenLabs now offers on-premise deployment, allowing enterprises to run voice AI solutions within their own i…

ElevenLabs BlogApr 9, 2026

Microsoft executives acknowledge voice AI technology requires significant advancement to support the company's enterprise artificial intelligence strategy.

Microsoft identifies improved voice understanding as a critical gap in its AI development roadmap

Yahoo Finance AIApr 9, 2026

Gemma 4 26BA4B achieves perfect multilingual tool-calling performance in self-hosted voice assistant testing

User reports Gemma 4 26BA4B as first model to achieve 100% success rate in multilingual tool-calling tests acr…

r/LocalLLaMAApr 3, 2026

Miravoice secures $6.3M in seed funding to automate phone survey interviews using AI voice agents

Miravoice uses AI voice agents to conduct long-form phone surveys autonomously

Crunchbase News AIApr 3, 2026

New Thiomi Dataset provides over 601,000 text annotations and 385,000 audio recordings across ten African languages to advance low-resource language AI models.

Dataset covers ten African languages including Swahili, Kikuyu, Wolof, Somali, and Fulani across four language…

arXiv cs.CLApr 1, 2026

EchoMind launches AI-powered voice notes app on Apple App Store for intelligent audio recording and transcription

New iOS app EchoMind (ID: 6760428216) available on Apple App Store enabling users to record and process voice…

Hacker NewsMar 31, 2026

Irish pubs cut Guinness prices after man uses AI to survey 3,000 bartenders on pricing

A 37-year-old used voice AI and Anthropic's Claude to conduct a large-scale price survey of Guinness across Ir…

Fortune AIMar 30, 2026

AI music generation is transforming the industry while raising concerns about artist displacement, authenticity, and the need for better labeling and detection.

AI has penetrated all aspects of music production, from sampling and demo recording to playlist curation and d…

The Verge AIMar 30, 2026

Suno's v5.5 update prioritizes user control with new voice customization and personalization features for AI music generation.

Suno released v5.5, its biggest update yet, shifting focus from improving audio fidelity to giving users more…

The Verge AIMar 28, 2026

Guide shows how to run OpenAI's Whisper speech recognition model locally on Mac computers without cloud dependencies

Whisper AI can be installed and run directly on Mac devices for private, offline speech-to-text processing

Hacker NewsMar 28, 2026

Microsoft's VibeVoice 9B achieves best open-source medical speech recognition at 8.34% WER, though it requires substantial computational resources and processing time.

Microsoft VibeVoice-ASR 9B now leads open-source models for medical speech-to-text with 8.34% WER, nearly matc…

r/LocalLLaMAMar 27, 2026

New method enables speech evaluation in low-resource languages by eliminating the need for precise phoneme timing alignment

Researchers propose a solution to adapt weakly-supervised ASR models for speech evaluation tasks that traditio…
arXiv cs.CLMar 27, 2026

Apple's iOS 27 will let users choose between multiple AI chatbots like Google Gemini and Claude to power Siri, moving beyond exclusive ChatGPT integration.

iOS 27 introduces a new "Extensions" system allowing users to select and manage third-party AI chatbots for Si…

The Verge AIMar 27, 2026

Google launches Gemini 3.1 Flash Live, a conversational audio AI that raises concerns about distinguishing human-AI interactions

Google is rolling out Gemini 3.1 Flash Live across Search, Gemini, and developer tools today

Ars Technica AIMar 26, 2026

Amazon Polly launches bidirectional streaming API to enable real-time speech synthesis for conversational AI applications powered by large language models.

New Bidirectional Streaming API allows simultaneous text input and audio output, eliminating wait times for co…

Amazon AI BlogMar 26, 2026

Google launches Gemini 3.1 Flash Live to improve real-time audio conversation quality and reliability in AI interactions

Google released Gemini 3.1 Flash Live, an updated model designed to make audio-based AI conversations more nat…

Hacker NewsMar 26, 2026

Google launches Gemini 3.1 Flash Live to enhance audio AI capabilities with improved naturalness and reliability across its product suite

Gemini 3.1 Flash Live is now available across Google's product ecosystem

Google AI BlogMar 26, 2026

Developer's 3-month real-world comparison reveals Claude significantly outperforms ChatGPT and Gemini for professional coding tasks.

Claude excels at complex coding work with its 200k context window, allowing developers to paste entire files p…

r/artificialMar 25, 2026

Today's AI, for Today's work.

Get curated AI news from 100+ sources delivered daily to your inbox. Free to use.

60,000+ monthly readers

Get Started Free

Free · 30 seconds with Google · unsubscribe anytime